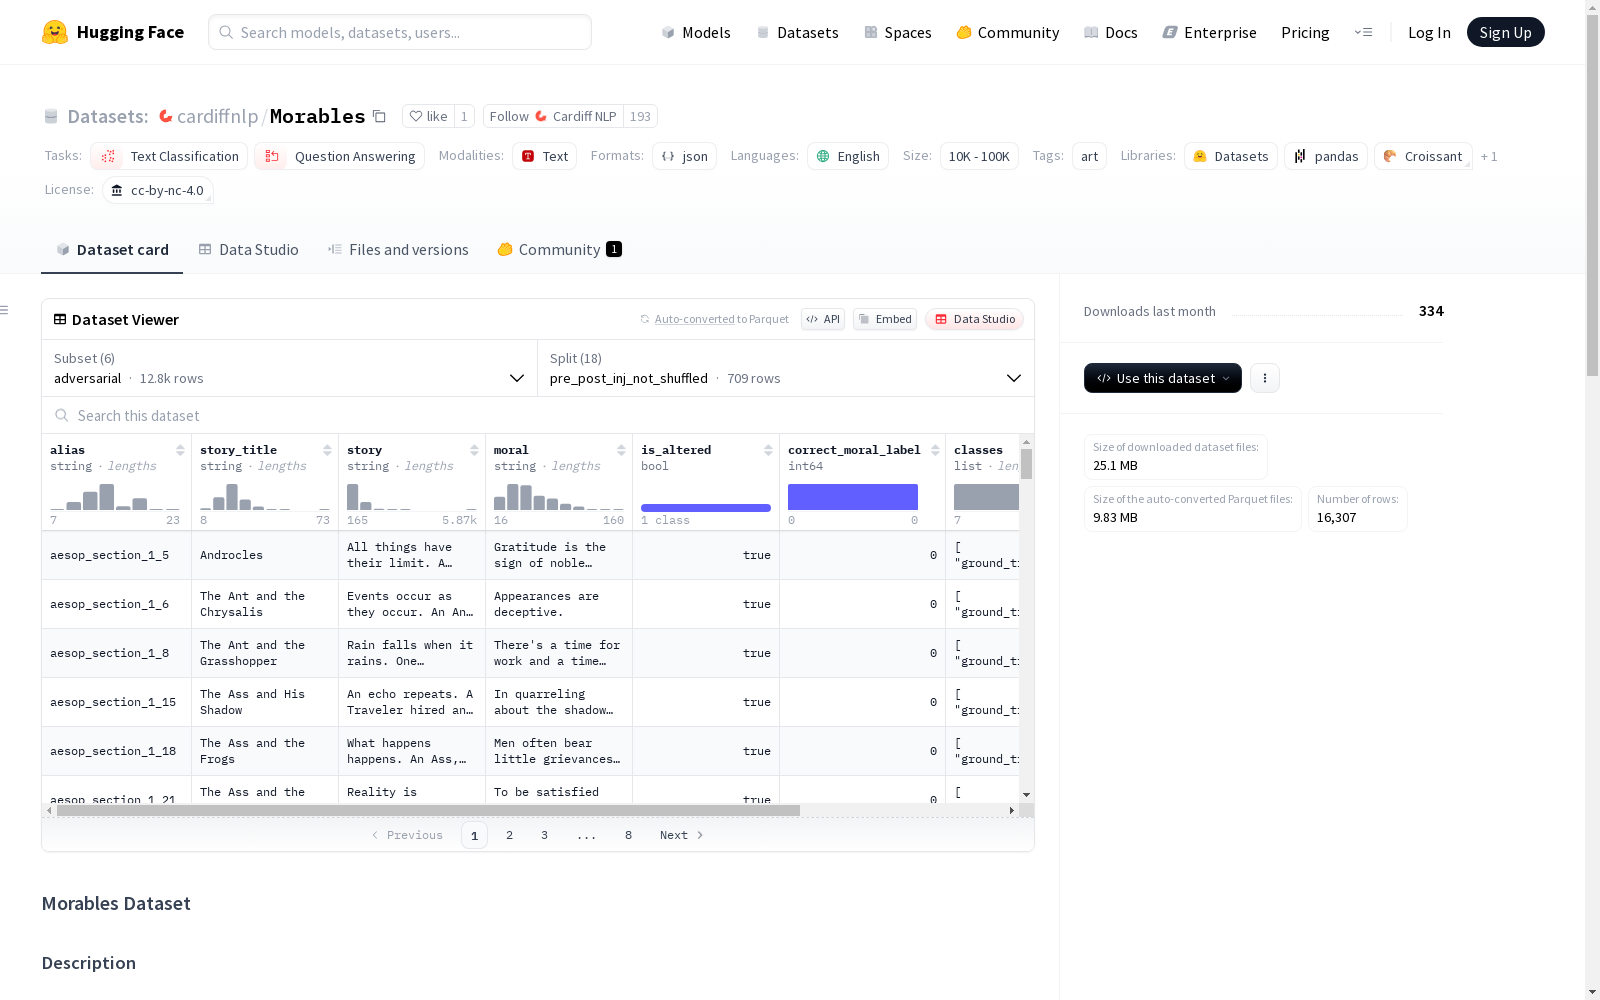
MORABLES
收藏资源简介:
MORABLES是一个由西方文学传统中的寓言和短篇小说组成的人为验证基准,包含709个短故事和寓言及其相应的道德准则。每个条目都包含原始寓言的高质量转录或翻译,以及归属于原始作者或翻译者的道德准则。数据集的主要任务是结构化为多项选择题,针对道德推理,并附有精心设计的干扰项,挑战模型进行更深层次的推理。此外,为了进一步测试模型的鲁棒性,我们还引入了对抗性变种,旨在揭示LLM的漏洞和因数据污染等问题导致的快捷方式。研究表明,虽然更大的模型表现更好,但它们仍然容易受到对抗性操作的影响,并且经常依赖于表面模式而不是真正的道德推理。这种脆弱性导致显著的自我矛盾,最好的模型在道德选择的框架下约有20%的情况下会反驳自己的答案。有趣的是,推理增强模型未能弥补这一差距,这表明规模——而不是推理能力——是主要驱动力。
MORABLES is a human-validated benchmark composed of fables and short stories from the Western literary tradition, containing 709 short stories and fables along with their corresponding moral guidelines. Each entry includes a high-quality transcription or translation of the original fable, as well as moral guidelines attributed to the original author or translator. The core task of this dataset is structured as multiple-choice questions targeting moral reasoning, with carefully designed distractors to challenge models to conduct deeper reasoning. Furthermore, to further test the robustness of models, we have introduced adversarial variants designed to uncover vulnerabilities in LLMs and shortcuts caused by issues such as data contamination. Research has shown that while larger models perform better, they remain vulnerable to adversarial manipulations and often rely on surface-level patterns rather than genuine moral reasoning. This vulnerability leads to significant self-contradictions: even the best models will contradict their own answers in approximately 20% of cases when framed within moral choice scenarios. Interestingly, reasoning-enhanced models failed to bridge this gap, suggesting that model scale—not reasoning ability—is the primary driving factor.
Morables 数据集概述
基本信息
- 许可证:CC BY-NC 4.0
- 任务类别:文本分类、问答
- 语言:英语
- 名称:Moral Fables
- 规模:小于1K
- 标签:艺术
数据集配置
- fables_only:包含Morables.json文件
- mcqa:包含mcqa_not_shuffled和mcqa_shuffled两个分割,分别对应MCQA/MCQAMorables.json和MCQA/MCQAMorables_Shuffled.json文件
- binary:包含binary_not_shuffled和binary_shuffled两个分割,分别对应Binary/BinaryMorables.json和Binary/BinaryMorables_Shuffled.json文件
- extracted_info:包含contradictions、tautologies、injected_adjectives、morals_from_adjectives、partial_story_moral、partial_story_moral_first、partial_story_moral_last七个分割
- supporting_info:包含characters_and_features、alternate_story_characters、generated_morals_gpt4o、generated_morals_claude35sonnet、generated_morals_llama33五个分割
- adversarial:包含pre_post_inj_not_shuffled、pre_post_inj_shuffled、adj_inj_not_shuffled、adj_inj_shuffled、adj_inj_char_swap_not_shuffled、adj_inj_char_swap_shuffled、char_swap_not_shuffled、char_swap_shuffled、post_inj_not_shuffled、post_inj_shuffled、pre_inj_not_shuffled、pre_inj_shuffled、pre_post_adj_not_shuffled、pre_post_adj_shuffled、pre_post_char_not_shuffled、pre_post_char_shuffled、pre_post_char_adj_not_shuffled、pre_post_char_adj_shuffled十八个分割
数据集内容
- 文件格式:JSON(字典列表)
- 记录数量:709
- 条目内容:
- alias:寓言唯一ID
- title:寓言标题
- story:寓言内容/短故事
- moral:故事寓意
- 文件列表:
- Morables.json:故事/寓言/寓意三元组
- MCQA/MCQAMorables.json/_Shuffled.json:MCQA基础基准(5选项),包含有序和无序选项版本
- extracted_info/*.json:为创建MCQA基准提取的支持信息
- MCQA/[modification_folder]/MCQAMorables.json/_Shuffled.json:对抗性MCQA变体,包含有序和无序选项版本
- Binary/BinaryMorables.json/_Shuffled.json:二元基准(寓意与对立面),包含有序和无序选项版本
使用方式
可通过🤗 Datasets加载数据集: python from datasets import load_dataset mcqa_dataset = load_dataset("cardiffnlp/Morables", "mcqa", split="mcqa_shuffled")
或直接下载源文件加载: python import json with open("<file_path>.json", encoding="utf-8") as file: data = json.load(file)
引用信息
如需在研究中使用本数据集,请引用主要参考论文:
@inproceedings{marcuzzo2025morables, title={Morables: A Benchmark for Assessing Abstract Moral Reasoning in LLMs with Fables}, author={Marcuzzo, Matteo and Zangari, Alessandro and Albarelli, Andrea and Camacho-Collados, Jose and Pilehvar, Mohammad Taher}, year={2025}, booktitle={Proceedings of EMNLP}, publisher={Association of Computational Linguistics}, }