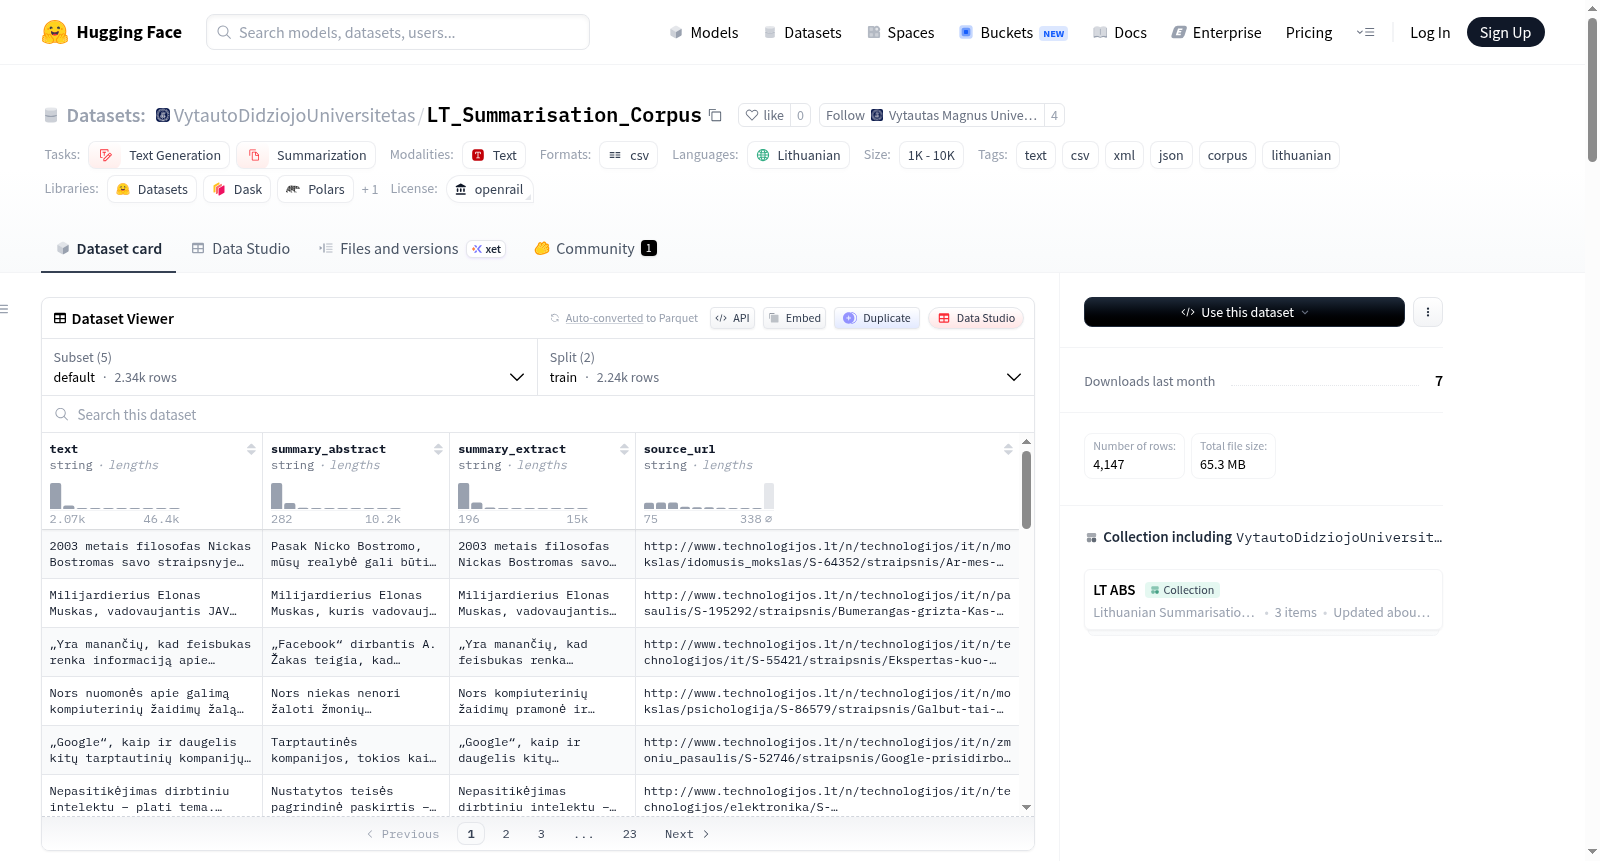
LT_Summarisation_Corpus
收藏资源简介:
立陶宛语摘要语料库是一个专门为立陶宛语自然语言处理任务设计的数据集,尤其侧重于文本摘要。该语料库包含2340个立陶宛语文本样本,每个样本都配有人工撰写的抽象摘要和抽取式摘要。数据覆盖四个专业领域:信息技术(IT)、法律、医学和新闻媒体,旨在支持技术性和通用性语域的摘要系统开发与评估。数据集以CSV、JSON和XML格式提供,总大小约为21 MB,包含训练集(2251个样本)和测试集(100个样本)。主要数据字段包括原文(`text`)、抽象摘要(`summary_abstract`)、抽取式摘要(`summary_extract`)以及领域类型(`type`)。数据来源于多个权威渠道,如IT博客、学术论文、法律信息系统、法院案例、匿名医疗文档以及新闻网站。语料库总词数超过170万,摘要词数总计约85万。该数据集适用于文本生成、摘要、语言建模、语法风格校正、语义搜索等多种NLP任务。数据集采用NewGenLTU OpenRAIL-D许可证发布,允许负责任的开放使用,但明确禁止用于歧视、武器开发、自动决策影响个人、虚假信息等用途。需要注意的是,语料库中新闻文本和文档占主导(分别约52%和38%),可能使下游模型偏向这些语域。本数据集由维陶塔斯·马格努斯大学和维尔纽斯大学在欧盟NextGenerationEU及立陶宛“新世代立陶宛”计划资助下创建。
The Lithuanian Abstract Corpus is a dataset specifically designed for Lithuanian natural language processing (NLP) tasks, with a particular focus on text summarization. This corpus contains 2,340 Lithuanian text samples, each paired with human-written abstractive summaries and extractive summaries. The data covers four professional domains: information technology (IT), law, medicine, and news media, aiming to support the development and evaluation of summarization systems for both technical and general linguistic registers. The dataset is provided in CSV, JSON, and XML formats, with a total size of approximately 21 MB, and is split into a training set (2,251 samples) and a test set (100 samples). Core data fields include the original text (`text`), abstractive summary (`summary_abstract`), extractive summary (`summary_extract`), and domain type (`type`). The data is sourced from multiple authoritative channels, such as IT blogs, academic papers, legal information systems, court cases, anonymized medical documents, and news websites. The total number of words in the corpus exceeds 1.7 million, with the total word count of the summaries reaching approximately 850,000. This dataset is applicable to a variety of NLP tasks including text generation, summarization, language modeling, grammatical style correction, and semantic search. The dataset is released under the NewGenLTU OpenRAIL-D license, permitting responsible open use while explicitly prohibiting applications such as discrimination, weapons development, automated decision-making that affects individuals, and disinformation. It should be noted that news texts and documents dominate the corpus (accounting for approximately 52% and 38% respectively), which may lead to downstream models being biased towards these registers. This dataset was created by Vytautas Magnus University and Vilnius University with funding from the EU NextGenerationEU and Lithuania's "New Generation Lithuania" program.
数据集概述:立陶宛语摘要语料库
基本信息
- 数据集名称:Lithuanian Summarisation Corpus(立陶宛语摘要语料库)
- 语言:立陶宛语(lt)
- 许可证:NewGenLTU OpenRAIL-D
- 数据集大小:1M 至 30M 条记录
- 数据格式:CSV、JSON、XML
- 总文件大小:21 MB(训练集 20.3 MB,测试集 0.7 MB)
- 总文本数量:2,340 篇(训练集 2,251 篇,测试集 100 篇)
数据集构成
该语料库包含立陶宛语文本及其人工编写的抽象式摘要和抽取式摘要,涵盖四个主题领域:
| 领域 | 描述 | 来源 |
|---|---|---|
| IT(信息技术) | 信息技术文章 | IT 博客、学生学士/硕士论文、VU IT 研究期刊 |
| 法律(teisė) | 法律文档 | 立陶宛法院信息系统、法律登记册、最高法院判例、法律出版物 |
| 医学(medicina) | 医学文本 | 国家数据局提供的匿名化药房文件、医生诊断 |
| 媒体(žiniasklaida) | 新闻文章 | lrt.lt 新闻网站 |
数据分布
| 文本类型 | 文本词数 | 抽象式摘要词数 | 抽取式摘要词数 | 文本数量 |
|---|---|---|---|---|
| IT | 344,710 | 65,403 | 89,131 | 689 |
| 法律 | 668,276 | 155,893 | 224,446 | 533 |
| 医学 | 371,611 | 64,980 | 89,570 | 550 |
| 媒体 | 354,012 | 66,315 | 91,714 | 568 |
| 总计 | 1,738,609 | 352,591 | 494,861 | 2,340 |
主要字段
text:原始文本(字符串)summary_abstract:抽象式摘要(字符串)summary_extract:抽取式摘要(字符串)type:文本所属领域类型(字符串)
数据配置文件
数据集提供以下配置,每个配置包含训练集和测试集:
- default:所有领域数据,训练集为
csv/train/*.csv,测试集为csv/test/*.csv - it:仅信息技术领域,训练集
csv/train/it.csv,测试集csv/test/it.csv - teisė:仅法律领域
- medicina:仅医学领域
- žiniasklaida:仅媒体领域
预期用途
该数据集适用于以下立陶宛语 NLP 和 AI 任务:
- 文本生成
- 文本摘要
- 语言建模
- 语法与风格校正
- 语义搜索
- 文本分析
- 虚拟助手
- 其他语言技术应用
限制与偏差
- 语料库中新闻门户文本占 52%、法律文档占 38%,这可能导致下游模型偏向这些领域和语体。
- 开发者已尽力清洗数据、减少 OCR 错误和重复内容,但用户应知晓上述领域分布偏差。
引用信息
请引用为: Vytautas Magnus University and Vilnius University. 2026. Abstract Corpora for Artificial Intelligence. Hugging Face. https://huggingface.co/datasets/VytautoDidziojoUniversitetas/LT_Summarisation_Corpus