medmentions-ner
收藏资源简介:
MedMentions BioNER数据集是一个定制的预处理版本,专门用于生物医学命名实体识别(NER)任务。该数据集基于MedMentions数据集,包含128种来自UMLS语义类型的实体类别,采用BIO标注方案。数据集以英文为主要语言,分为训练集、验证集和测试集,比例分别为80%、10%和10%。每个句子由一系列单词和对应的BIO标签组成。
The MedMentions BioNER dataset is a customized preprocessed version specifically designed for biomedical named entity recognition (NER) tasks. Derived from the original MedMentions dataset, it includes 128 entity categories from UMLS semantic types and adopts the BIO annotation scheme. Taking English as its primary language, the dataset is split into training, validation and test sets with a ratio of 80%, 10% and 10% respectively. Each sentence consists of a sequence of words and their corresponding BIO tags.
MedMentions BioNER (Custom Processed) 数据集概述
数据集基本信息
- 任务类型: 生物医学命名实体识别(NER)
- 数据来源: MedMentions
- 语言: 英语
- 实体类型: 128个基于UMLS语义类型的实体类别
- 标注格式: BIO标记方案
数据集结构
-
特征列:
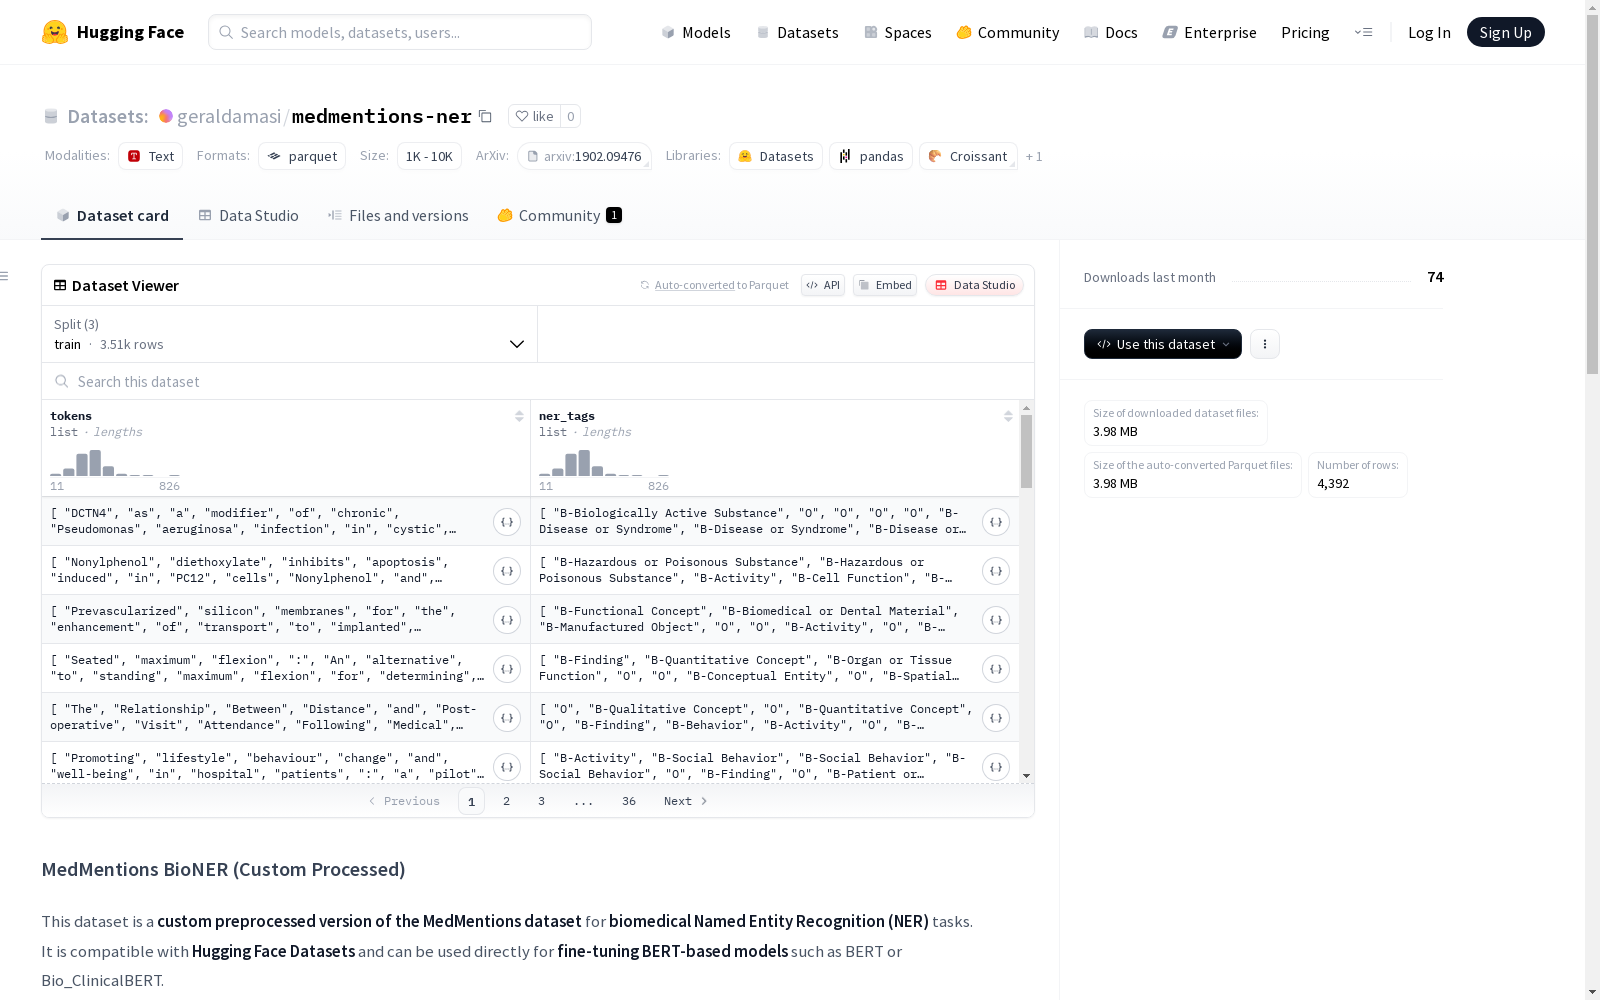
tokens: 句子中的单词列表ner_tags: 每个单词对应的BIO格式标签列表
-
数据划分:
train: 3513个样本(80%)validation: 439个样本(10%)test: 440个样本(10%)
数据示例
json { "tokens": ["DCTN4", "as", "a", "modifier", "of", "chronic", "Pseudomonas", "aeruginosa", "infection"], "ner_tags": ["B-Biologically Active Substance", "O", "O", "O", "O", "B-Disease or Syndrome", "B-Disease or Syndrome", "B-Disease or Syndrome", "B-Disease or Syndrome"] }
技术规格
- 总大小: 25,924,360字节
- 下载大小: 3,982,978字节
- 兼容性: 可直接用于Hugging Face Datasets,适合微调BERT类模型(如BERT或Bio_ClinicalBERT)
引用信息
bibtex @article{medmentions, title={MedMentions: A Large Biomedical Annotated Corpus with UMLS Concepts}, author={Mohan, Sunil and Li, Donghui}, journal={arXiv preprint arXiv:1902.09476}, year={2019} }