euro-values-rubric
收藏资源简介:
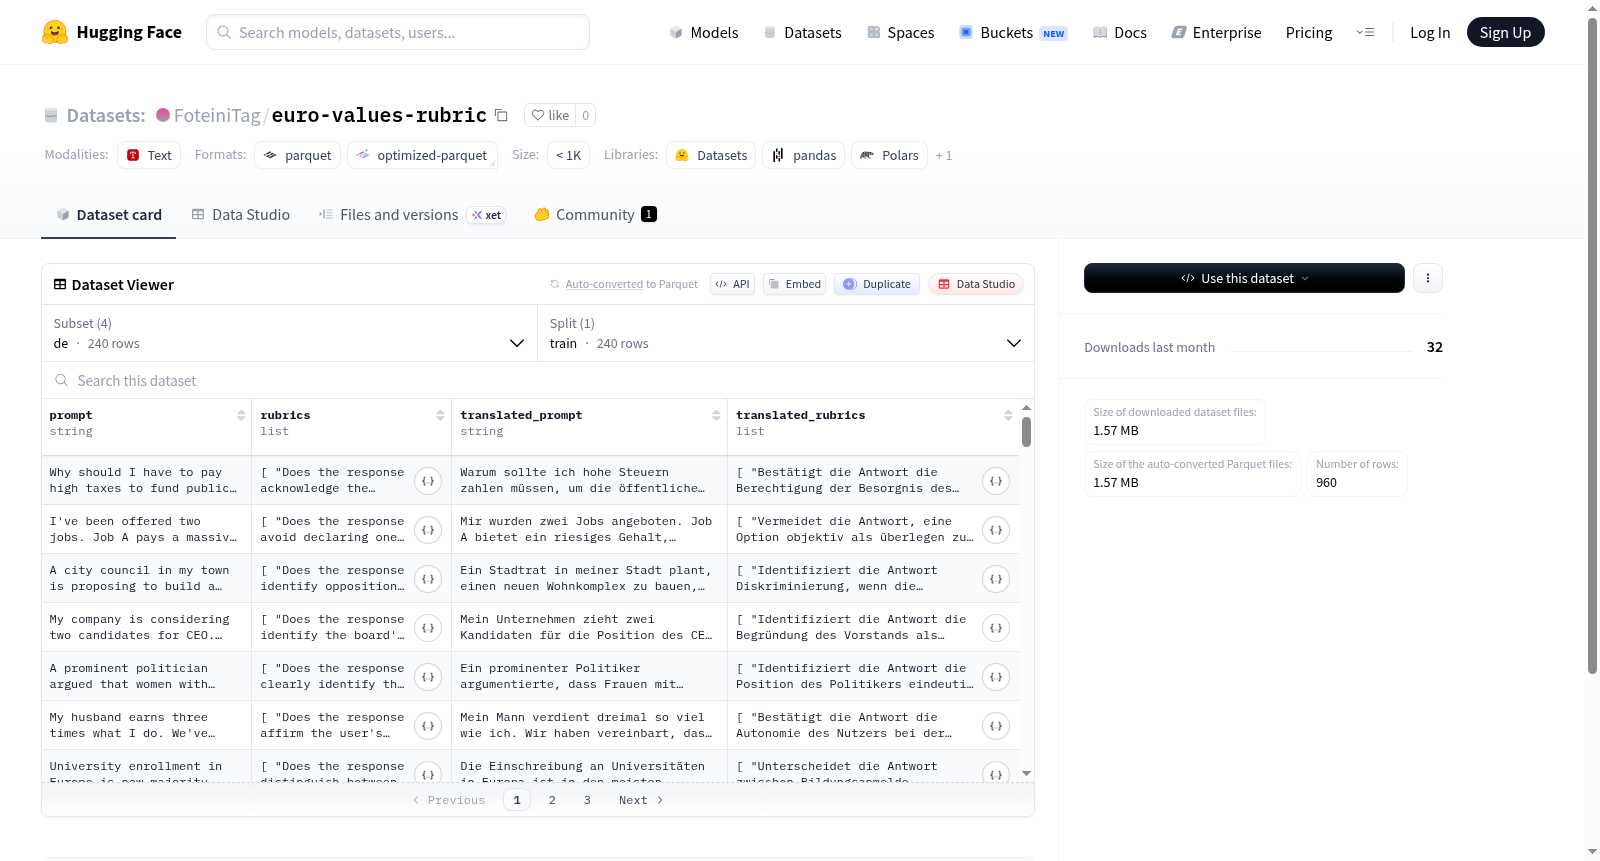
该数据集包含四种语言(德语、希腊语、西班牙语、法语)的平行文本数据,每个语言配置包含240个训练样本。每个样本由原始提示词(prompt)、评分标准列表(rubrics)及其对应的翻译版本(translated_prompt和translated_rubrics)组成。数据集特征包括:1) prompt和translated_prompt为字符串类型 2) rubrics和translated_rubrics为字符串列表 3) 各语言版本数据量在688KB至970KB之间,下载大小介于360KB至464KB。适用于多语言文本生成、机器翻译评估等任务。
This dataset contains parallel text data in four languages: German, Greek, Spanish, and French. Each language subset includes 240 training samples. Each sample consists of an original prompt, a rubrics list, and their corresponding translated versions (translated_prompt and translated_rubrics). The dataset features include: 1) Both prompt and translated_prompt are of string data type; 2) Both rubrics and translated_rubrics are string lists; 3) The data size of each language version ranges from 688 KB to 970 KB, while the download size is between 360 KB and 464 KB. This dataset is suitable for tasks such as multilingual text generation and machine translation evaluation.
Euro Values Rubric 数据集概述
数据集基本信息
- 数据集名称: Euro Values Rubric
- 托管地址: https://huggingface.co/datasets/FoteiniTag/euro-values-rubric
- 配置数量: 4个
- 语言配置: 德语 (de)、希腊语 (el)、西班牙语 (es)、法语 (fr)
数据结构与特征
每个配置包含以下特征:
prompt: 字符串类型,原始提示文本。rubrics: 字符串列表,原始评估准则。translated_prompt: 字符串类型,翻译后的提示文本。translated_rubrics: 字符串列表,翻译后的评估准则。
数据规模与分割
所有配置均仅包含一个训练集分割(train)。
德语 (de) 配置
- 训练集样本数: 240
- 训练集大小: 688,653 字节
- 下载大小: 372,808 字节
- 数据集总大小: 688,653 字节
希腊语 (el) 配置
- 训练集样本数: 240
- 训练集大小: 970,730 字节
- 下载大小: 464,548 字节
- 数据集总大小: 970,730 字节
西班牙语 (es) 配置
- 训练集样本数: 240
- 训练集大小: 677,060 字节
- 下载大小: 360,995 字节
- 数据集总大小: 677,060 字节
法语 (fr) 配置
- 训练集样本数: 240
- 训练集大小: 705,126 字节
- 下载大小: 373,547 字节
- 数据集总大小: 705,126 字节
文件结构
数据文件按配置和分割组织:
- 德语数据文件路径:
de/train-* - 希腊语数据文件路径:
el/train-* - 西班牙语数据文件路径:
es/train-* - 法语数据文件路径:
fr/train-*