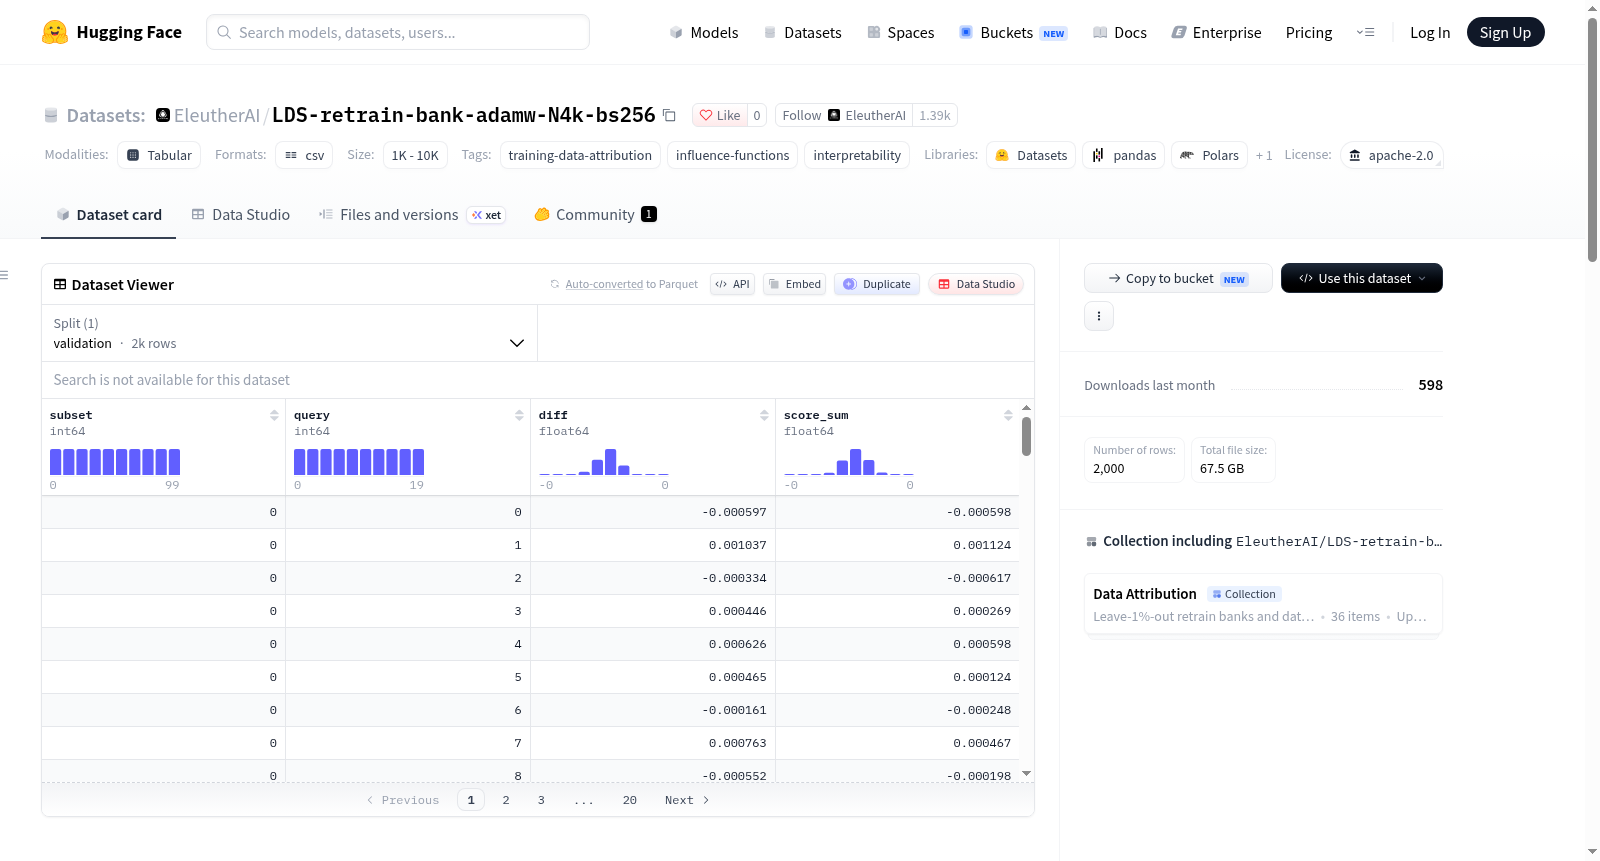
metasmoothness-bank-plan_adam_eps1e17_4k_bs256
收藏资源简介:
该数据集(名为“plan_adam_eps1e17_4k_bs256”)由EleutherAI发布,专为训练数据归因(training data attribution)研究设计。它包含100个完全重新训练的语言模型,每个模型均为GPT-2(gpt2)架构,在相同的4,000文档语料上微调,但每个模型随机剔除1%(40个文档)的不同子集。所有模型使用相同的种子和数据顺序,重训练过程在相同环境下是确定性的,因此模型差异仅来自剔除的文档。数据集提供了地面真实值文件(validation.csv),记录每个子集对每个查询(query)造成的损失变化(diff),以及子集信息(subsets.json)和精确的训练配置(config.yaml)。此外,还包含基于MAGIC、EK-FAC和metasmoothness等方法的评分器评估结果(LDS指标和tail-filter delta)。该数据集可用于评估新的归因方法,无需重新训练模型。LDS指标定义为每个查询上预测子集影响与实测diff之间的Spearman相关系数的平均值。数据集采用Apache-2.0许可证。
This dataset (named "plan_adam_eps1e17_4k_bs256") is released by EleutherAI, specifically designed for training data attribution research. It contains 100 fully retrained language models, each with GPT-2 (gpt2) architecture, fine-tuned on the same 4,000-document corpus, but each model randomly drops a different subset of 1% (40 documents). All models use the same seed and data order, and the retraining process is deterministic under the same environment, so the model differences come only from the dropped documents. The dataset provides a ground truth file (validation.csv) recording the loss change (diff) caused by each subset for each query, along with subset information (subsets.json) and the exact training configuration (config.yaml). Additionally, it includes evaluator scores based on methods such as MAGIC, EK-FAC, and metasmoothness (LDS metric and tail-filter delta). This dataset can be used to evaluate new attribution methods without retraining models. The LDS metric is defined as the average Spearman correlation coefficient between predicted subset influence and measured diff for each query. The dataset is licensed under Apache-2.0.
数据集概述
该数据集由EleutherAI发布,许可证为Apache 2.0,用于训练数据归因(training-data-attribution)和影响函数(influence-functions)研究。
核心内容
- 包含100个完整重新训练的语言模型,并非仅提供分数。
- 每个模型基于GPT-2(gpt2),在相同的4,000篇文档语料库上进行微调,但每次随机剔除不同的1%(即40篇文档)。
- 所有模型使用相同种子和数据顺序,仅因剔除文档不同而存在差异。重训练在单一环境内是确定性的。
主要文件结构
| 路径 | 说明 |
|---|---|
retrained/base/ |
未剔除任何文档的微调基础模型 |
retrained/subset_*/ |
100个模型,每个缺失语料库中不同的1%文档 |
validation.csv |
真实标签(ground truth):每个(子集,查询)组合因剔除导致的损失变化 |
subsets.json |
每个子集剔除的文档ID列表 |
config.yaml |
精确的训练配置文件 |
filter_proponents_*/ |
尾部过滤结果:移除评分器排名前1%文档后的损失变化 |
使用方式
可通过huggingface_hub的snapshot_download下载完整数据集,并通过validation.csv获取真实标签。用户可对自己提出的归因方法进行评分,然后将预测影响与测量到的diff值进行相关分析。
该数据集上测得的指标
| 指标 | 值 |
|---|---|
| MAGIC LDS | 0.9295 |
| EK-FAC LDS | 0.3975 |
| metasmoothness | 0.9946 |
| MAGIC尾部过滤delta | 0.02505 nats |
| EK-FAC尾部过滤delta | 0.01153 nats |
| 随机对照尾部过滤delta | 0.00004 nats |
其中LDS表示每个查询的平均Spearman相关性,衡量预测子集影响与实测diff之间的关联。
数据来源与训练配置
- 优化器:
adamw,学习率:0.0001,批次大小:256,训练轮数:2,步数:32,随机种子:42 - 语料库:smollm2,共4,000篇文档
- 注意:所有重训练在同一GPU类型上完成,因为混合GPU类型会导致重训练模型产生足以影响LDS约0.05的变化,这一变化幅度大于多数待测效应。
该数据集由bergson工具生成,其核心价值在于可复用于任何leave-k-out归因研究,无需额外进行重训练即可评估新的归因方法。