JiashengGuo/ExpressEdit
收藏资源简介:
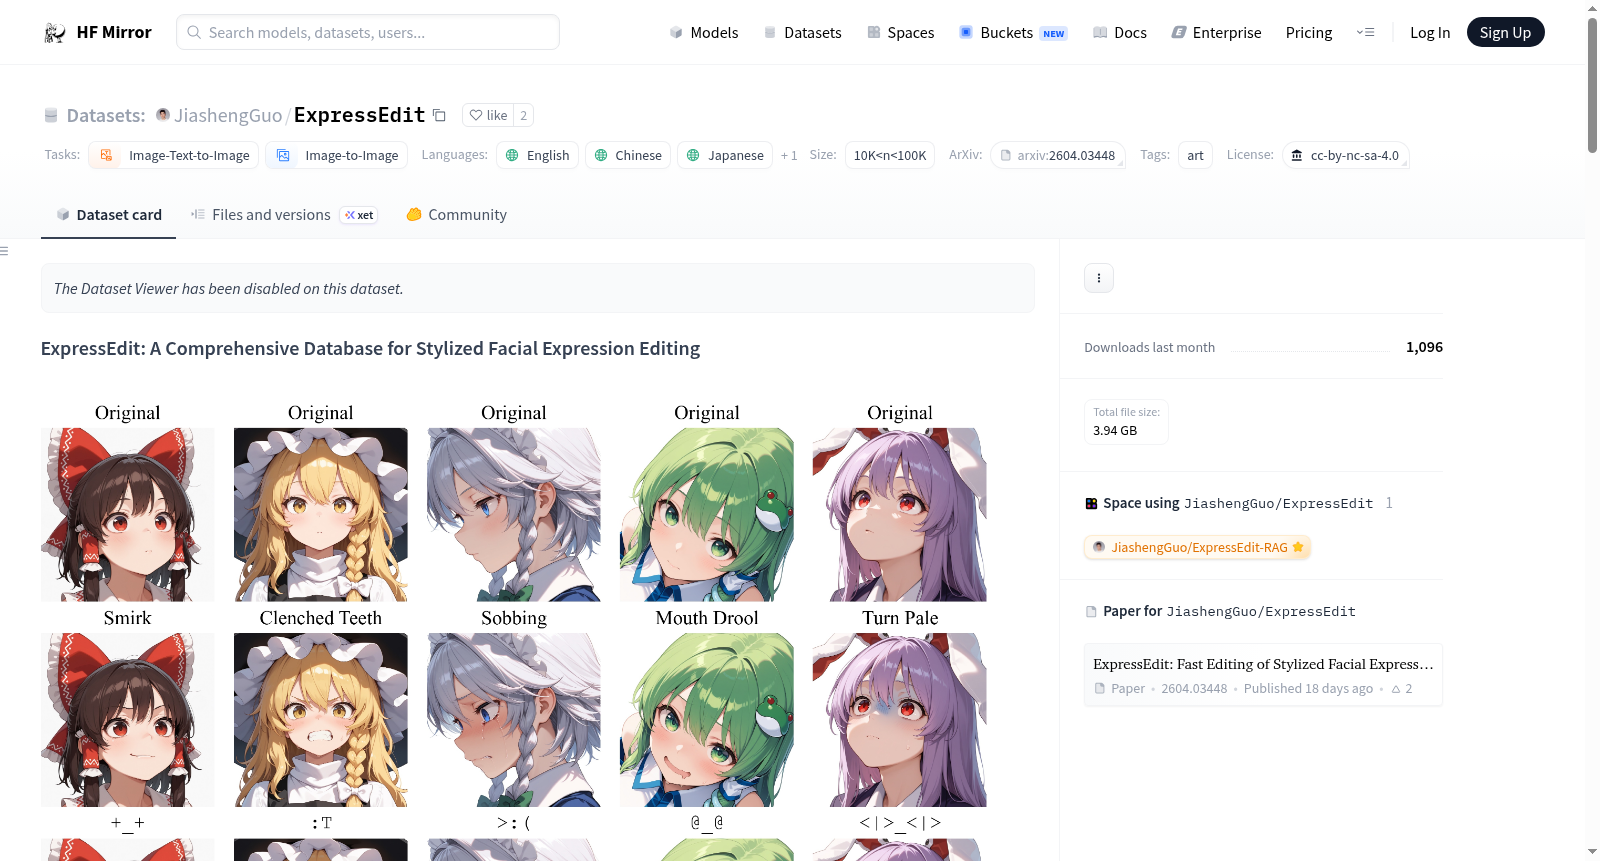
--- license: cc-by-nc-sa-4.0 task_categories: - image-text-to-image - image-to-image language: - en - zh - ja - ko tags: - art pretty_name: ExpressEdit size_categories: - 10K<n<100K viewer: false --- # ExpressEdit: A Comprehensive Database for Stylized Facial Expression Editing  ## 🚀 Interactive Demo We provide a minimalist Retrieval-Augmented Generation (RAG) demo hosted on Hugging Face Spaces. You can input your own creative story snippet, and the system will retrieve the most matching expression tag from this database. 👉 **[Try the ExpressEdit RAG Demo Here](https://huggingface.co/spaces/JiashengGuo/ExpressEdit-RAG)** ## 📋 Dataset Summary Facial expressions of characters are a vital component of visual storytelling. While current AI image editing models hold promise for assisting artists in the task of stylized expression editing, these models introduce global noise and pixel drift into the edited image, preventing the integration of these models into professional image editing software and workflows. Furthermore, models primarily rely on textual prompts for image generation, which means users have to come up with detailed descriptions of expressions. This requirement on the prompt quality poses a cognitive burden for users and slows down the creation process. **ExpressEdit** provides a solution by mapping free-form narrative intents to structured generation tags. To support the generation of diverse expressions according to different narrative needs, we compile a comprehensive expression database of 135 expression tags enriched with example stories and images designed for retrieval-augmented generation. This dataset accompanies the ExpressEdit Photoshop plugin, an open-source tool for fast and clean stylized expression editing. ## 🖼️ Dataset Composition The dataset contains a rich combination of text, tags, and generated images: ### Expression Tags * **Base Tags:** We obtained the expression tags from the Danbooru official website of face tags and eye tags. We manually choose the tags that can assist expression generation, filtering out explicit content, to obtain **135 expression tags**. * **Definitions:** The definition for each expression tag was obtained from the official Danbooru website, specifying when the tag should and should not be applied. * **Alternative Tags:** We also include alternative tags, which are Pixiv tags for each expression, or translations of the expression tag into Chinese, Japanese, or Korean. A total of **332 alternative tags** were obtained in this process. * **Transformation-Free Flag:** Each tag is annotated with a flag indicating whether it can be reliably edited without applying Photoshop transformations such as Liquify. 100 out of 135 tags are transformation-free; the remaining 35 require quick manual operations. ### Example Stories * To inspire users and facilitate the retrieval process, we generated 5 example stories for each tag with Gemini 3 Flash. * The process is repeated for Chinese, English, Japanese, and Korean. * The process results in **2,700 short stories** (135 tags × 5 stories × 4 languages). ### Example Images * Example images were automatically generated based on 5 original character images. * For each expression tag, we repeat the generation 5 times with different random seeds, resulting in **3,375 total edited images**. ## 🎯 Applications There are two primary use cases for the ExpressEdit dataset: ### Retrieval-Augmented Generation (RAG) Given the database, a user can conveniently use a VLM to retrieve the tag that is relevant to their stories, ideas, or specific editing instructions. By converting free-form user intent into structured expression tags, ExpressEdit refines the prompt into a format suitable for the image generation model, mitigating the prompt sensitivity of multi-modal generative models that potentially degrades image quality.  ### Reference for Expression Stylization The 3,375 image results can be used as a visual benchmark for how specific Danbooru tags influence the style, eye placement, and mouth shape of various 2D characters across different random seeds. ## 🏗️ Dataset Structure The repository is organized into image folders and text-based JSONL files: ### Image Data * **`results/` Directory:** Contains the 3,375 generated `.png` images. The files are named systematically as `c{character}_t{tag}_r{round}.png`, where `character` ranges from 1 to 5, `tag` is the zero-padded tag index from 001 to 135, and `round` is the random seed repetition from 1 to 5. ### Metadata & Text Files * **`danbooru_expression_tags_full.jsonl`:** The core expression tag database. Each line is a JSON object with the following fields: * `tag_id`: Integer identifier from 1 to 135. * `tag`: The canonical Danbooru tag string (e.g., `+_+`, `averting_eyes`). * `definition`: Human-readable explanation of the expression, sourced from the Danbooru wiki. * `alternative_tags`: A list of Pixiv tags and translations into Chinese, Japanese, and Korean. * `wai_illustrious_sdxl_16_auto_edit`: Integer flag (1 = transformation-free; 0 = requires Photoshop transformations such as Liquify). * **`*_stories.jsonl`:** Four separate files (`english_stories.jsonl`, `chinese_stories.jsonl`, `japanese_stories.jsonl`, `korean_stories.jsonl`) containing the narrative backgrounds. Each line mirrors the fields of the tag database and adds: * `responses`: A single string containing 5 numbered stories (prefixed `1.`, `2.`, ..., `5.`) separated by blank lines, which can be split on the numeric prefix to recover individual stories. ## 🚀 Usage Download the full repository: ```bash huggingface-cli download JiashengGuo/ExpressEdit --repo-type=dataset --local-dir ./ExpressEdit ``` Load the tag database and English stories in Python: ```python import json with open("danbooru_expression_tags_full.jsonl") as f: tags = [json.loads(line) for line in f] with open("english_stories.jsonl") as f: stories = [json.loads(line) for line in f] # Access the first tag print(tags[0]["tag"], "-", tags[0]["definition"]) ``` ## 📜 Citation If you find this dataset helpful in your research, please cite: ```bibtex @article{tang2026expressedit, title={ExpressEdit: Fast Editing of Stylized Facial Expressions with Diffusion Models in Photoshop}, author={Tang, Kenan and Guo, Jiasheng and Lin, Jeffrey and Qin, Yao}, journal={arXiv preprint arXiv:2604.03448}, year={2026} } ``` ## 🙏 Acknowledgements The expression tags, definitions, and alternative tags are sourced from the [Danbooru](https://danbooru.donmai.us/) and [Pixiv Encyclopedia](https://dic.pixiv.net/en/) communities. The example stories were generated with Gemini 3 Flash.
许可协议: 知识共享署名-非商业性使用-相同方式共享 4.0 国际许可协议(CC BY-NC-SA 4.0) 任务类别: - 图像-文本转图像 - 图像转图像 语言: - 英语 - 中文 - 日语 - 韩语 标签: - 艺术 展示名称: ExpressEdit 规模类别: - 10K<n<100K 数据集查看器: 禁用 # ExpressEdit:用于风格化面部表情编辑的综合数据库  ## 🚀 交互式演示 我们在Hugging Face Spaces上部署了一款极简的检索增强生成(Retrieval-Augmented Generation, RAG)演示程序。您可以输入自定义的创意故事片段,系统将从本数据库中检索最匹配的表情标签。 👉 **[点击此处体验ExpressEdit RAG演示程序](https://huggingface.co/spaces/JiashengGuo/ExpressEdit-RAG)** ## 📋 数据集概述 面部表情是视觉叙事的核心组成部分。当前的AI图像编辑模型虽有望辅助艺术家完成风格化表情编辑任务,但这类模型会在编辑后的图像中引入全局噪声与像素漂移,导致其无法集成至专业图像编辑软件及工作流中。此外,现有模型主要依赖文本提示进行图像生成,这要求用户必须提供详细的表情描述,对提示词质量的严苛要求给用户带来了认知负担,同时拖慢了创作流程。 **ExpressEdit** 提供了一种解决方案:将自由格式的叙事意图映射为结构化生成标签。为支持根据不同叙事需求生成多样化表情,我们构建了一套涵盖135个表情标签的综合表情数据库,并为其配套了适用于检索增强生成的示例故事与图像。本数据集与ExpressEdit Photoshop插件配套发布,后者是一款用于快速且高质量风格化表情编辑的开源工具。 ## 🖼️ 数据集构成 本数据集包含文本、标签与生成图像的丰富组合: ### 表情标签 * **基础标签**:我们从Danbooru官网的面部标签与眼部标签库中提取表情标签,手动筛选出可辅助表情生成的条目并过滤了露骨内容,最终得到**135个表情标签**。 * **定义说明**:每个表情标签的定义均取自Danbooru官网,明确了该标签的适用与不适用场景。 * **替代标签**:我们还补充了替代标签,包括各表情对应的Pixiv标签,以及该表情标签的中文、日语、韩语译法,最终共获得**332个替代标签**。 * **无变换标记**:每个标签均标注了一个标记,用于指示该标签是否可在不使用Photoshop液化等变换工具的前提下进行可靠编辑。其中100个标签支持无变换编辑,剩余35个标签需进行快速手动操作。 ### 示例故事 * 为启发用户并优化检索流程,我们使用Gemini 3 Flash为每个标签生成5条示例故事。 * 该流程覆盖英语、中文、日语、韩语四种语言。 * 最终共生成**2700篇短篇故事**(135个标签 × 5篇故事 × 4种语言)。 ### 示例图像 * 示例图像基于5张原始角色图像自动生成。 * 针对每个表情标签,我们使用不同的随机种子重复生成5次,最终共获得**3375张编辑后图像**。 ## 🎯 应用场景 ExpressEdit数据集主要有两类核心应用: ### 检索增强生成(RAG) 借助本数据库,用户可通过视觉语言模型(Vision-Language Model, VLM)便捷地检索与自身故事、创意或具体编辑指令相关的标签。ExpressEdit将自由格式的用户意图转换为结构化表情标签,将提示词优化为适配图像生成模型的格式,缓解了多模态生成模型对提示词的敏感性问题——该问题可能会降低图像生成质量。  ### 表情风格化参考 3375张图像生成结果可作为视觉基准,用于展示特定Danbooru标签如何影响不同随机种子下各类二维角色的风格、眼部位置与嘴部形态。 ## 🏗️ 数据集结构 本仓库按图像文件夹与基于文本的JSONL文件进行组织: ### 图像数据 * **`results/` 目录**:包含3375张生成的`.png`格式图像。文件命名规则为`c{character}_t{tag}_r{round}.png`,其中`character`取值范围为1至5,`tag`为补零的标签索引(001至135),`round`为随机种子重复次数(1至5)。 ### 元数据与文本文件 * **`danbooru_expression_tags_full.jsonl`**:核心表情标签数据库。每行均为一个JSON对象,包含以下字段: * `tag_id`:1至135的整数标识符。 * `tag`:标准Danbooru标签字符串(例如`+_+`、`averting_eyes`)。 * `definition`:取自Danbooru维基的可读式表情解释。 * `alternative_tags`:Pixiv标签列表,以及中文、日语、韩语译法。 * `wai_illustrious_sdxl_16_auto_edit`:整数标记(1代表支持无变换编辑;0代表需使用Photoshop液化等变换工具)。 * **`*_stories.jsonl`**:四个独立文件(`english_stories.jsonl`、`chinese_stories.jsonl`、`japanese_stories.jsonl`、`korean_stories.jsonl`),存储叙事背景信息。每行格式与标签数据库一致,额外包含: * `responses`:单个字符串,包含5条编号故事(前缀为`1.`、`2.`……`5.`),以空行分隔,可通过数字前缀拆分得到单条故事。 ## 🚀 使用方法 下载完整仓库: bash huggingface-cli download JiashengGuo/ExpressEdit --repo-type=dataset --local-dir ./ExpressEdit 在Python中加载标签数据库与英文故事: python import json with open("danbooru_expression_tags_full.jsonl") as f: tags = [json.loads(line) for line in f] with open("english_stories.jsonl") as f: stories = [json.loads(line) for line in f] # 访问第一个标签 print(tags[0]["tag"], "-", tags[0]["definition"]) ## 📜 引用信息 若您在研究中使用本数据集,请引用如下文献: bibtex @article{tang2026expressedit, title={ExpressEdit: Fast Editing of Stylized Facial Expressions with Diffusion Models in Photoshop}, author={Tang, Kenan and Guo, Jiasheng and Lin, Jeffrey and Qin, Yao}, journal={arXiv preprint arXiv:2604.03448}, year={2026} } ## 🙏 致谢 本数据集的表情标签、定义说明与替代标签均源自Danbooru与Pixiv Encyclopedia社区。示例故事由Gemini 3 Flash生成。