gptoss20b-bilingual-curriculum-sft
收藏资源简介:
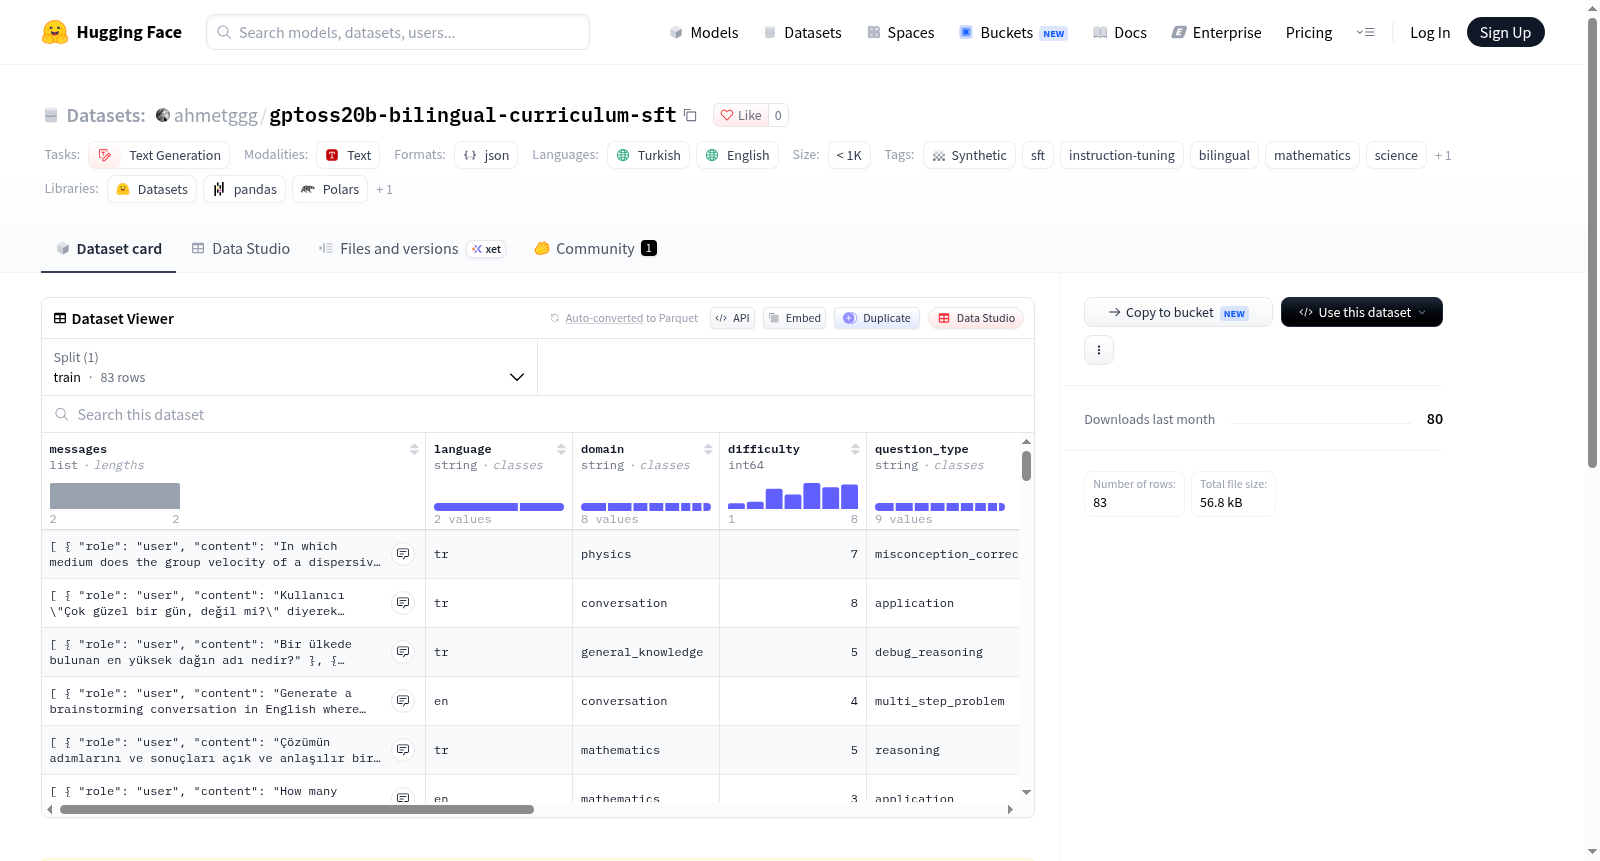
该数据集是一个使用 gpt-oss-20b 模型(混合专家模型,约3.6B活跃参数,原生MXFP4,按难度自适应推理努力)生成的合成双语监督微调数据。数据集涵盖数学、物理、化学、生物、计算机科学、通用科学、通用知识和对话等多个领域,语言为土耳其语和英语。难度级别从1到8(共8个等级)。数据集适用于文本生成和对话任务,尤其适合指令微调场景。注意:该数据集为合成数据,在生产环境中使用前应进行独立评估。
This dataset is a synthetic bilingual supervised fine-tuning data generated using the gpt-oss-20b model (a mixture of experts model with approximately 3.6B active parameters, native MXFP4, and adaptive reasoning effort based on difficulty). The dataset covers multiple domains including mathematics, physics, chemistry, biology, computer science, general science, general knowledge, and conversation, with languages in Turkish and English. Difficulty levels range from 1 to 8 (8 levels in total). The dataset is suitable for text generation and conversation tasks, particularly for instruction fine-tuning scenarios. Note: This dataset is synthetic data and should be independently evaluated before use in production environments.
gpt-oss-20b Bilingual Curriculum SFT 数据集概述
基本信息
- 数据集名称:gpt-oss-20b Bilingual Curriculum SFT
- 任务类型:文本生成、对话
- 标签:合成数据、监督微调(SFT)、指令微调、双语、数学、科学、gpt-oss
数据内容
- 生成模型:gpt-oss-20b(MoE架构,约36亿激活参数,原生MXFP4格式,支持按难度自适应推理)
- 覆盖领域:数学、物理、化学、生物学、计算机科学、通用科学、通用知识、对话
- 语言:土耳其语和英语
- 难度等级:1-8级
数据性质
- 该数据集为合成数据,由gpt-oss-20b模型生成
- 数据为双语教学模式,结合不同难度层级进行课程式编排
- 重要提示:数据集为合成性质,在生产环境使用前应进行独立评估