TheGreatRambler/mm2_level
收藏资源简介:
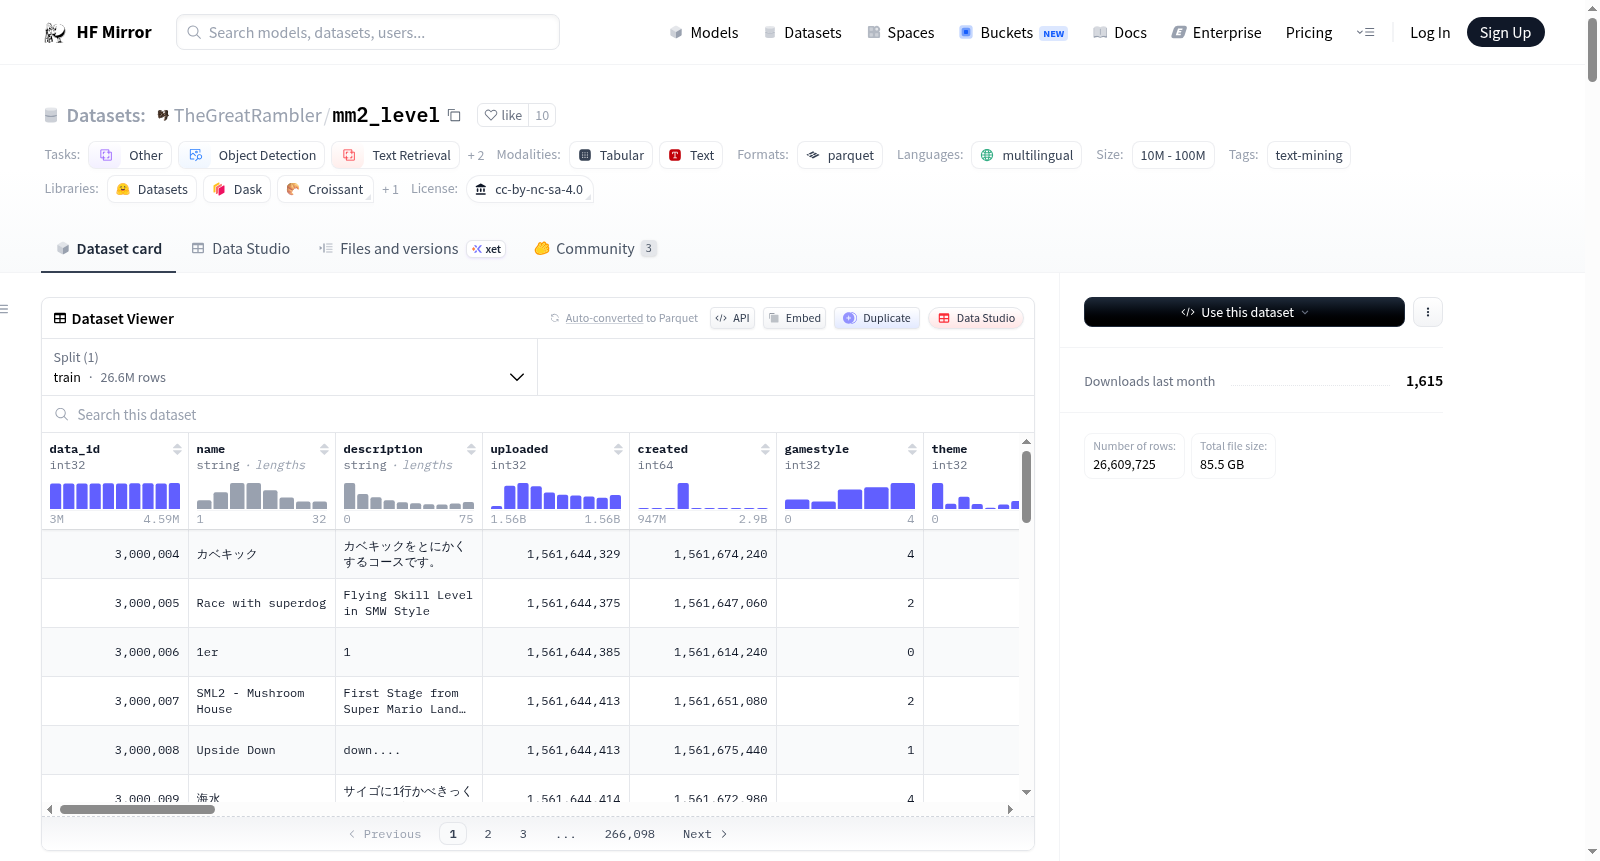
Mario Maker 2 levels数据集包含来自任天堂在线服务的2660万个关卡,总计约100GB的数据。该数据集是通过自托管的Mario Maker 2 API在2022年2月的一个月内创建的。数据集中包含多个字段,如关卡ID、名称、描述、上传时间、创建时间、游戏风格、主题、难度等。此外,还提供了如何使用该数据集的代码示例,包括如何加载和迭代数据集,以及如何解析关卡数据。
The Mario Maker 2 Levels dataset contains 26.6 million levels sourced from Nintendo's online services, with a total data volume of approximately 100 GB. This dataset was collected over the course of one month in February 2022 via a self-hosted Mario Maker 2 API. The dataset includes multiple fields, such as level ID, name, description, upload time, creation time, game style, theme, difficulty, and more. In addition, code examples for using the dataset are provided, including how to load and iterate over the dataset, as well as how to parse level data.
Mario Maker 2 Levels Dataset Summary
Dataset Overview
General Information
- Language: Multilingual
- License: CC-BY-NC-SA-4.0
- Size: 10M<n<100M
- Source: Original
- Tasks: Object-detection, text-retrieval, token-classification, text-generation, other
- Tags: text-mining
- Pretty Name: Mario Maker 2 levels
Dataset Description
- Content: Consists of 26.6 million levels from Nintendos online service, totaling around 100GB of data.
- Creation: Created using the self-hosted Mario Maker 2 API over the course of 1 month in February 2022.
Data Structure
Data Instances
Each instance includes details such as:
- Data ID: Unique identifier.
- Name: Course name.
- Description: Course description.
- Uploaded: UTC timestamp for when the level was uploaded.
- Created: Local timestamp for when the level was created.
- Gamestyle: Enum indicating the game style.
- Theme: Enum indicating the course theme.
- Difficulty: Enum indicating the difficulty level.
- Tags: Enum indicating the tags associated with the course.
- Game Version: Version of the game this level was made on.
- World Record: Time in milliseconds for the world record.
- Upload Time: Time in milliseconds for the upload.
- Upload Attempts: Number of attempts to upload.
- Number of Comments: Number of comments on the course.
- Clear Condition: Enum indicating the clear condition.
- Timer: Timer of the level.
- Autoscroll Speed: Speed of the autoscroll.
- Clears: Number of course clears.
- Attempts: Number of course attempts.
- Clear Rate: Course clear rate.
- Plays: Number of course plays.
- Versus Matches: Number of versus matches.
- Coop Matches: Number of coop matches.
- Likes: Number of likes.
- Boos: Number of boos.
- Unique Players and Versus: Unique players that have played this level.
- Weekly Likes: Weekly likes on this course.
- Weekly Plays: Weekly plays on this course.
- Uploader PID: Player ID of the uploader.
- First Completer PID: Player ID of the first completer.
- Record Holder PID: Player ID of the record holder.
- Level Data: GZIP compressed decrypted level data.
Data Fields
Detailed descriptions of each field are provided, including data types and descriptions.
Data Splits
- Splits: Contains only a train split.
Enums
The dataset includes several enum fields for game styles, difficulties, course themes, and tags, which can be converted to their string equivalents.
Considerations
- Content Warning: Levels may contain harmful language or depictions.