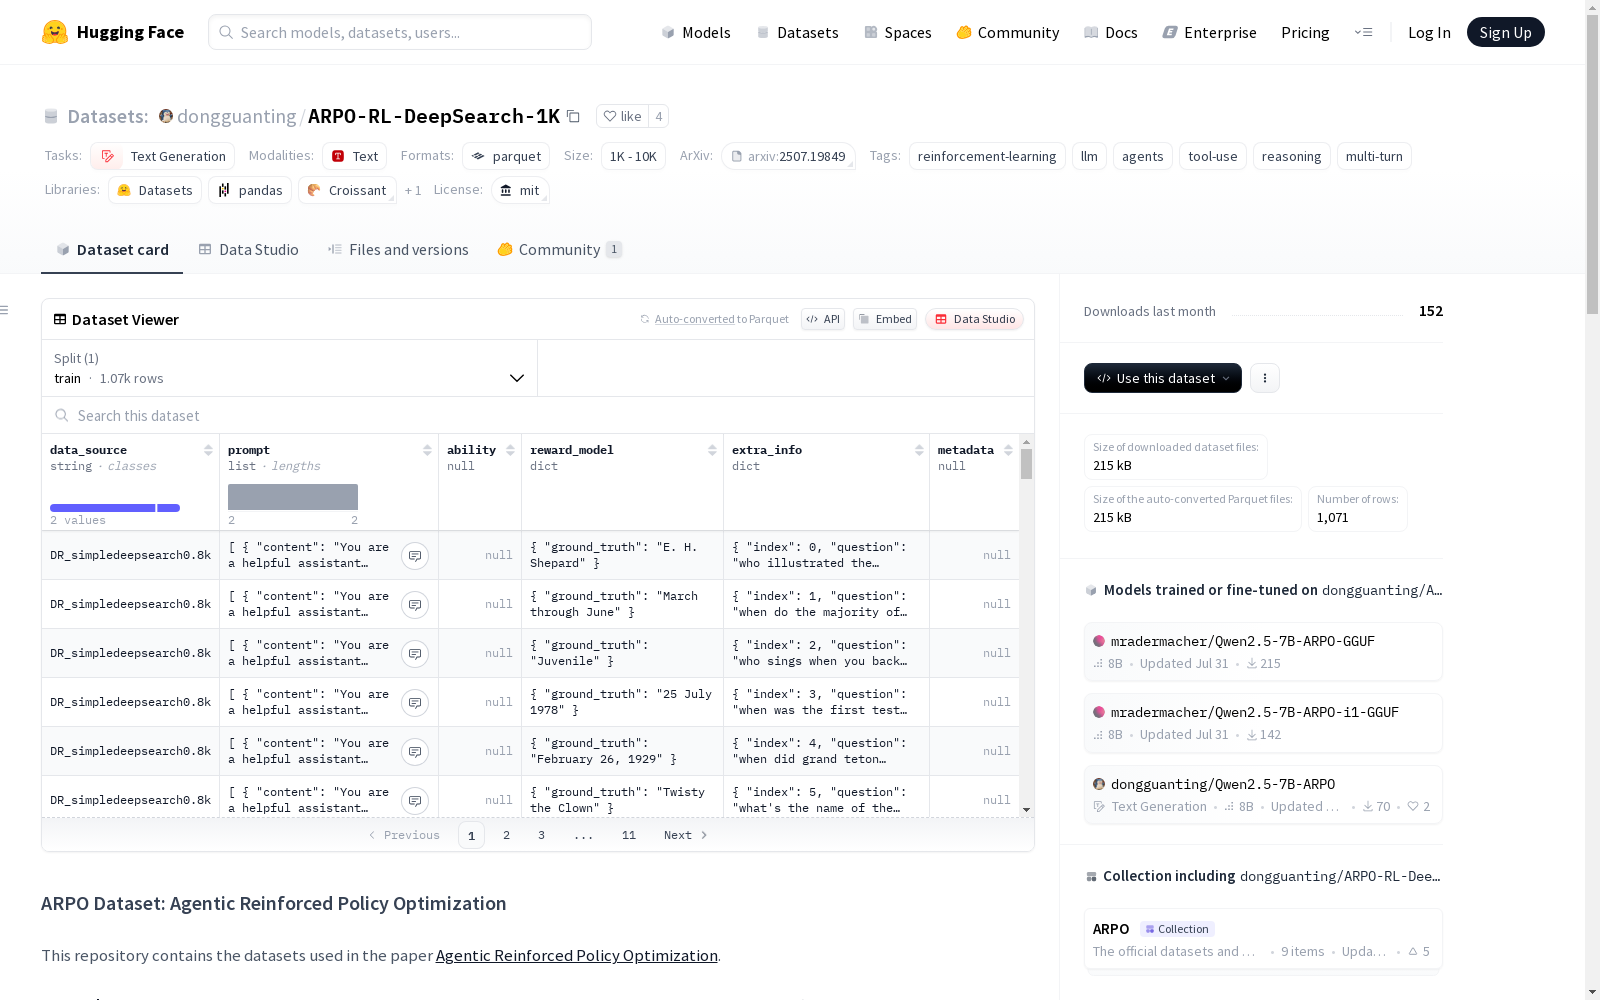
ARPO-RL-DeepSearch-1K
收藏资源简介:
ARPO数据集是一个用于验证Agentic Reinforced Policy Optimization算法有效性的数据集,包含推理和知识推理基准以及深度搜索能力基准的数据。它旨在帮助训练能够在实时动态环境中工作的多轮大型语言模型(LLM)代理。数据集分为推理和知识数据集、深度搜索数据集以及用于冷启动监督微调的ARPO-SFT-54K数据集。
The ARPO dataset is a specialized dataset developed to validate the effectiveness of the Agentic Reinforced Policy Optimization algorithm. It includes data from three types of benchmarks: inference benchmarks, knowledge reasoning benchmarks, and deep search capability benchmarks. This dataset is designed to support the training of multi-turn large language model (LLM) agents that can operate in real-time dynamic environments. It is categorized into three subsets: the Inference and Knowledge Dataset, the Deep Search Dataset, and the ARPO-SFT-54K dataset for cold-start supervised fine-tuning.
ARPO-RL-DeepSearch-1K 数据集概述
基本信息
- 许可证: MIT
- 任务类别: 文本生成
- 标签:
- 强化学习
- 大语言模型 (LLM)
- 代理
- 工具使用
- 推理
- 多轮对话
数据集描述
ARPO-RL-DeepSearch-1K 数据集是 Agentic Reinforced Policy Optimization (ARPO) 项目的一部分,专为测试具有深度搜索能力的 LLM 代理而设计。该数据集包含 1,000 个样本,其中 800 个来自 SimpleDeepSearch,200 个来自 WebDancer。
数据集内容
- 主要文件:
hard_search.parquet- 样本数量: 1,000
- 来源:
- SimpleDeepSearch: 800 个样本
- WebDancer: 200 个样本
相关数据集
- 推理与知识数据集:
dongguanting/ARPO-RL-Reasoning-10K- 训练集:
train_10k.parquet(10,000 个样本) - 测试集:
test.parquet(300 个样本,来自 8 个不同数据集)
- 训练集:
- 监督微调数据集:
dongguanting/ARPO-SFT-54K- 样本数量: 54,000
使用示例
bash
安装 Git LFS
git lfs install
克隆深度搜索 RL 数据集
git clone https://huggingface.co/datasets/dongguanting/ARPO-RL-DeepSearch-1K
引用
如需引用,请使用以下 BibTeX 条目: bibtex @misc{dong2025arpo, title={Agentic Reinforced Policy Optimization}, author={Guanting Dong and Hangyu Mao and Kai Ma and Licheng Bao and Yifei Chen and Zhongyuan Wang and Zhongxia Chen and Jiazhen Du and Huiyang Wang and Fuzheng Zhang and Guorui Zhou and Yutao Zhu and Ji-Rong Wen and Zhicheng Dou}, year={2025}, eprint={2507.19849}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2507.19849}, }