
CIRCL/circl-ail-dataset-01
收藏资源简介:
--- license: cc-by-4.0 tags: - darkweb - screenshot --- ## Introduction CERTs such as CIRCL and security teams collect and process content such as images (at large from photos, screenshots of websites or screenshots of sandboxes). Datasets become larger - e.g. on average 10000 screenshots of onion domains websites are scrapped each day in [AIL - Analysis Information Leak framework](https://github.com/ail-project/ail-framework), an analysis tool of information leak - and analysts need to classify, search and correlate through all the images. Automatic tools can help them in this task. Less research about image matching and image classification seems to have been conducted exclusively on websites screenshots. However, a classification of this kind of pictures needs to be addressed. ### Goal Image-matching algorithms benchmarks already exist and are highly informative, but none is delivered turnkey. Our long-term objective is to build a generic library and services which can at least be easily integrated in Threat Intelligence tools such as [AIL](https://github.com/ail-project/ail-framework), and [MISP - Threat Intelligence Sharing Platform](https://github.com/MISP/MISP). A quick-lookup mechanism for correlation would be necessary and part of this library. This paper includes the release of two datasets to support research effort in this direction. MISP is an open source software solution tool developed at CIRCL for collecting, storing, distributing and sharing cyber security indicators and threats about cyber security incidents analysis. AIL is also an open source modular framework developed at CIRCL to analyze potential information leaks from unstructured data sources or streams. It can be used, for example, for data leak prevention. The dataset presented on this page is strongly associated with other projects, which are an evaluation framework provided as [Carl-Hauser](https://github.com/CIRCL/carl-hauser) and the open-source library provided as [Douglas-Quaid](https://github.com/CIRCL/douglas-quaid). ## Problem Statement Image correlation for security event correlation purposes is nowadays mainly manual. No open-source tool provides easy correlation on pictures, without regard to the technology used. Ideally, the extraction of links or correlation between these images could be fully automated. Even partial automation would reduce the burden of this task on security teams. Datasets are part of the foundation needed to construct such tool. Our contribution about this problem is the provision of datasets to support research effort in this direction. # Dataset description ## circl-ail-dataset-01 This dataset is named circl-ail-dataset-01 and is composed of [AIL](https://github.com/ail-project/ail-framework)'s scraped onion websites. Around 37500 pictures are in this dataset to date. Only one label-classification (DataTurks direct output) is provided along with the dataset. This classification is per part and will be improved and updated as soon as classification operations had been achieved. Direct link : [https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/](https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/) 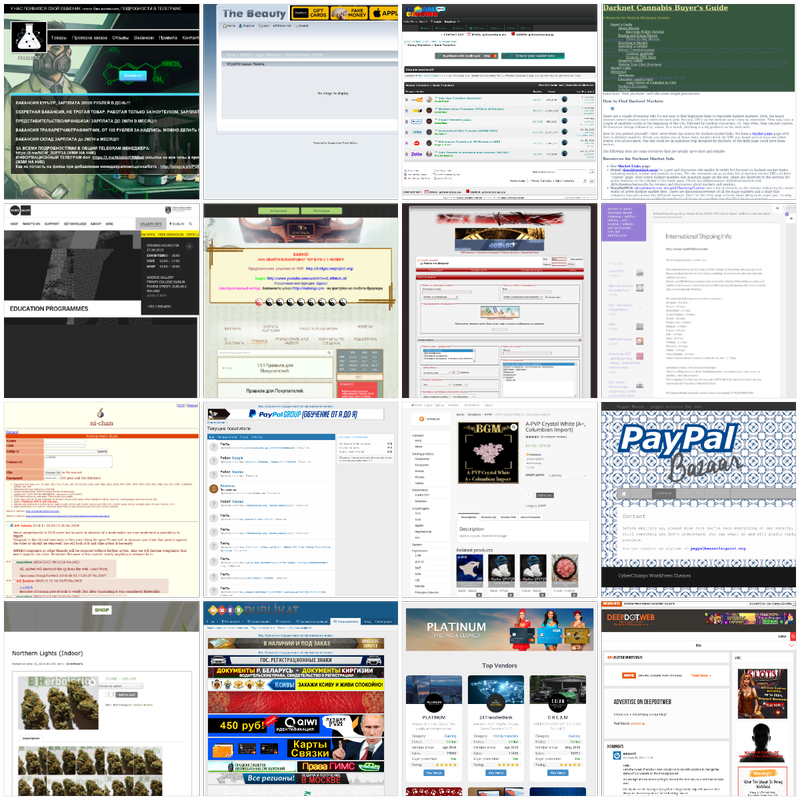 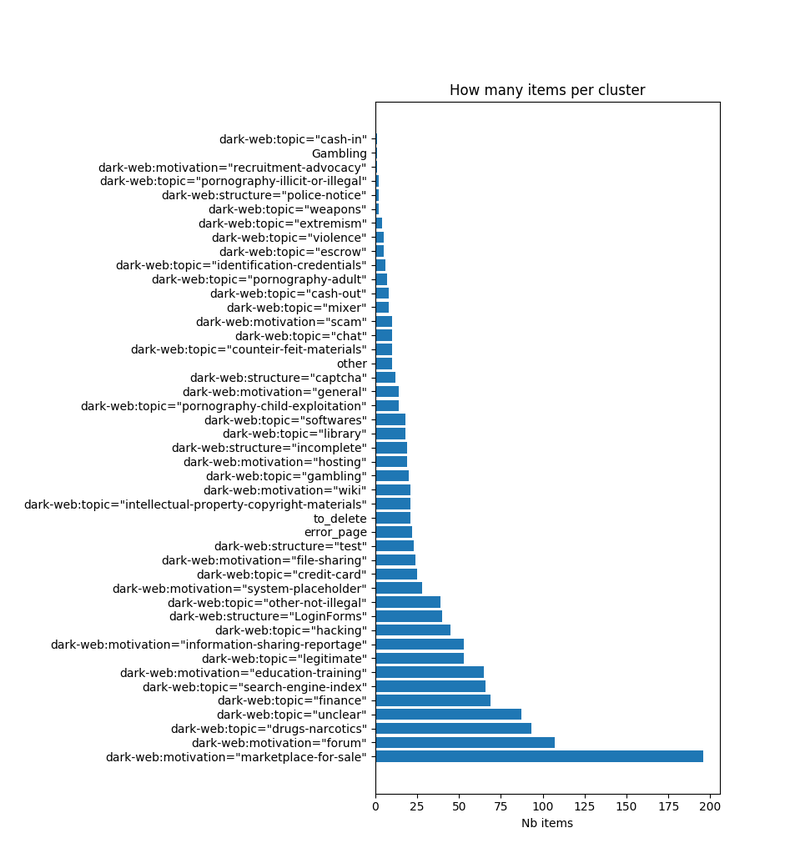 Sampled over 800 pictures 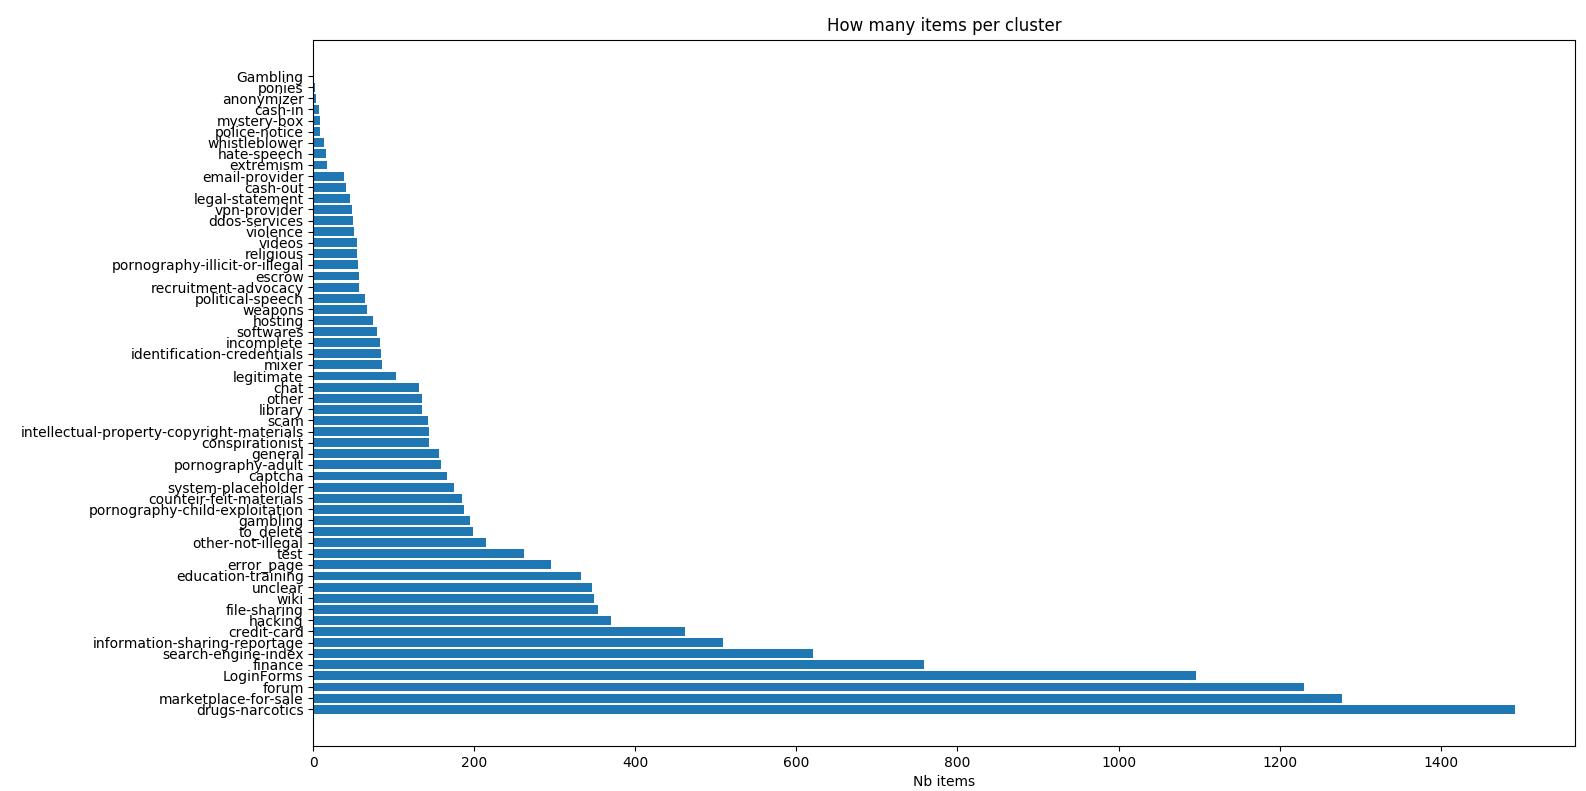 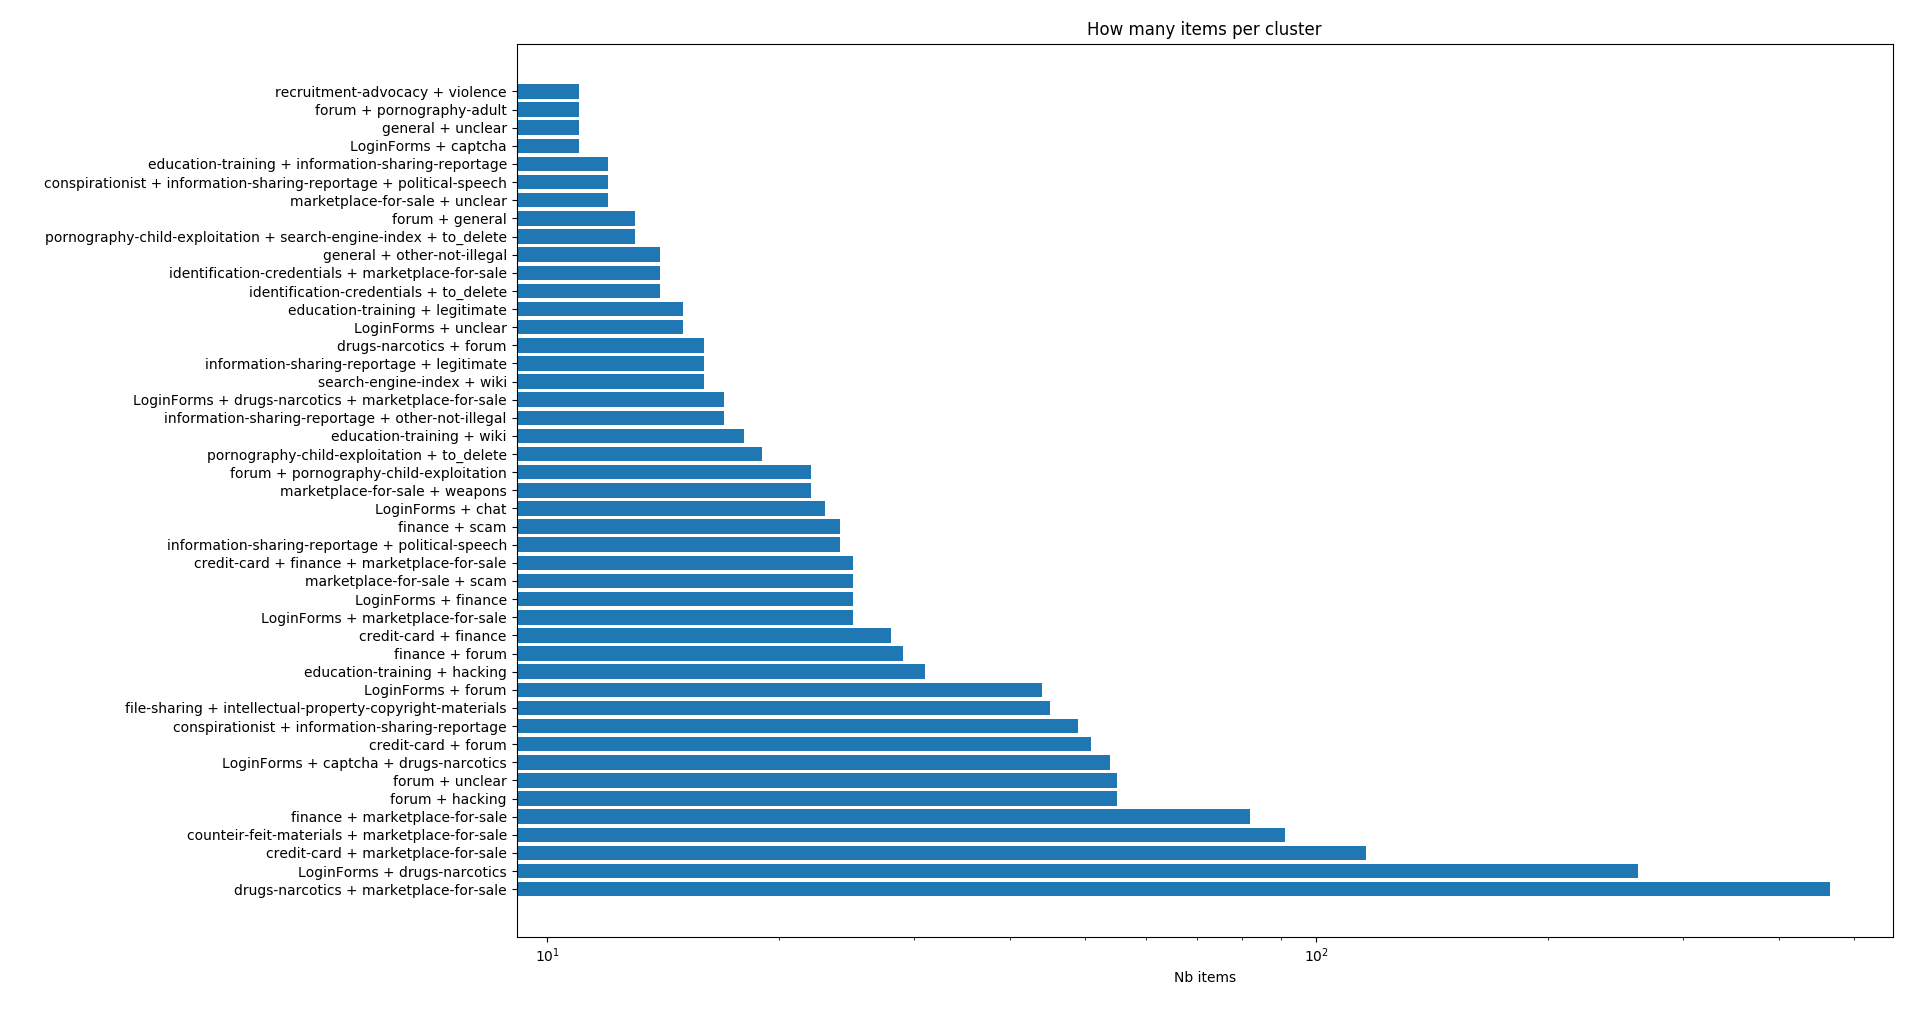 Sampled over 9500 pictures. Be aware of the log scale of the second frequency chart. # Data sources Different tools collected the dataset presented on this page. The screenshots's data source is a subset of onion domain websites scrapped by [AIL](https://github.com/ail-project/ail-framework); ### Processing on datasets Each picture's content of each dataset was hashed to "humanly readable" name to allow a unified and readable reference system for image's naming convention. This had been performed with a slightly modified version of [Codenamize - Consistent easier-to-remember codenames generator](https://github.com/jjmontesl/codenamize). The bytes-content of each file is hashed and mapped to a list of words, from a dictionary. Collision were handled by keeping track of which name has already been generated, and temporary adding bytes to each colliding file. However collision were still rare. A human-readable hash of 3 adjectives (without a maximum number of characters) can generates up to 2 trillion combinations, which is far sufficient to handle even 40 000 pictures without common collision occurrence. Collision were however easily met in case of similar pictures (typically, all white or all dark pictures) but then, their name can be swapped without incidence on the meaning of the dataset. This dataset is a folder of pictures as well as a reference JSON, containing a mapping from file names to MD5, SHA1, SHA256 of each picture. This allows an easy retrieval of which picture is which, in case picture names need to be modified. We manually reviewed datasets, picture by picture. We used a private instance of [Dataturks - OpenSource Data Annotation tool for teams](https://github.com/DataTurks/DataTurks) to perform classification and review the datasets. We removed datasets pictures which were identified as containing personal information such as sensitive e-mail address clearly displayed on screenshoots, ... We also manually removed pictures which were identified as containing harmful content, such as violent, offensive, obscene or equivalent undesirable pictures which may shock anyone. We makes reasonable effort not to display anything in the dataset which may specifically identify an individual. This dataset is provided for research purposes. We stay available for any request. Please refer to contact information at the end of this page. Please note that each website behind each screenshot can be freely accessed by one with relevant means. ## Potential Use These datasets can be used to create classifiers, which then can be used to automate processes. Few examples of application : - Automatically classify onion website; - Correlate object on pictures from crawled websites, mainly with screenshots of hidden services (AIL usecase); - Correlate websites screenshots to cluster of websites with common topic together, to keep track of domain-name changes for example (Lookyloo usecase). - Isolate and characterize outliers - Extracting statistics about crawled websites (per theme, per type, per content, per access allowance ...) ## Detailed information of the dataset Labels are used to classify each picture in one or more cluster. Labels are different depending on the dataset and the tool used to classify it. ## AIL dataset Pictures are labeled following [MISP "dark-web" taxonomy - Taxonomies used by MISP and other information threat sharing tools](https://github.com/MISP/misp-taxonomies). Labels are expressed as triplets 'namespace:predicate=value'. For example 'dark-web:topic="hacking"' is one label of this taxonomy. Two labels were added : "error page" and "other" which does not specifically belongs to dark-web, but could cover any other case met in the dataset. For a complete list of labels used, please see the following : ~~~ json dark-web:topic="drugs-narcotics", dark-web:topic="extremism", dark-web:topic="finance", dark-web:topic="cash-in", dark-web:topic="cash-out", dark-web:topic="hacking", dark-web:topic="identification-credentials", dark-web:topic="intellectual-property-copyright-materials", dark-web:topic="pornography-adult", dark-web:topic="pornography-child-exploitation", dark-web:topic="pornography-illicit-or-illegal", dark-web:topic="search-engine-index", dark-web:topic="unclear", dark-web:topic="violence", dark-web:topic="weapons", dark-web:topic="credit-card", dark-web:topic="counteir-feit-materials", dark-web:topic="gambling", dark-web:topic="library", dark-web:topic="other-not-illegal", dark-web:topic="legitimate", dark-web:topic="chat", dark-web:topic="mixer", dark-web:topic="mystery-box", dark-web:topic="anonymizer", dark-web:topic="vpn-provider", dark-web:topic="email-provider", dark-web:topic="escrow", dark-web:topic="softwares", dark-web:motivation="education-training", dark-web:motivation="file-sharing", dark-web:motivation="forum", dark-web:motivation="wiki", dark-web:motivation="hosting", dark-web:motivation="general", dark-web:motivation="information-sharing-reportage", dark-web:motivation="marketplace-for-sale", dark-web:motivation="recruitment-advocacy", dark-web:motivation="system-placeholder", dark-web:motivation="conspirationist", dark-web:motivation="scam", dark-web:motivation="hate-speech", dark-web:motivation="religious", dark-web:structure="incomplete", dark-web:structure="captcha", dark-web:structure="LoginForms", dark-web:structure="police-notice", dark-web:structure="test", dark-web:structure="legal-statement", error_page, other, ~~~ Clustering file format for Dataturks tool is a list of filename along with their labels, to which they belong. Here follows technical overview of this file format: ~~~ json (...), { "picture": "tricky-sturdy-impossible-sweet.png", "labels": [ 'dark-web:structure="legal-statement"' ] }, { "picture": "old-wet-evasive-influence.png", "labels": [ 'dark-web:motivation="scam"' ] }, (...) ~~~ ## Future work This lead to a list of future possible developments : - Extending provided dataset to support research effort - Improve classification provided - Add images extracted from DOM. These pictures allow a more particular matching. Please note that ground truth files provided with current dataset as well as dataset themselves may evolve and be updated. Even partial automation of screenshots classification would reduce the burden on security teams, and that the data we provide is a step further in this direction. ## FAQ Questions have emerged since the discussions about the published datasets. ##### Is the frequency of appearance of all labels representing reality? Label frequencies were calculated on a sample of the original dataset and measured **before** removal of any offensive images. The statistics of the initial data set and the downloadable data set are therefore different. Some labels require explanations, which can be found in the MISP-darkweb taxonomy. For example, the label "other-not-illegal" refers to any image that does not fall into any other obvious category and is not potentially illegal. The "legitimate" label refers to personal websites, blogs on general content, etc. The "other-not-illegal" label can for example refer to Tor Wiki (also labelled as "wiki"), websites that allow you to perform calculations online (e.g. hashing tools, calculator) or online gaming sites (without money). "Finance" is a very broad category referring to many subtypes: "Crypto currency", "Pump and dump", "Mixers", "Credit-Card sellers", "Paypal-related" schemes, "CryptoWallets", "Escrows", which may or may not be represented by other labels. Market-Places are usually not labelled as "Finance". ##### Is it really useful to know the frequency of labels? We can only recommend calculating the frequency of label sets. The frequency of the X or Y label is not as interesting as the frequency of a set of labels. Images can have multiple labels. Thus, the number of sites labelled "Forum + Drugs + Finance" compared to the number of sites labelled "Market-Places + Weapons" provides more information than the overall frequency of the "Finance" label alone. ##### What is the legality of these data sets? The answer has several points. In context of GDPR, the dataset is part of a scientific publication for scientific purposes. Although GDPR has a clause for this particular case, we have manually reviewed the data sets to avoid diffusion of personal information leaks (DOX). Elements may have been missed by us, so we remain available for any comments regarding these datasets. Regarding the legal aspects of the collection, all data sources are freely available with sufficient means of access. Crawling is basic and does not involve exploiting vulnerabilities, for example. Regarding the aspects related to crawling offensive content, we work closely with the relevant authorities in the fight against the dissemination of such content. ##### Can these datasets be used as a links index? We have revised the dataset to remove explicit links (clearly readable and copyable) to websites that share offensive content. Thus,".onion" addresses clearly pointing to offensive content were removed from the datasets. ##### Do I need psychological support to use this dataset? The data sets available for downloading do not contain offensive content. They can be downloaded, viewed and used by the majority of audiences, especially those with a Western/Western European reference system. This dataset could even be used for educational purposes to show (in a watered-down way) - even if we don't recommend it - what is present on the dark-web. Content culturally unacceptable is understood in the standards of the Western and Western European countries reference system. ##### Is everything in this dataset true? As true as what it represents. These sites do exist, but what they offer can be scam. We have not done any tests in this regard. As a rule of thumb, most "Finance" or "Market-Place" websites are probably scam. A "scam" label exists, and only the websites presenting the most obvious scams have been labelled as such. In particular, market places for high-tech products (e.g. iPhone) are generally scam. ##### What does the label "Religious" refer to? In general, sites offering Bible excerpts, or discussions about religion are labelled as such. Very little content related to sects or equivalent is present in the data set. ##### Is the dataset "classified" as "secret" or "labelled"? The dataset is labelled and public. ## Links - Complete dataset [https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/](https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/) - State-of-The-Art - Carl Hauser [https://github.com/CIRCL/carl-hauser/blob/master/SOTA/SOTA.md](https://github.com/CIRCL/carl-hauser/blob/master/SOTA/SOTA.md) - Open Source implementation - Douglas Quaid [https://github.com/CIRCL/douglas-quaid](https://github.com/CIRCL/douglas-quaid) - AIL framework - Analysis Information Leak framework - [https://github.com/ail-project/ail-framework](https://github.com/ail-project/ail-framework) ## Contact information If you have a complaint related to the dataset or the processing over it, please contact us. We aim to be transparent, not only about how we process but also about rights that are linked to such information and processing. You can contact us at [circl.lu/contact/](https://circl.lu/contact/) for request about the dataset itself, regarding elements of the dataset, or extension requests. You can contact us at same address or on github for feedback about the benchmarking framework, methodology or relevant ideas/inquiries. ## Cite ``` @Electronic{CIRCL-AILDS2019, author = {Vincent Falconieri}, month = {07}, year = {2019}, title = {CIRCL Images AIL Dataset}, organization = {CIRCL}, address = {CIRCL - Computer Incident Response Center Luxembourg c/o "security made in Lëtzebuerg" (SMILE) g.i.e. 122, rue Adolphe Fischer L-1521 Luxembourg Grand-Duchy of Luxembourg}, url = {https://www.circl.lu/opendata/circl-ail-dataset-01/}, abstract = {This dataset is named circl-ail-dataset-01 and is composed of Tor hidden services websites screenshots. Around 37000+ pictures are in this dataset to date.}, } ``` ## Revision - Version 1.0 - 2019-07-10 (initial release)
license: CC BY 4.0(知识共享署名4.0国际许可协议) tags: - 暗网(Dark Web) - 截图(Screenshot) --- ## 简介 计算机应急响应小组(Computer Emergency Response Team,CERT)如CIRCL与安全团队会收集并处理各类图像内容,其中大多来自照片、网站截图或沙箱截图。 数据集规模持续扩张——例如在信息泄露分析工具[AIL(信息泄露分析框架,Analysis Information Leak framework)](https://github.com/ail-project/ail-framework)中,日均会爬取约10000条.onion域名网站的截图,安全分析师需对所有图像进行分类、检索与关联分析。 自动化工具可辅助完成此类任务。但目前针对网站截图的图像匹配与分类研究相对匮乏,而这类图像的分类任务亟待解决。 ### 研究目标 现有图像匹配算法基准测试工具虽已具备较高参考价值,但均未提供开箱即用的完整方案。 我们的长期目标是构建通用库与服务,至少能够轻松集成至威胁情报工具中,例如[AIL](https://github.com/ail-project/ail-framework)与[MISP(威胁情报共享平台,Threat Intelligence Sharing Platform)](https://github.com/MISP/MISP)。该库需包含关联分析所需的快速检索机制,而本数据集的发布正是为该方向的研究提供支撑。 MISP是CIRCL开发的开源软件工具,用于收集、存储、分发与共享网络安全指标及网络安全事件分析相关的威胁情报。 AIL同样是CIRCL开发的开源模块化框架,用于从非结构化数据源或数据流中分析潜在的信息泄露事件,例如可用于数据泄露防护场景。 本页面展示的数据集与另外两个项目深度绑定:分别是作为评估框架的[Carl-Hauser](https://github.com/CIRCL/carl-hauser),以及作为开源库的[Douglas-Quaid](https://github.com/CIRCL/douglas-quaid)。 ## 问题陈述 当前用于安全事件关联的图像关联分析仍以手动为主,尚未出现可无视底层技术栈、轻松实现图像关联的开源工具。理想状态下,图像间的关联或链接提取应可完全自动化,即便实现部分自动化也能大幅减轻安全团队的工作负担,而此类工具的构建离不开数据集的支撑。 针对该问题,我们的贡献在于发布相关数据集以支撑该方向的研究工作。 # 数据集说明 ## circl-ail-dataset-01 本数据集命名为circl-ail-dataset-01,由[AIL](https://github.com/ail-project/ail-framework)爬取的.onion域名网站截图组成,截至目前共包含约37500张图像。 本数据集仅附带由Dataturks直接输出的单标签分类结果,该分类按批次生成,待分类工作完成后将持续优化与更新。 直接下载链接:[https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/](https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/)   采样自800张图像   采样自9500张图像,请注意第二张频率图表采用对数刻度。 # 数据来源 本页面展示的数据集由多种工具采集,其中截图数据源为[AIL](https://github.com/ail-project/ail-framework)爬取的.onion域名网站的子集。 ### 数据集处理流程 为实现统一且易读的图像命名规范,本数据集的每张图像均通过哈希算法生成人类可读的文件名。该流程基于经过小幅修改的[Codenamize——易记且一致的代码名生成器](https://github.com/jjmontesl/codenamize)实现:将每个文件的字节内容进行哈希运算后,映射至字典中的词汇列表。 通过记录已生成的文件名,并为冲突文件临时追加字节的方式处理哈希冲突,但此类冲突仍较为罕见。由3个形容词组成的人类可读哈希可生成多达2万亿种组合,足以应对40000张图像且不会出现常见的冲突情况。不过在相似图像(通常为全白或全黑图像)中,冲突仍易发生,但此时交换文件名不会对数据集的语义产生影响。 本数据集包含图像文件夹与参考JSON文件,其中JSON文件存储了文件名与每张图像的MD5、SHA1、SHA256哈希值的映射关系,便于在需要修改文件名时快速检索对应图像。 我们逐张人工审核了本数据集的所有图像:使用私有部署的[Dataturks——团队开源数据标注工具](https://github.com/DataTurks/DataTurks)完成分类与审核工作,并移除了包含个人信息的图像(例如屏幕截图中清晰显示的敏感电子邮箱地址等),同时手动剔除了包含暴力、冒犯、色情等可能令人不适的有害内容的图像。 我们已尽合理努力确保数据集中不存在可直接识别个人身份的内容,本数据集仅用于研究目的。若有任何需求,请联系本页面末尾的联系方式。请注意,每张截图对应的网站均可通过合规方式自由访问。 ## 潜在应用场景 本数据集可用于构建分类器,进而实现流程自动化,典型应用场景包括: - 自动对.onion域名网站进行分类; - 关联爬取网站截图中的目标对象,主要适用于暗网服务场景(AIL用例); - 将网站截图按主题聚类,例如跟踪域名变更情况(Lookyloo用例); - 识别并表征异常样本; - 提取爬取网站的统计信息(按主题、类型、内容、访问权限等维度)。 ## 数据集详细说明 标签用于将每张图像归入一个或多个类别,不同数据集与分类工具所使用的标签存在差异。 ## AIL数据集 本数据集的图像标签遵循[MISP暗网分类体系——MISP与其他威胁情报共享工具使用的分类标准](https://github.com/MISP/misp-taxonomies)。 标签采用`命名空间:谓词=值`的三元组格式,例如`dark-web:topic="hacking"`即为该分类体系下的一个标签。 此外新增了两个标签:`error_page`与`other`,二者并非专门针对暗网场景,而是用于覆盖数据集中的其他所有情况。 完整的可用标签列表如下: json dark-web:topic="drugs-narcotics", dark-web:topic="extremism", dark-web:topic="finance", dark-web:topic="cash-in", dark-web:topic="cash-out", dark-web:topic="hacking", dark-web:topic="identification-credentials", dark-web:topic="intellectual-property-copyright-materials", dark-web:topic="pornography-adult", dark-web:topic="pornography-child-exploitation", dark-web:topic="pornography-illicit-or-illegal", dark-web:topic="search-engine-index", dark-web:topic="unclear", dark-web:topic="violence", dark-web:topic="weapons", dark-web:topic="credit-card", dark-web:topic="counteir-feit-materials", dark-web:topic="gambling", dark-web:topic="library", dark-web:topic="other-not-illegal", dark-web:topic="legitimate", dark-web:topic="chat", dark-web:topic="mixer", dark-web:topic="mystery-box", dark-web:topic="anonymizer", dark-web:topic="vpn-provider", dark-web:topic="email-provider", dark-web:topic="escrow", dark-web:topic="softwares", dark-web:motivation="education-training", dark-web:motivation="file-sharing", dark-web:motivation="forum", dark-web:motivation="wiki", dark-web:motivation="hosting", dark-web:motivation="general", dark-web:motivation="information-sharing-reportage", dark-web:motivation="marketplace-for-sale", dark-web:motivation="recruitment-advocacy", dark-web:motivation="system-placeholder", dark-web:motivation="conspirationist", dark-web:motivation="scam", dark-web:motivation="hate-speech", dark-web:motivation="religious", dark-web:structure="incomplete", dark-web:structure="captcha", dark-web:structure="LoginForms", dark-web:structure="police-notice", dark-web:structure="test", dark-web:structure="legal-statement", error_page, other, Dataturks工具使用的聚类文件格式为文件名与对应标签的列表,以下为该文件格式的技术概览: json (...), { "picture": "tricky-sturdy-impossible-sweet.png", "labels": [ "dark-web:structure="legal-statement"" ] }, { "picture": "old-wet-evasive-influence.png", "labels": [ "dark-web:motivation="scam"" ] }, (...) ## 未来研究方向 据此,我们列出了未来可开展的研究方向: - 扩充现有数据集以支撑相关研究; - 优化现有分类结果; - 新增从DOM中提取的图像,此类图像可实现更精准的匹配。 请注意,本数据集附带的真值文件与数据集本身均可能进行迭代更新。 即便实现截图分类的部分自动化,也能大幅减轻安全团队的工作负担,而我们发布的数据集正是该方向的重要一步。 ## 常见问题解答 自数据集发布以来,我们收到了一些常见问题,现解答如下: ##### 所有标签的出现频率是否符合真实情况? 标签频率基于原始数据集的样本计算得出,且统计工作在移除任何有害图像**之前**完成,因此初始数据集与可下载版本的统计结果存在差异。部分标签的说明可在MISP暗网分类体系中查阅。 例如,标签`other-not-illegal`指未归入其他明确类别且无潜在违法风险的图像;`legitimate`标签则指个人网站、通用内容博客等场景。`other-not-illegal`标签可覆盖Tor维基(也可标注为`wiki`)、提供在线计算功能的网站(例如哈希工具、计算器)或无盈利模式的在线游戏网站等。 "Finance"是一个非常宽泛的类别,涵盖众多子类型:如加密货币、拉高出货、混币服务、信用卡卖家、PayPal相关诈骗、加密钱包、托管服务等,部分子类型可能已有其他标签对应。市场交易平台通常不会被标注为"Finance"。 ##### 了解标签频率是否有实际意义? 我们建议优先计算标签组合的频率:相较于单一标签的整体频率,诸如"论坛+毒品+金融"与"交易平台+武器"的标签组合频率能提供更多有效信息。 图像可被赋予多个标签,因此标签组合的统计结果更具参考价值。 ##### 本数据集的合法性如何? 该问题可从多个维度解答: 在GDPR框架下,本数据集属于用于科学研究的学术出版物范畴,符合GDPR的相关豁免条款。同时我们已人工审核数据集,避免泄露个人可识别信息(DOX),尽管如此仍可能存在疏漏,若有相关意见请随时联系我们。 关于数据采集的合法性:所有数据源均可通过合规方式自由访问,爬取行为未涉及任何漏洞利用等非法操作。 关于有害内容爬取的相关问题:我们已与相关主管部门密切合作,共同打击此类内容的传播。 ##### 本数据集能否作为链接索引使用? 我们已审核数据集,移除了指向有害内容网站的明确可复制链接,因此数据集中已不存在指向有害内容的.onion地址。 ##### 使用本数据集是否需要心理咨询支持? 可下载的数据集版本未包含有害内容,大多数受众均可正常下载、查看与使用,符合西欧与北美地区的文化标准。 本数据集甚至可用于教育场景,以(简化形式)展示暗网上存在的内容(我们不建议直接展示原始内容)。本数据集所包含的文化上不可接受的内容,均符合西欧与北美地区的定义标准。 ##### 数据集中的内容是否真实可靠? 就其本身而言是真实的:这些网站确实存在,但其中提供的服务可能为诈骗。我们未针对这一点进行验证。 一般而言,大多数"金融"或"交易平台"类网站大概率为诈骗站点。本数据集已针对最明显的诈骗站点标注了"scam"标签,例如主打高端电子产品(如iPhone)的交易平台通常均为诈骗站点。 ##### 标签"Religious"具体指什么? 一般而言,提供圣经章节或宗教讨论内容的网站会被标注为该标签。数据集中与教派或类似内容相关的占比极低。 ##### 本数据集是否被标记为"机密"或受保密限制? 本数据集为带标签的公开数据集。 ## 相关链接 - 完整数据集 [https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/](https://www.circl.lu/opendata/datasets/circl-ail-dataset-01/) - 前沿技术综述——Carl Hauser [https://github.com/CIRCL/carl-hauser/blob/master/SOTA/SOTA.md](https://github.com/CIRCL/carl-hauser/blob/master/SOTA/SOTA.md) - 开源实现——Douglas Quaid [https://github.com/CIRCL/douglas-quaid](https://github.com/CIRCL/douglas-quaid) - AIL框架——信息泄露分析框架 [https://github.com/ail-project/ail-framework](https://github.com/ail-project/ail-framework) ## 联系方式 若您对本数据集或其处理流程有任何异议,请联系我们。我们致力于保持透明,不仅包括数据处理方式,还包括此类信息与处理流程相关的权益问题。 您可通过[circl.lu/contact/](https://circl.lu/contact/)联系我们,以获取数据集相关请求、数据集元素咨询或扩展需求支持。 关于基准测试框架、方法论或相关想法/咨询的反馈,可通过同一邮箱或GitHub渠道联系我们。 ## 引用格式 bibtex @Electronic{CIRCL-AILDS2019, author = {Vincent Falconieri}, month = {07}, year = {2019}, title = {CIRCL Images AIL Dataset}, organization = {CIRCL}, address = {CIRCL - Computer Incident Response Center Luxembourg c/o "security made in Lëtzebuerg" (SMILE) g.i.e. 122, rue Adolphe Fischer L-1521 Luxembourg Grand-Duchy of Luxembourg}, url = {https://www.circl.lu/opendata/circl-ail-dataset-01/}, abstract = {本数据集命名为circl-ail-dataset-01,由Tor隐藏服务网站的截图组成,截至目前共包含约37000张图像。}, } ## 版本更新记录 - 版本1.0 - 2019年7月10日(初始发布)


