dianavdavidson/mucs-hinglish-blindtest
收藏资源简介:
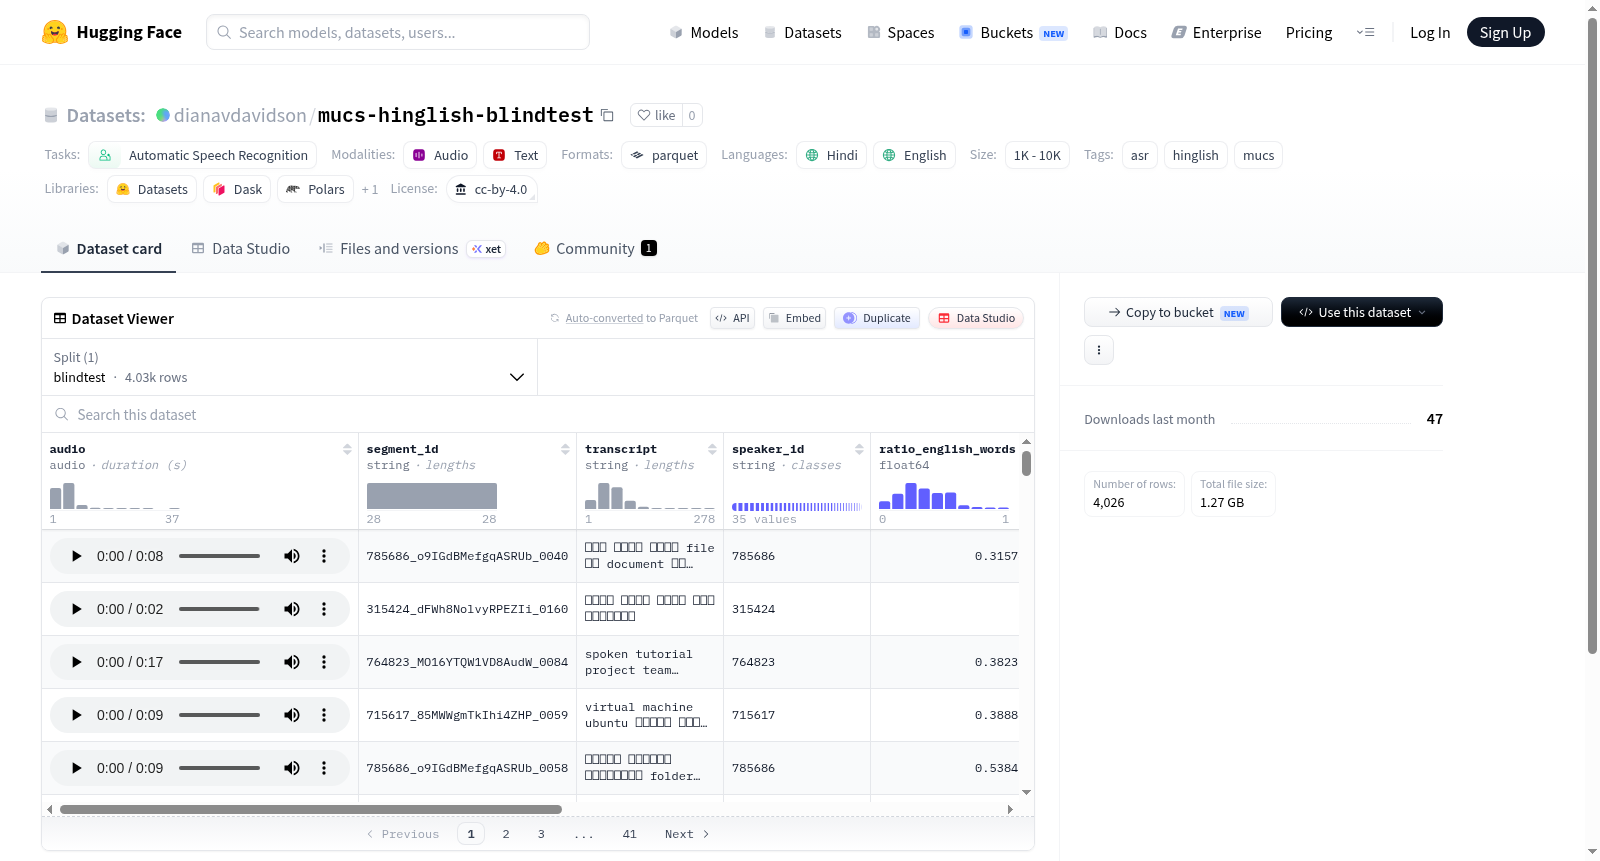
MUCS 2021 Hinglish盲测数据集是一个用于自动语音识别(ASR)任务的语音数据集,专门设计用于处理印地语和英语混合的Hinglish语言。该数据集包含4026个音频样本,采样率为16kHz,每个样本包括音频文件、转录文本、说话者ID、以及语言相关的统计信息,如英语和印地语单词的比例和计数。数据集仅提供盲测分割,用于模型评估,支持多语言ASR研究,并遵循CC-BY-4.0许可证。
The MUCS 2021 Hinglish blind test dataset is a speech dataset for automatic speech recognition (ASR) tasks, specifically designed for Hinglish, a mixed language combining Hindi and English. It contains 4026 audio samples with a sampling rate of 16 kHz. Each sample includes an audio file, transcription text, speaker ID, and language-related statistical information such as the proportion and count of English and Hindi words. The dataset only provides a blind test split for model evaluation, supports multilingual ASR research, and is licensed under CC-BY-4.0.