llm-jp/llm-jp-4-8b-thinking-dpo-data
收藏资源简介:
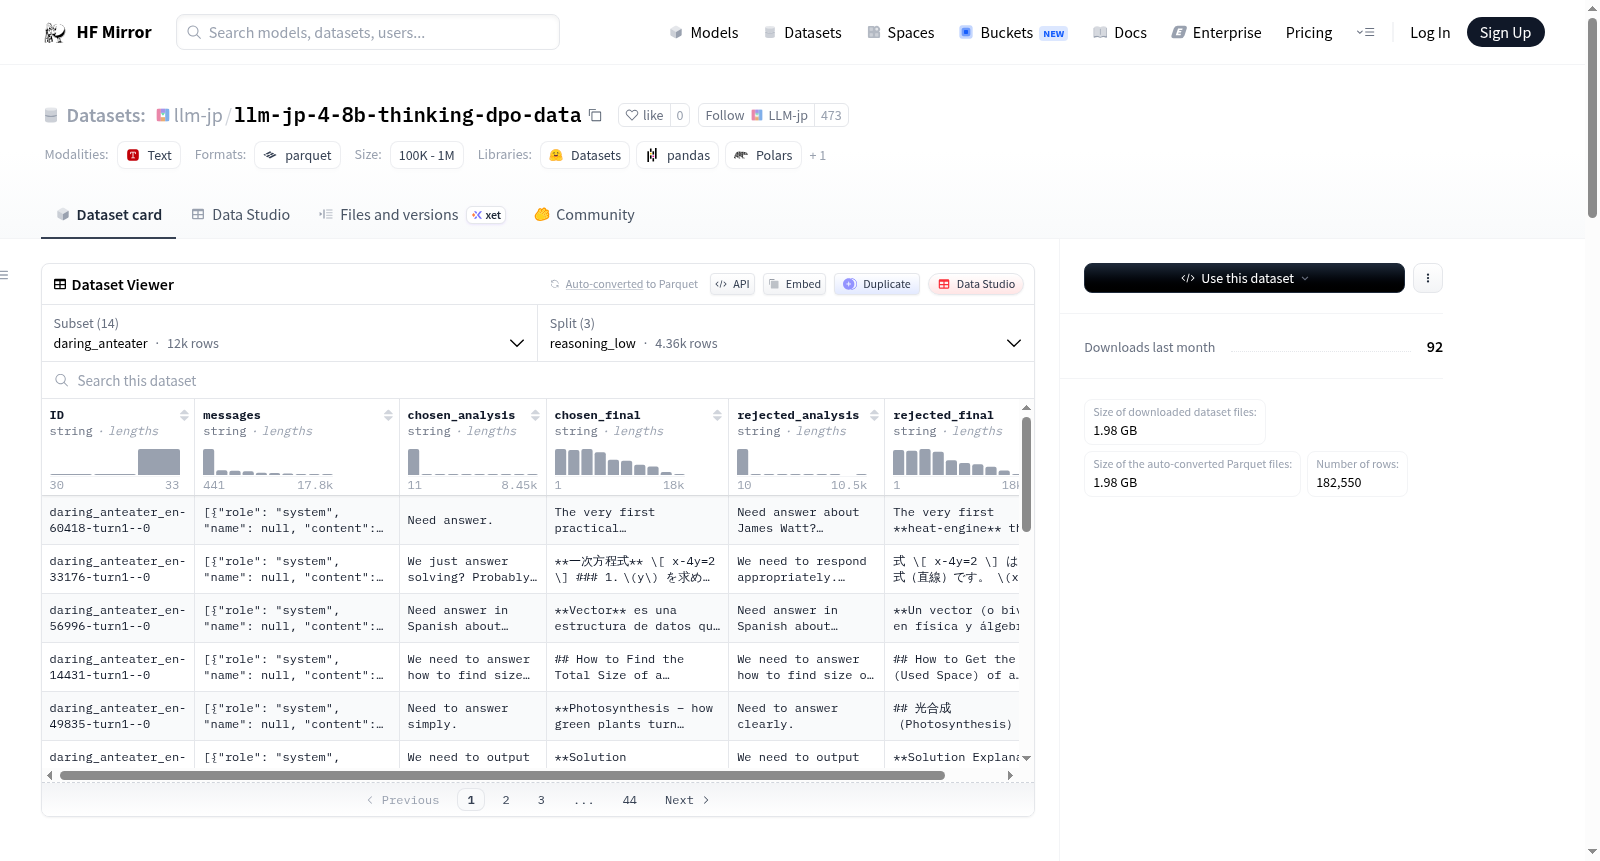
该数据集名为llm-jp-4-8b-thinking-dpo-data,是一个用于训练llm-jp-4-8b-thinking模型的直接偏好优化(DPO)数据集。数据集包含针对给定提示的配对响应(选择的和拒绝的),并根据不同的推理努力设置(低、中、高)进行分类。响应是通过监督微调模型生成的,并由gpt-oss-120b进行评估。数据集从多个来源编译而成,具有不同的许可证,其中一些由于重新分发限制而未包含在内。数据集包括多个配置,具有详细的特征和分割。
This dataset, named llm-jp-4-8b-thinking-dpo-data, is a Direct Preference Optimization (DPO) dataset used to train the llm-jp-4-8b-thinking model. It consists of paired responses (chosen and rejected) for given prompts, categorized into different reasoning effort settings (low, medium, high). The responses are generated using a supervised fine-tuned model and evaluated by gpt-oss-120b. The dataset is compiled from various sources with different licenses, some of which are not included due to redistribution restrictions. The dataset includes multiple configurations with detailed features and splits.