xudongwu/RPL_Q3-0.6B_U10_beta0.10rho0.00K4_sf1.00
收藏资源简介:
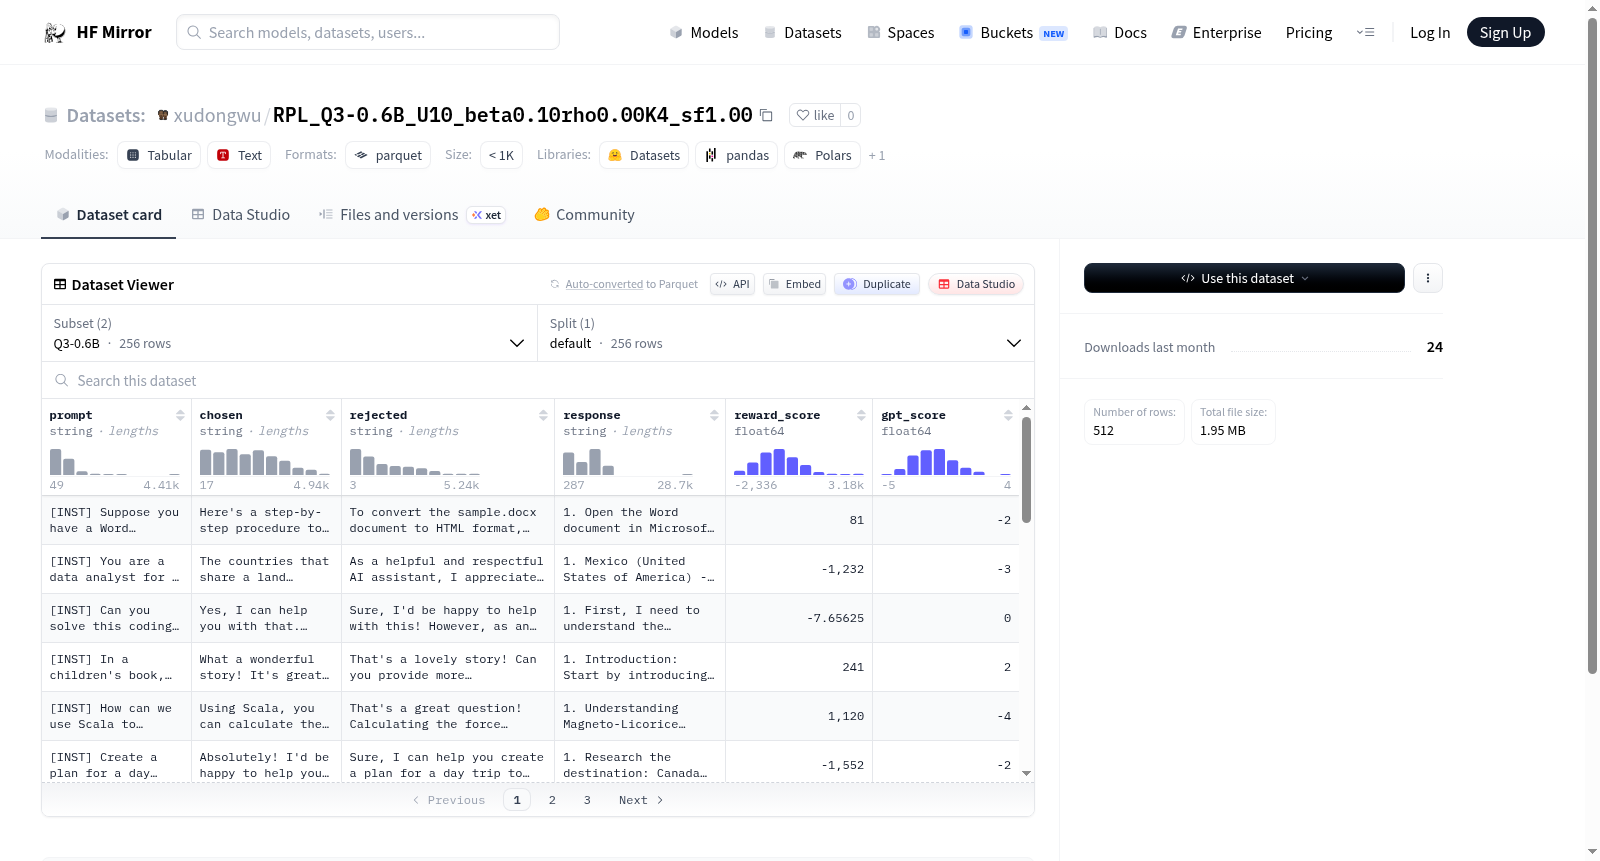
该数据集包含两个配置(Q3-0.6B和Q3-0.6B-s600),每个配置有256个示例,用于偏好学习或强化学习对齐任务。特征包括:prompt(提示文本)、chosen(被选中的高质量回答)、rejected(被拒绝的低质量回答)、response(模型响应文本)、reward_score(奖励模型评分)和gpt_score(GPT模型评分,仅Q3-0.6B配置包含),旨在通过对比回答和评分数据训练或评估语言模型。
This dataset contains two configurations: Q3-0.6B and Q3-0.6B-s600, each with 256 examples, designed for preference learning or reinforcement learning alignment tasks. Its features include: prompt (prompt text), chosen (selected high-quality responses), rejected (rejected low-quality responses), response (model-generated responses), reward_score (reward model scores), and gpt_score (GPT model scores, only available in the Q3-0.6B configuration). This dataset aims to train or evaluate language models using comparative response and scoring data.