yodas-granary
收藏资源简介:
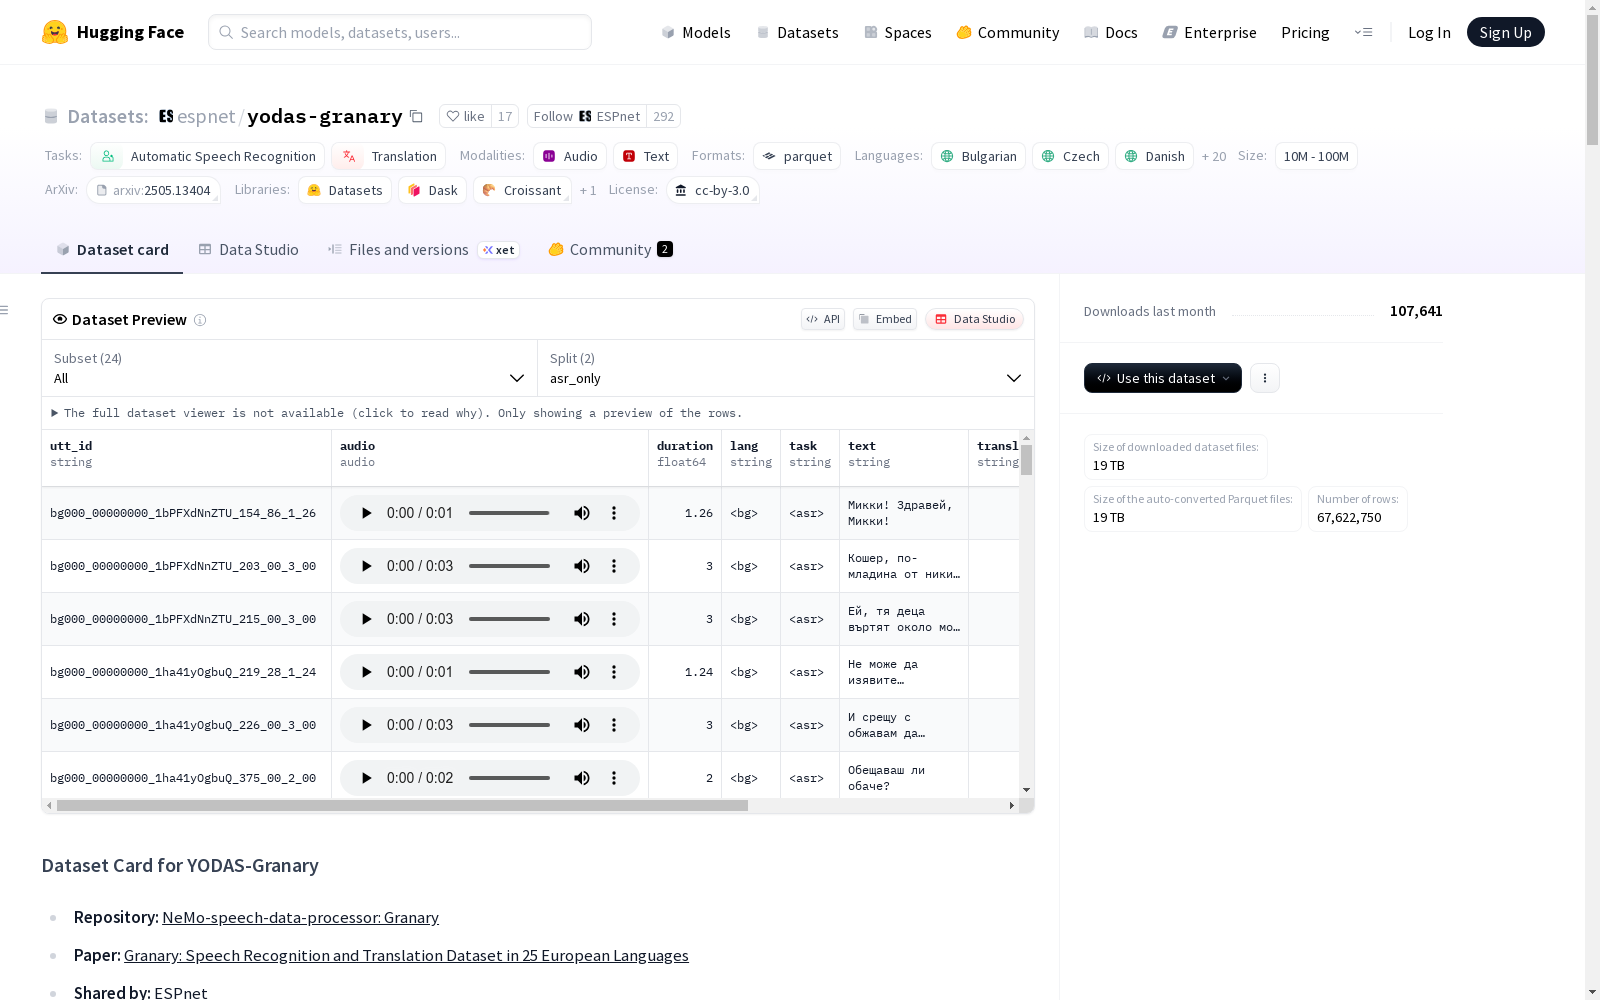
YODAS-Granary是一个由更大的NVIDIA/Granary数据集精心挑选的子集,专注于高质量的伪标签语音数据,用于自动语音识别(ASR)和自动语音翻译(AST)跨23种欧洲语言。数据集包括特征,如utterance ID,音频采样率为16000 Hz,持续时间,语言,任务,文本,英文翻译,原始音频ID和原始音频偏移。数据集分为ASR-only和AST子集,数据分布在各种语言中。数据集在CC BY 3.0许可下可用,并通过NeMo语音数据处理器存储库访问。
YODAS-Granary is a carefully curated subset derived from the larger NVIDIA/Granary dataset, focusing on high-quality pseudo-labeled speech data for automatic speech recognition (ASR) and automatic speech translation (AST) across 23 European languages. The dataset includes attributes such as utterance ID, audio sampling rate of 16000 Hz, duration, language, task, transcript, English translation, original audio ID, and original audio offset. It is divided into ASR-only and AST subsets, with data distributed across various languages. The dataset is available under the CC BY 3.0 license and can be accessed via the NeMo Speech Data Processor repository.