Multimodal Oil & Gas Benchmark
收藏资源简介:
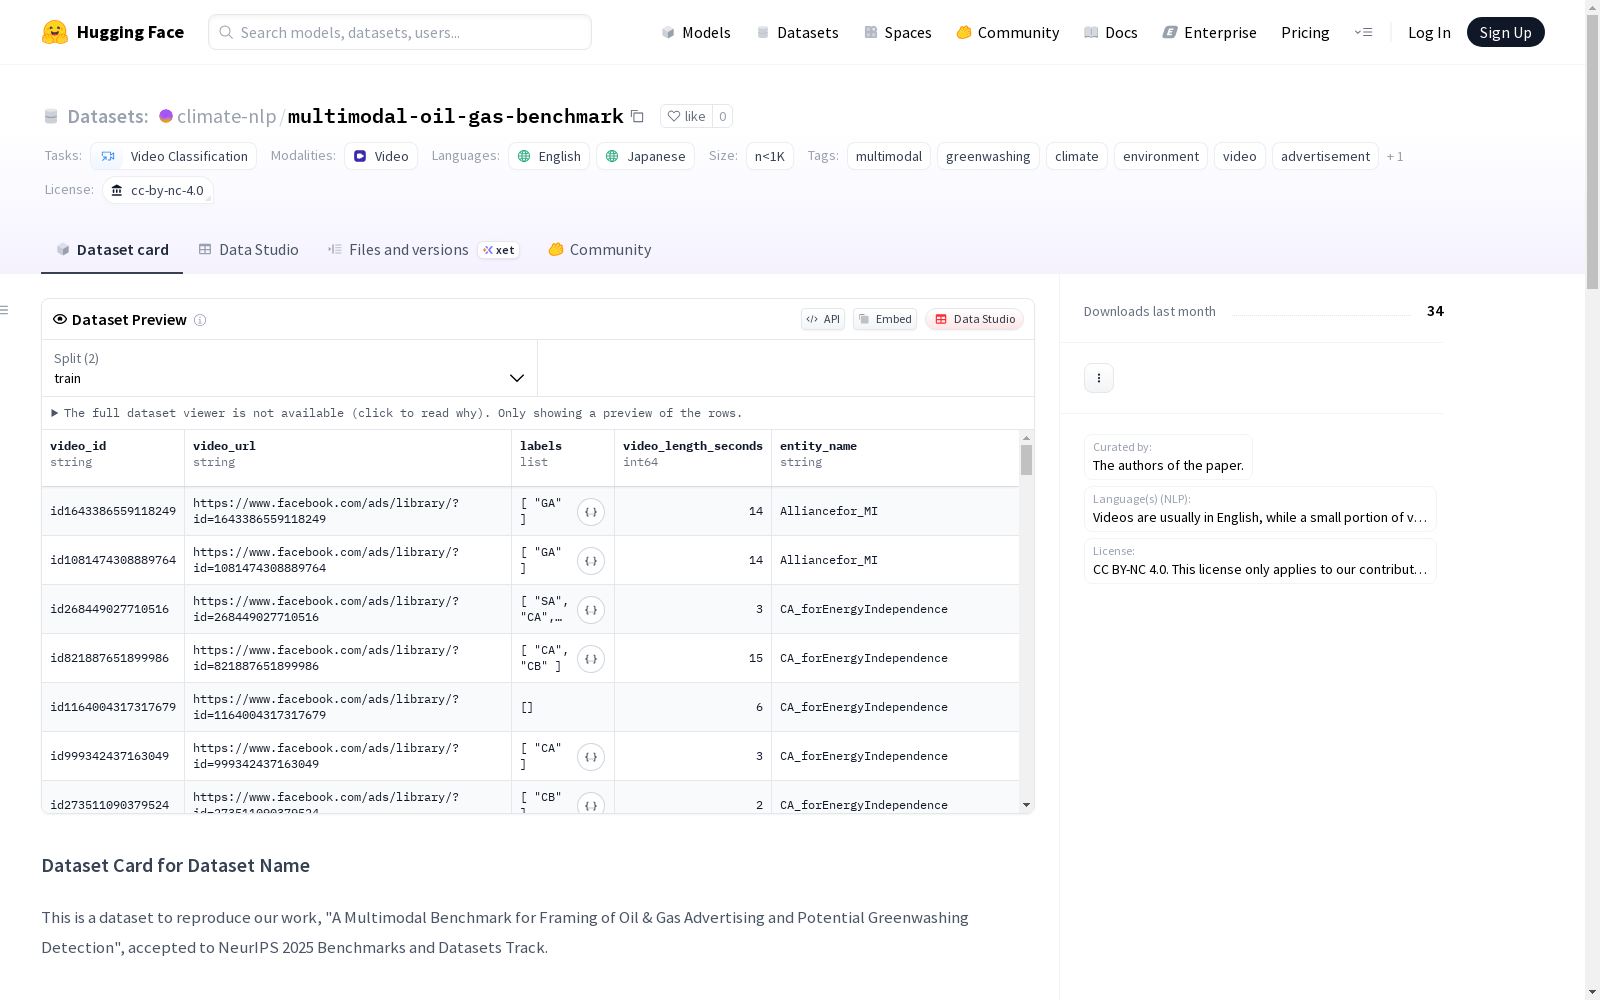
本数据集是一个多模态基准数据集,专门用于评估视觉语言模型(VLMs)在石油和天然气广告和潜在漂绿检测方面的能力。数据集由专家标注的视频广告组成,包括来自Facebook和YouTube的13种框架类型,涉及20个国家的50多个公司或倡导组织。数据集设计独特,旨在评估VLMs在现实世界战略框架方面的表现,并支持跨领域、实体级别和时间分析。
This dataset is a multimodal benchmark dataset specifically tailored to evaluate the capabilities of Vision-Language Models (VLMs) in detecting oil and gas advertisements and potential greenwashing. It consists of expert-annotated video advertisements, including 13 types of framing frameworks sourced from Facebook and YouTube, and covers over 50 companies or advocacy organizations across 20 countries. Uniquely designed, this dataset aims to assess VLMs' performance on real-world strategic framing tasks, while supporting cross-domain, entity-level and temporal analysis.
多模态石油天然气广告基准数据集概述
数据集基本信息
- 数据集名称:多模态石油天然气广告基准数据集
- 创建者:论文作者
- 许可证:CC BY-NC 4.0(仅适用于作者贡献部分,不包含原始视频内容权利)
- 语言:主要为英语,少量视频包含日语等非英语语言
- 任务类别:视频分类
- 标签:多模态、漂绿、气候、环境、视频、广告、大语言模型
- 数据规模:小于1000个样本
数据集用途
直接用途
- 研究目的
- 用于基准测试视觉语言模型预测石油天然气实体的阻碍性和印象派框架
超出范围用途
- 禁止用于商业目的
- 仅限研究用途
数据集结构
数据格式
- JSON-Line格式,每行一个视频样本
- 基本数据结构包含以下字段:
- video_id:视频唯一标识符
- video_url:视频URL(已匿名化)
- labels:标注标签
- video_length_seconds:视频时长(秒)
- entity_name:视频发布者实体名称(已匿名化)
数据集创建
数据来源
- 视频URL来源于YouTube和Facebook广告
- 标签基于先前文献(Holder等人和Rowlands等人)
标注过程
- YouTube数据集:手动标注
- Facebook数据集:远程标注
- 标注者:YouTube数据集由作者参与标注,Facebook数据集标注来源于先前文献
数据收集
- 源视频来自社交媒体上的公共广告视频
- 详细信息请参阅论文
引用信息
text @inproceedings{morio-etal-2025-multimodal, author = {Morio, Gaku and Rowlands, Harri and Stammbach, Dominik and Manning, Christopher D and Henderson, Peter}, booktitle = {Advances in Neural Information Processing Systems}, title = {A Multimodal Benchmark for Framing of Oil & Gas Advertising and Potential Greenwashing Detection}, year = {2025} }
相关资源
- 代码仓库:https://github.com/climate-nlp/multimodal-oil-gas-benchmark
- 论文:A Multimodal Benchmark for Framing of Oil & Gas Advertising and Potential Greenwashing Detection (NeurIPS 2025)
联系方式
- 请联系论文作者,主要联系邮箱请参阅论文