
KETI-AIR/kor_ag_news
收藏官方服务:
资源简介:
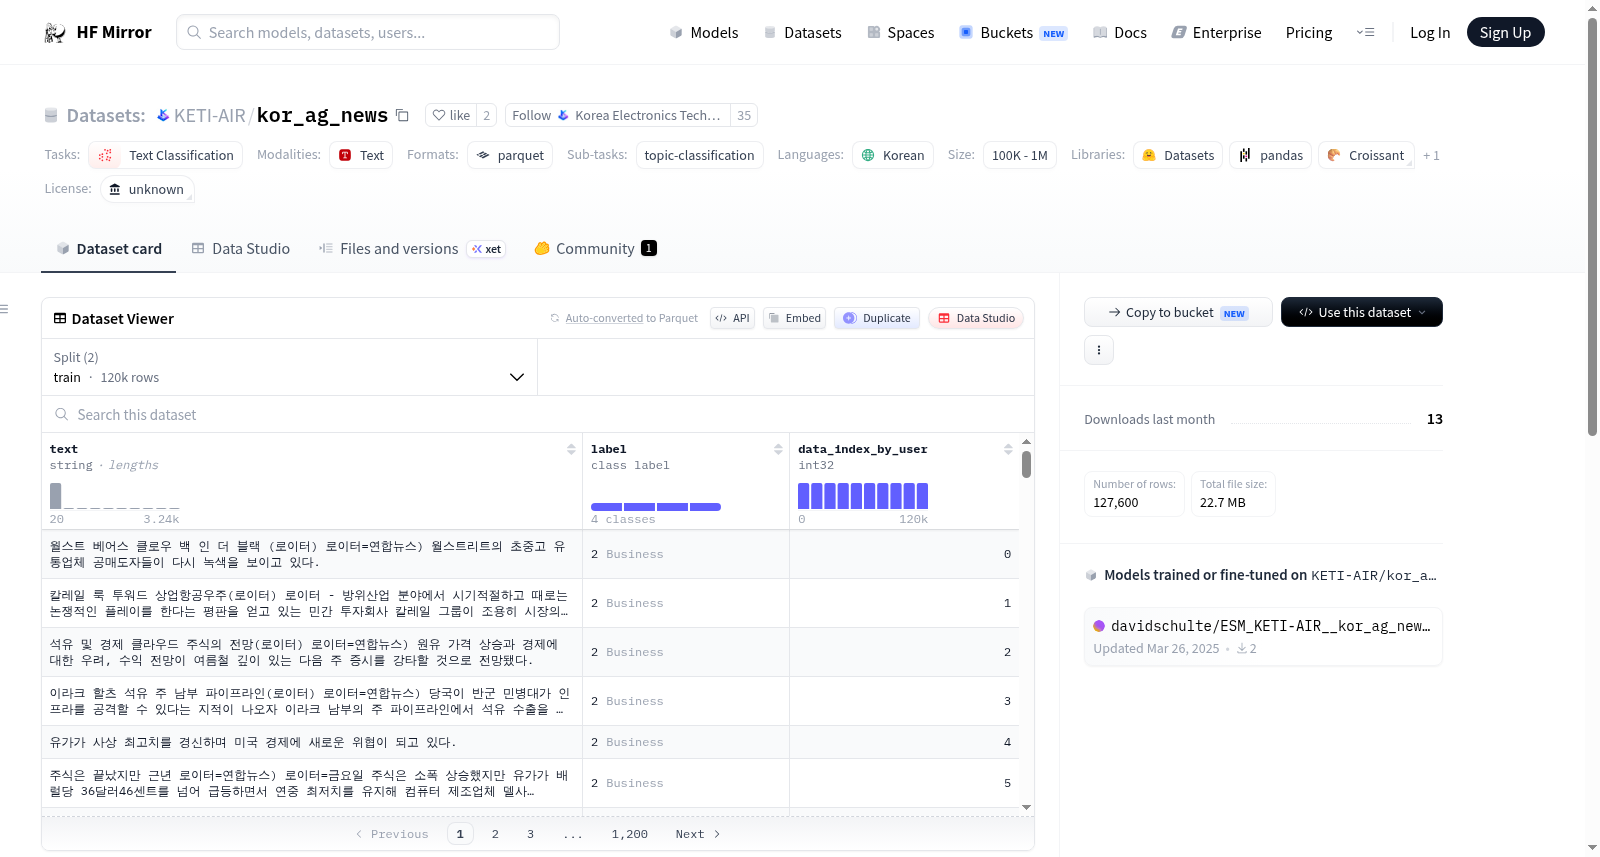
AG新闻数据集是一个包含超过100万篇新闻文章的集合,这些文章来自2000多个新闻源,由ComeToMyHead学术新闻搜索引擎在一年多的时间内收集。该数据集由Xiang Zhang从原始数据集中构建,并用于文本分类基准测试。数据集的特征包括文本、标签和用户数据索引。数据集分为训练集和测试集,分别包含120,000和7,600个样本。
The AG News Dataset is a collection of over 1 million news articles sourced from more than 2,000 news outlets, which was collected over a period of more than one year by the ComeToMyHead academic news search engine. Constructed by Xiang Zhang from the original raw dataset, it serves as a standard benchmark for text classification tasks. The dataset features text, labels, and user data indices, and is partitioned into training and test subsets containing 120,000 and 7,600 samples respectively.
提供机构:
KETI-AIR原始信息汇总
AGs News Corpus 数据集概述
基本信息
- 语言: 韩语 (ko)
- 大小类别: 100K<n<1M
- 任务类别: 文本分类 (text-classification)
- 任务ID: 主题分类 (topic-classification)
- Papers with Code ID: ag-news
- 美观名称: AG’s News Corpus
- 许可证: 未知
数据集详情
- 特征:
- text: 数据类型为字符串 (string)
- label: 数据类型为类别标签 (class_label),标签名称为:
- 0: World
- 1: Sports
- 2: Business
- 3: Sci/Tech
- data_index_by_user: 数据类型为整数 (int32)
- 分割:
- train: 字节数为 35075728,样本数为 120000
- test: 字节数为 2195191,样本数为 7600
- 下载大小: 22724153 字节
- 数据集大小: 37270919 字节
搜集汇总
数据集介绍
背景与挑战
背景概述
KETI-AIR/kor_ag_news是一个韩语新闻主题分类数据集,基于AG新闻数据集构建,包含约128,000条新闻文本,用于文本分类任务。数据集涵盖多个主题类别(如商业、科技),旨在为数据挖掘和信息检索研究提供基准,支持非商业学术用途。
以上内容由遇见数据集搜集并总结生成


