Omanic
收藏资源简介:
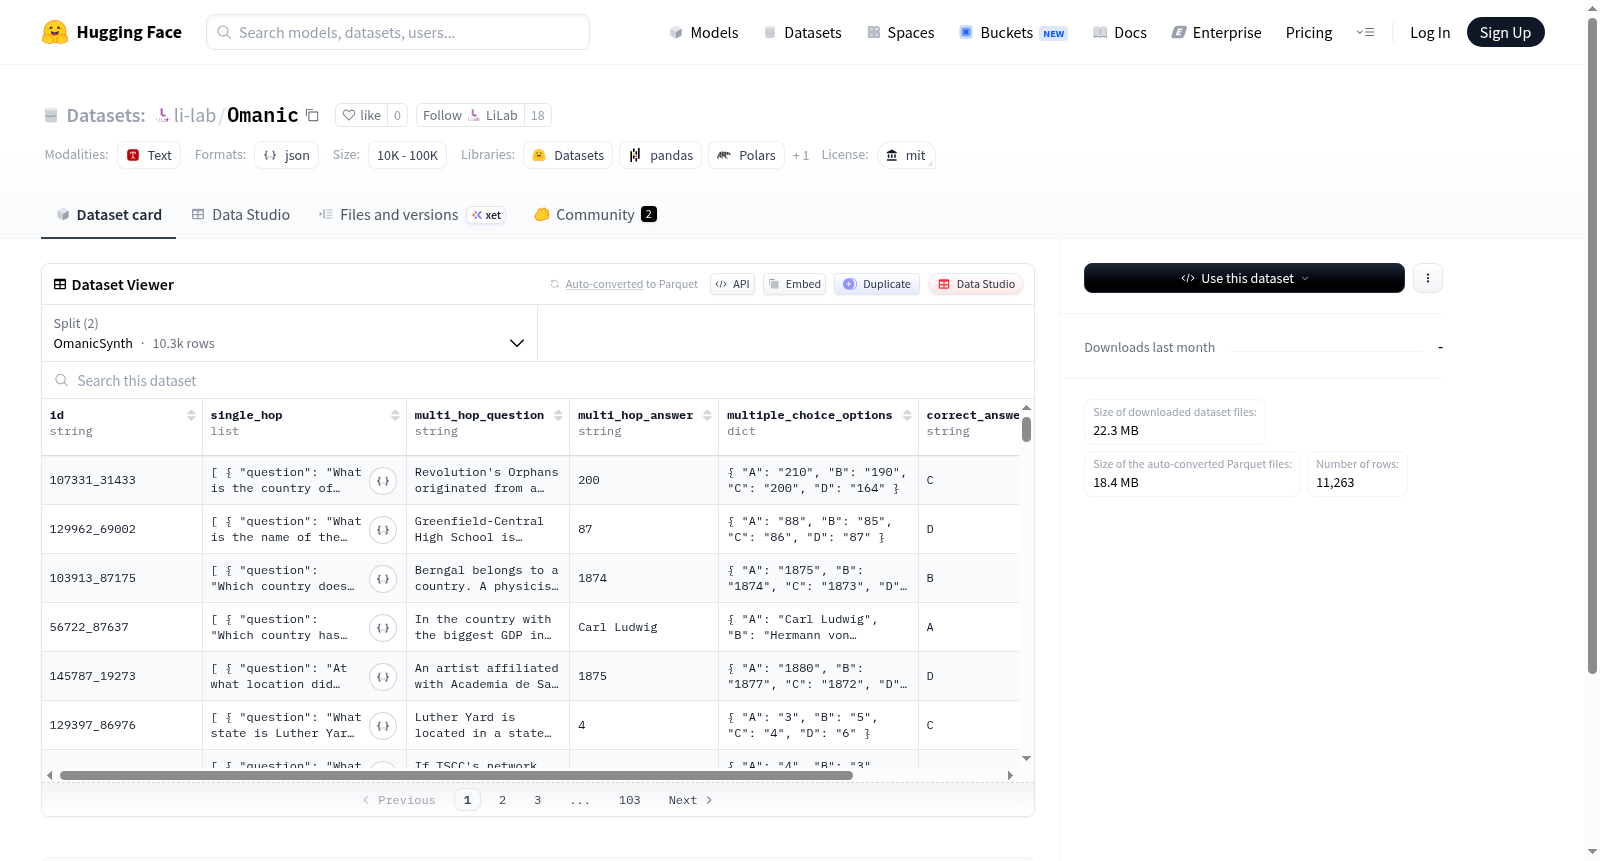
Omanic是由东京大学等机构联合构建的开放领域多跳问答基准数据集,包含10,296条机器生成的训练样本和967条专家评审的测试样本。该数据集通过结构化标注(分解的子问题及中间答案)支持逐步推理分析,覆盖8个知识领域并嵌入数学推理环节。数据来源于MuSiQue的2跳问题扩展和Wikidata知识图谱,经过严格的自动过滤和人工审核流程。其核心价值在于诊断大语言模型在多跳推理中的知识依赖和错误传播现象,适用于复杂推理能力评估与提升研究。
Omanic is an open-domain multi-hop question answering benchmark dataset jointly constructed by The University of Tokyo and other institutions. It includes 10,296 machine-generated training samples and 967 expert-reviewed test samples. This dataset supports step-by-step reasoning analysis via structured annotations, which cover decomposed sub-questions and intermediate answers. It spans 8 knowledge domains and incorporates mathematical reasoning components. The data is derived from the 2-hop question expansion of MuSiQue and the Wikidata knowledge graph, and has undergone strict automatic filtering and manual review procedures. Its core value lies in diagnosing the knowledge dependence and error propagation phenomena of large language models (LLMs) in multi-hop reasoning, and it is applicable to research on complex reasoning capability evaluation and improvement.
数据集概述
数据集标识
- 数据集名称: Omanic
- 托管平台: Hugging Face Datasets
- 唯一地址: https://huggingface.co/datasets/li-lab/Omanic
- 许可证: MIT License
数据集配置与结构
数据集采用单一默认配置(config_name: default),数据通过两个独立的JSON Lines文件提供,每个文件对应一个特定的数据划分。
数据文件划分
-
OmanicSynth
- 文件路径: OmanicSynth.jsonl
- 说明: 该文件包含名为“OmanicSynth”的数据划分。
-
OmanicBench
- 文件路径: OmanicBench.jsonl
- 说明: 该文件包含名为“OmanicBench”的数据划分。
数据格式
- 主要格式: JSON Lines (.jsonl)
- 说明: 每个数据文件均为JSON Lines格式,即每行是一个独立的JSON对象。