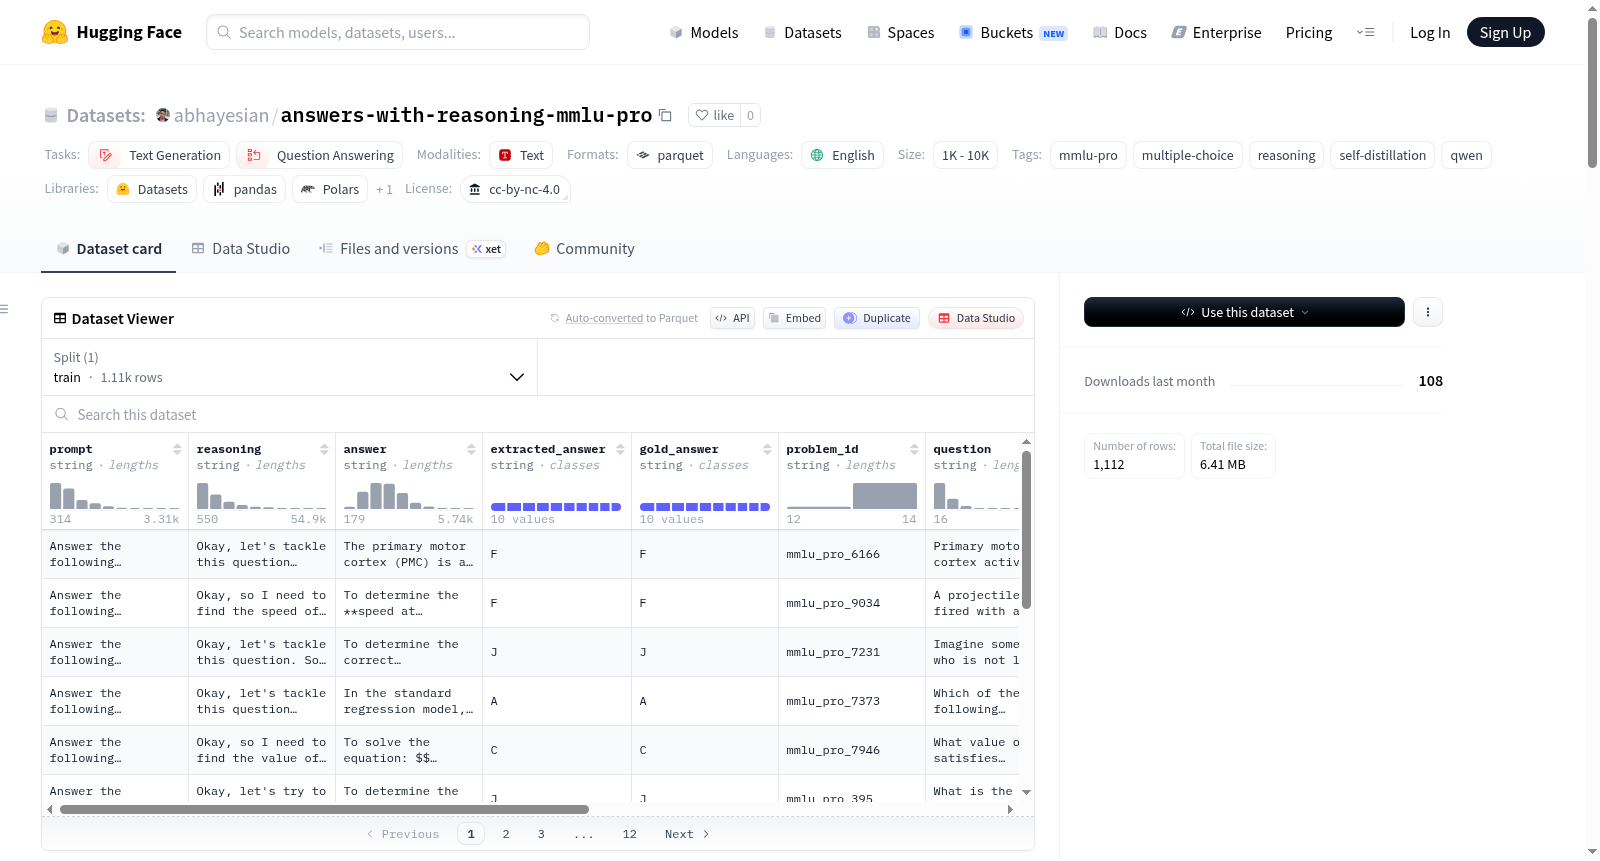
abhayesian/answers-with-reasoning-mmlu-pro
收藏资源简介:
该数据集名为answers-with-reasoning-mmlu-pro,是使用Qwen/Qwen3-8B模型(指令模式,开启推理)在TIGER-Lab/MMLU-Pro数据集上生成的自我蒸馏rollouts,仅保留了最终答案与黄金解决方案匹配的rollouts。数据集包含1474个训练样本,每个样本包含模型的完整推理轨迹(包括<think>...</think>部分和最终答案)。数据集用于项目Eliciting "Trying Hard": Does Reasoning Generalize Across Domains?,并与其他两个兄弟数据集(数学和代码领域)一起使用。采样设置包括模型为Qwen/Qwen3-8B,启用思考模式,温度为0.6,top_p为0.95,每个问题一个样本。数据集还包含了详细的模式描述、接受过滤器条件、评分标准、统计数据和注意事项。
The dataset is named answers-with-reasoning-mmlu-pro, which consists of self-distilled rollouts generated by the `Qwen/Qwen3-8B` model (instruct mode, reasoning ON) on the **TIGER-Lab/MMLU-Pro** dataset, filtered to keep only rollouts whose final answer matches the gold solution. It contains 1474 training examples, each including the models full reasoning trace (both the `<think>...</think>` section and the final answer). This dataset is part of the project *Eliciting "Trying Hard": Does Reasoning Generalize Across Domains?* and is used alongside two sibling datasets (math and code domains). Sampling settings include the model `Qwen/Qwen3-8B`, `enable_thinking=True`, `temperature=0.6`, `top_p=0.95`, and one sample per problem. The README also provides detailed schema descriptions, acceptance filter criteria, grading standards, statistics, and caveats.