MedAlign
收藏资源简介:
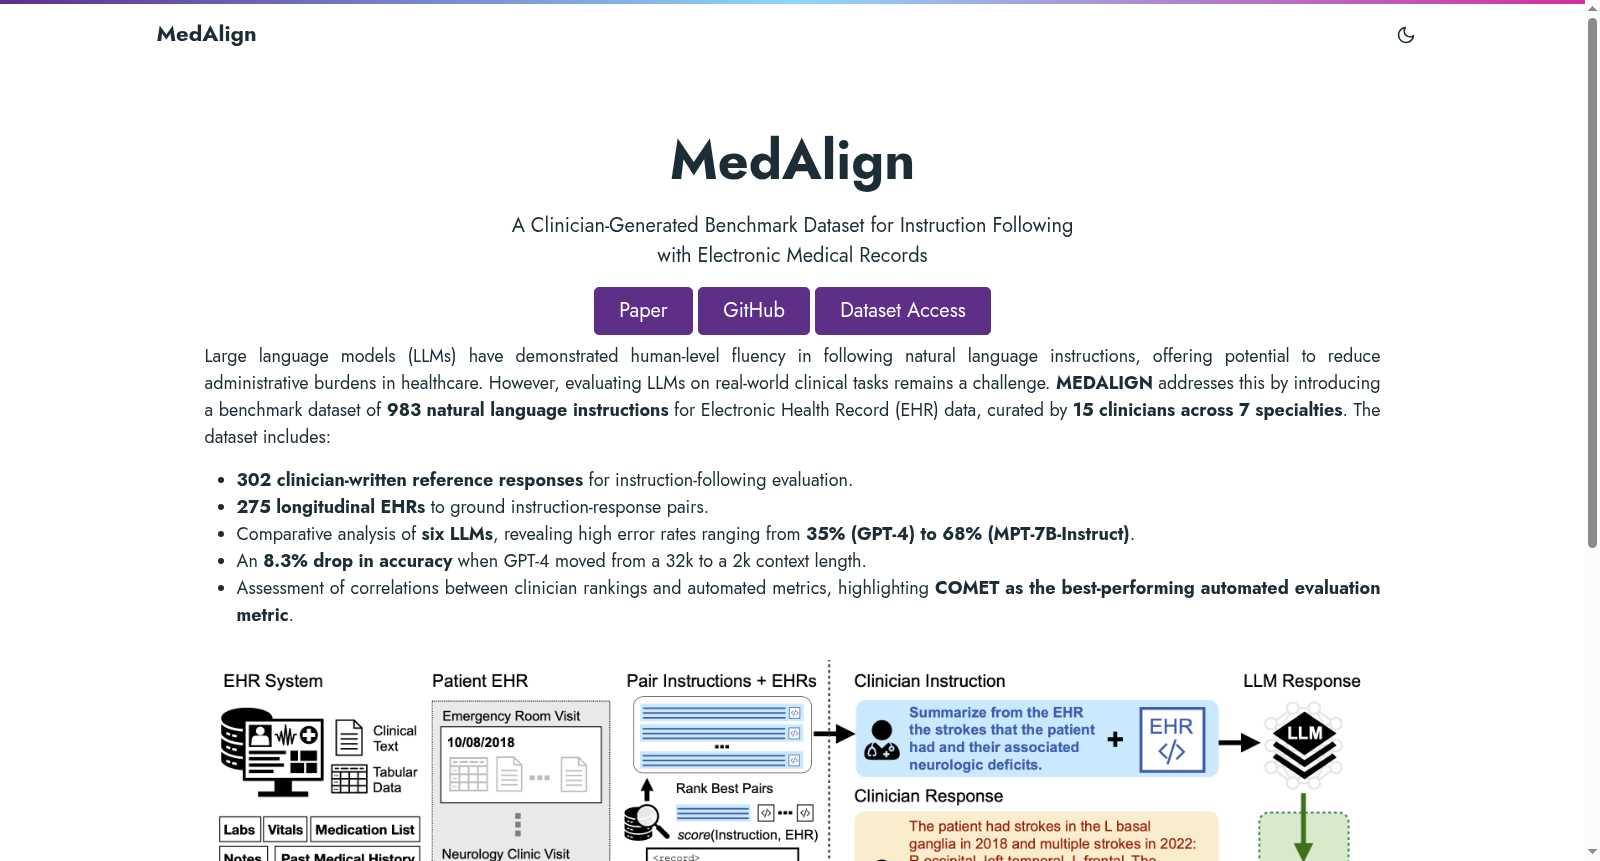
MedAlign数据集是由斯坦福大学医学院的15名临床医生生成的,专门设计用于评估大型语言模型(LLMs)在处理电子健康记录(EHR)数据时的表现。该数据集包含983条自然语言指令,覆盖7个医学专业,旨在模拟临床环境中医生可能遇到的复杂信息需求和文档负担。数据集不仅包括指令,还提供了303条指令的临床医生编写的参考答案和276个纵向EHR,以便于评估LLMs的响应质量。MedAlign数据集的开发是为了解决现有EHR相关数据集未能充分捕捉临床医生实际工作中的信息需求和文档复杂性的问题。通过此数据集,研究者可以更准确地评估和改进LLMs在医疗领域的应用,从而减轻医生的行政负担,提高医疗质量。
The MedAlign dataset was generated by 15 clinicians from Stanford University School of Medicine, and is specifically designed to evaluate the performance of large language models (LLMs) when processing electronic health record (EHR) data. It contains 983 natural language instructions spanning 7 medical specialties, aiming to simulate the complex information needs and documentation burdens that clinicians may encounter in clinical settings. In addition to the instructions, the dataset also provides clinician-written reference answers for 303 of these instructions and 276 longitudinal EHRs, to facilitate the evaluation of LLM response quality. The MedAlign dataset was developed to address the gap that existing EHR-related datasets fail to fully capture the information needs and documentation complexity encountered in clinicians' actual clinical work. With this dataset, researchers can more accurately evaluate and improve the application of LLMs in the medical field, thereby alleviating clinicians' administrative burdens and enhancing healthcare quality.