semeval-stance-conversations
收藏资源简介:
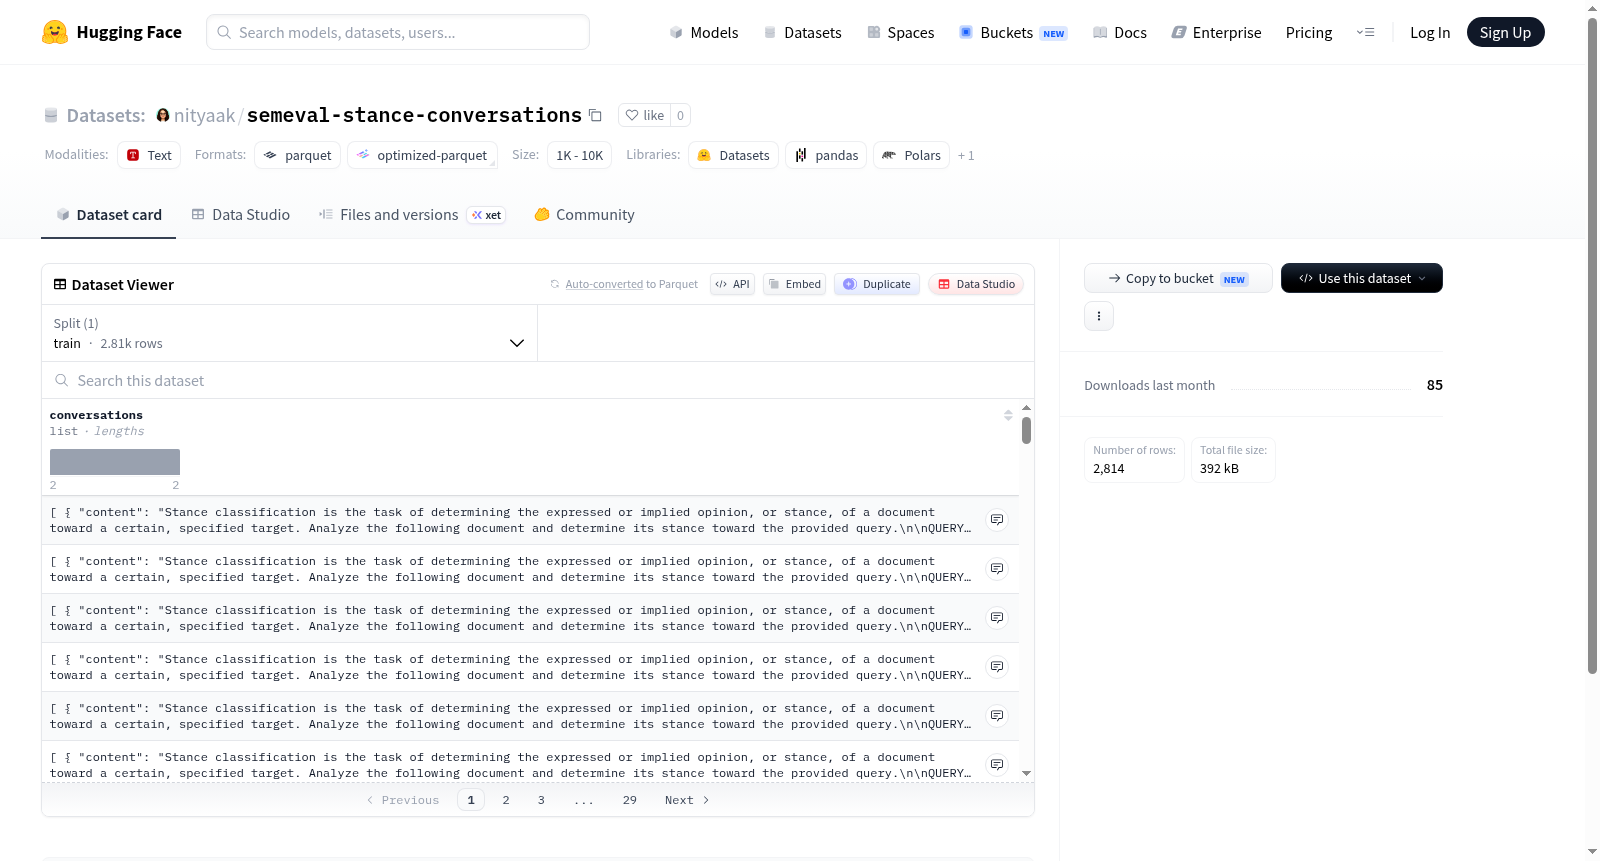
该数据集包含一个对话格式的数据集,专门用于训练和评估对话系统模型。数据集的核心结构为conversations字段,该字段是一个列表,其中每个元素代表对话中的一轮发言,包含两个关键属性:content(字符串类型,存储发言的具体文本内容)和role(字符串类型,标识发言者的角色,例如user或assistant)。数据集仅提供训练集(train split),共包含2,814个对话样本。数据集的原始下载大小约为389KB,加载处理后的总大小约为2.76MB。基于其数据结构,该数据集适用于自然语言处理领域的对话生成、对话理解、聊天机器人训练等相关任务。
This dataset is a conversation-formatted dataset specifically designed for training and evaluating dialogue system models. The core structure of the dataset is the 'conversations' field, which is a list. Each element in this list represents a single dialogue turn, containing two key attributes: 'content' (string type, storing the specific textual content of the utterance) and 'role' (string type, identifying the speaker's role, such as 'user' or 'assistant'). This dataset only provides the training split, containing a total of 2,814 dialogue samples. The original download size of the dataset is approximately 389 KB, and the total size after loading and processing is about 2.76 MB. Based on its data structure, this dataset is applicable to natural language processing tasks including dialogue generation, dialogue understanding, and chatbot training.
数据集概述
基本信息
- 数据集名称: semeval-stance-conversations
- 页面地址: https://huggingface.co/datasets/nityaak/semeval-stance-conversations
特征
- conversations: 对话列表,包含以下字段:
- content: 字符串类型,表示对话内容
- role: 字符串类型,表示对话角色
数据集划分
- train: 训练集
- 样本数量: 2,814
- 字节大小: 2,756,111 字节
数据集大小
- 下载大小: 388,995 字节
- 总大小: 2,756,111 字节
配置
- 配置名称: default
- 数据文件: 训练集数据位于
data/train-*路径下