dev_set_v2_g1_a1_top16_32b_step600_20260820_171320
收藏资源简介:
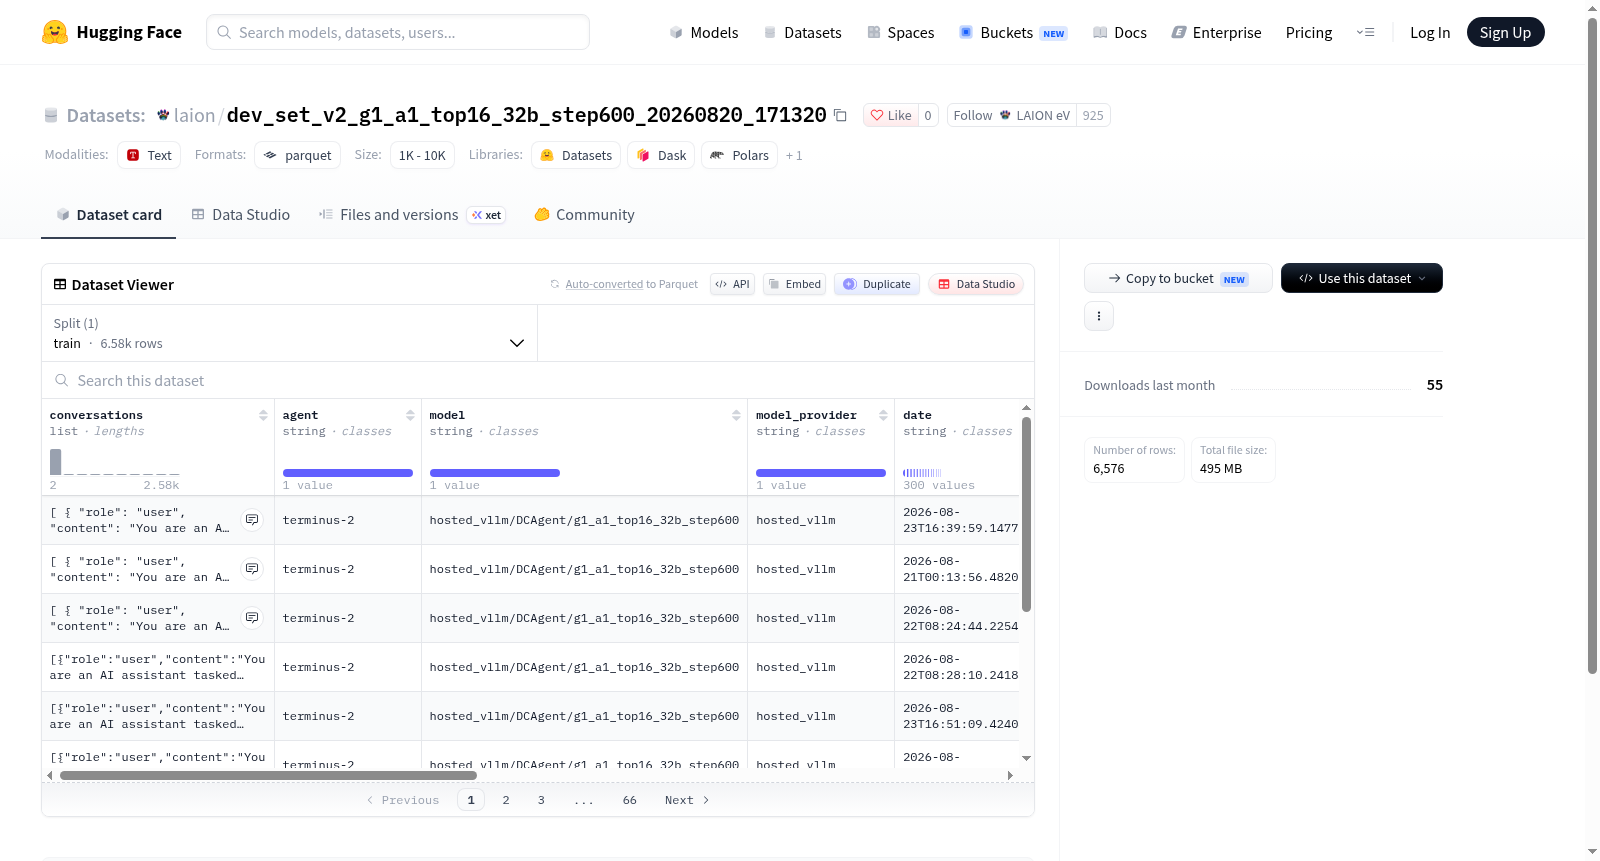
该数据集是一个多轮对话记录集合,主要面向模型评估与对话分析任务。每条数据包含一个完整的对话历史(conversations字段,由role和content组成),以及对应的代理(agent)、模型(model)及其提供方(model_provider)、日期(date)、任务(task)、实验轮次(episode)、运行ID(run_id)、试验名称(trial_name)、结果(result)、验证器输出(verifier_output)和追踪来源(trace_source)。数据集规模为训练集6576个样本,总大小约556MB。该数据集可用于研究不同模型在给定任务下的对话能力、结果分析以及可追溯性实验。
This dataset is a collection of multi-turn conversation records, primarily designed for model evaluation and dialogue analysis tasks. Each data entry contains a complete conversation history (conversations field, composed of role and content), along with the corresponding agent, model and its provider, date, task, episode, run_id, trial_name, result, verifier_output, and trace_source. The dataset has a training set of 6576 samples, with a total size of approximately 556MB. It can be used to study the conversational capabilities of different models under given tasks, result analysis, and traceability experiments.
数据集概述
该数据集名为 laion/dev_set_v2_g1_a1_top16_32b_step600_20260820_171320,托管于 Hugging Face 平台。
基本信息
- 数据集大小:下载大小为 494,683,499 字节(约 494.7 MB),解压后数据集大小为 556,358,182 字节(约 556.4 MB)。
- 数据划分:仅包含一个训练集(train),共 6,576 条样本。
- 数据格式:数据文件存储于
data/train-*路径下,采用分片存储方式。
数据字段
每条样本包含以下字段:
- conversations:对话列表,每个对话项由
role(角色)和content(内容)两个字符串字段组成,用于存储多轮对话。 - agent(字符串):代理标识。
- model(字符串):模型名称。
- model_provider(字符串):模型提供方。
- date(字符串):日期信息。
- task(字符串):任务类型。
- episode(字符串):回合编号。
- run_id(字符串):运行标识。
- trial_name(字符串):试验名称。
- result(字符串):结果信息。
- verifier_output(字符串):验证器输出。
- trace_source(字符串):追踪来源。
数据特点
- 该数据集主要用于包含多轮对话记录的开发集(dev set),同时附带丰富的元数据(如模型、任务、运行信息等)。
- 数据规模相对较小(6,576 条样本),但每条样本可能包含较长的对话内容及附加信息。