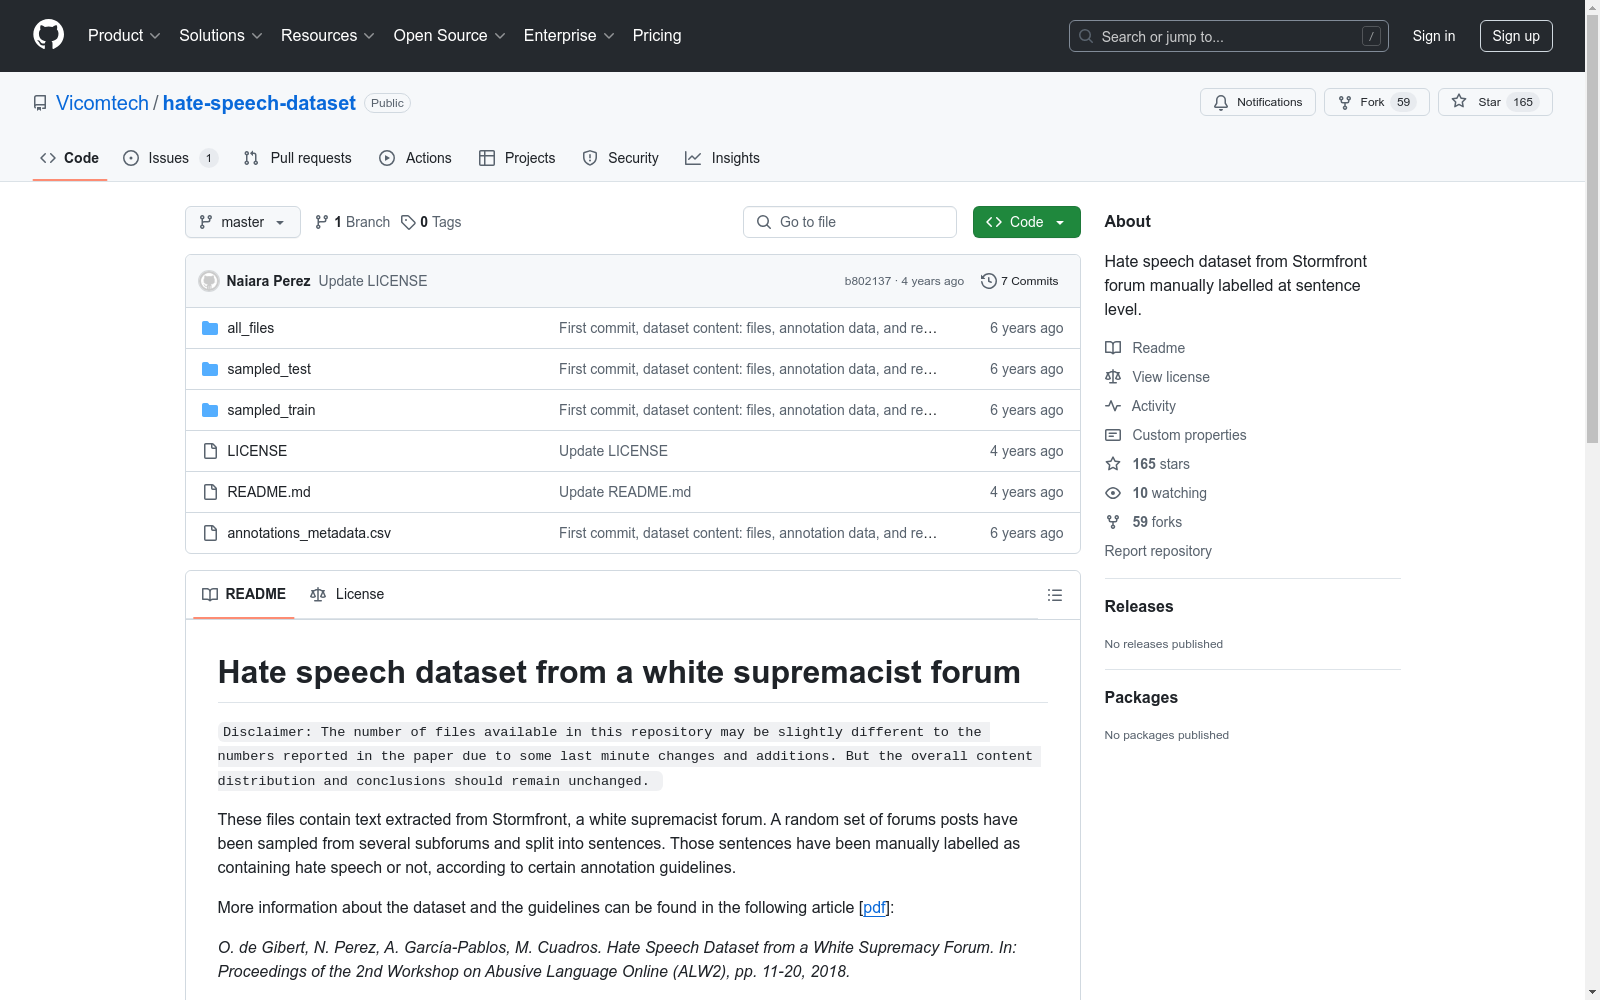
Hate Speech Dataset from a White Supremacy Forum
收藏资源简介:
该数据集包含从白人至上主义论坛Stormfront提取的文本,这些文本被分割成句子并手动标注是否包含仇恨言论。数据集用于研究仇恨言论的识别和分析。
This dataset comprises texts extracted from the white supremacist forum Stormfront, which have been segmented into sentences and manually annotated for the presence of hate speech. The dataset is utilized for research on the identification and analysis of hate speech.
Hate Speech Dataset from a White Supremacist Forum
数据集描述
- 来源:数据集包含从Stormfront论坛提取的文本,该论坛是一个白人至上主义论坛。
- 内容:随机抽样的论坛帖子被分割成句子,并根据特定的标注指南手动标注为包含仇恨言论或不包含。
数据集结构
- all_files:包含所有论坛帖子的文件夹。每个文件包含一个句子,文件名格式为commentID_sentenceNumber.txt。
- sampled_train:从all_files中抽取的平衡数据集(包含"hate"和"noHate"类别),用于实验。
- sampled_test:从all_files中抽取的平衡数据集(包含"hate"和"noHate"类别),用于实验。
- annotations_metadata.csv:包含上述文件夹中每个文件的实际标签,以及标注者做出决策所需的额外上下文量、用户ID和子论坛ID。
引用信息
若在工作中使用此数据集,请按以下方式引用:
@inproceedings{gibert2018hate, title = "{Hate Speech Dataset from a White Supremacy Forum}", author = "de Gibert, Ona and Perez, Naiara and Garc{\i}a-Pablos, Aitor and Cuadros, Montse", booktitle = "Proceedings of the 2nd Workshop on Abusive Language Online ({ALW}2)", month = oct, year = "2018", address = "Brussels, Belgium", publisher = "Association for Computational Linguistics", url = "https://www.aclweb.org/anthology/W18-5102", doi = "10.18653/v1/W18-5102", pages = "11--20", }