sample-dataset-test-energy-pack
收藏资源简介:
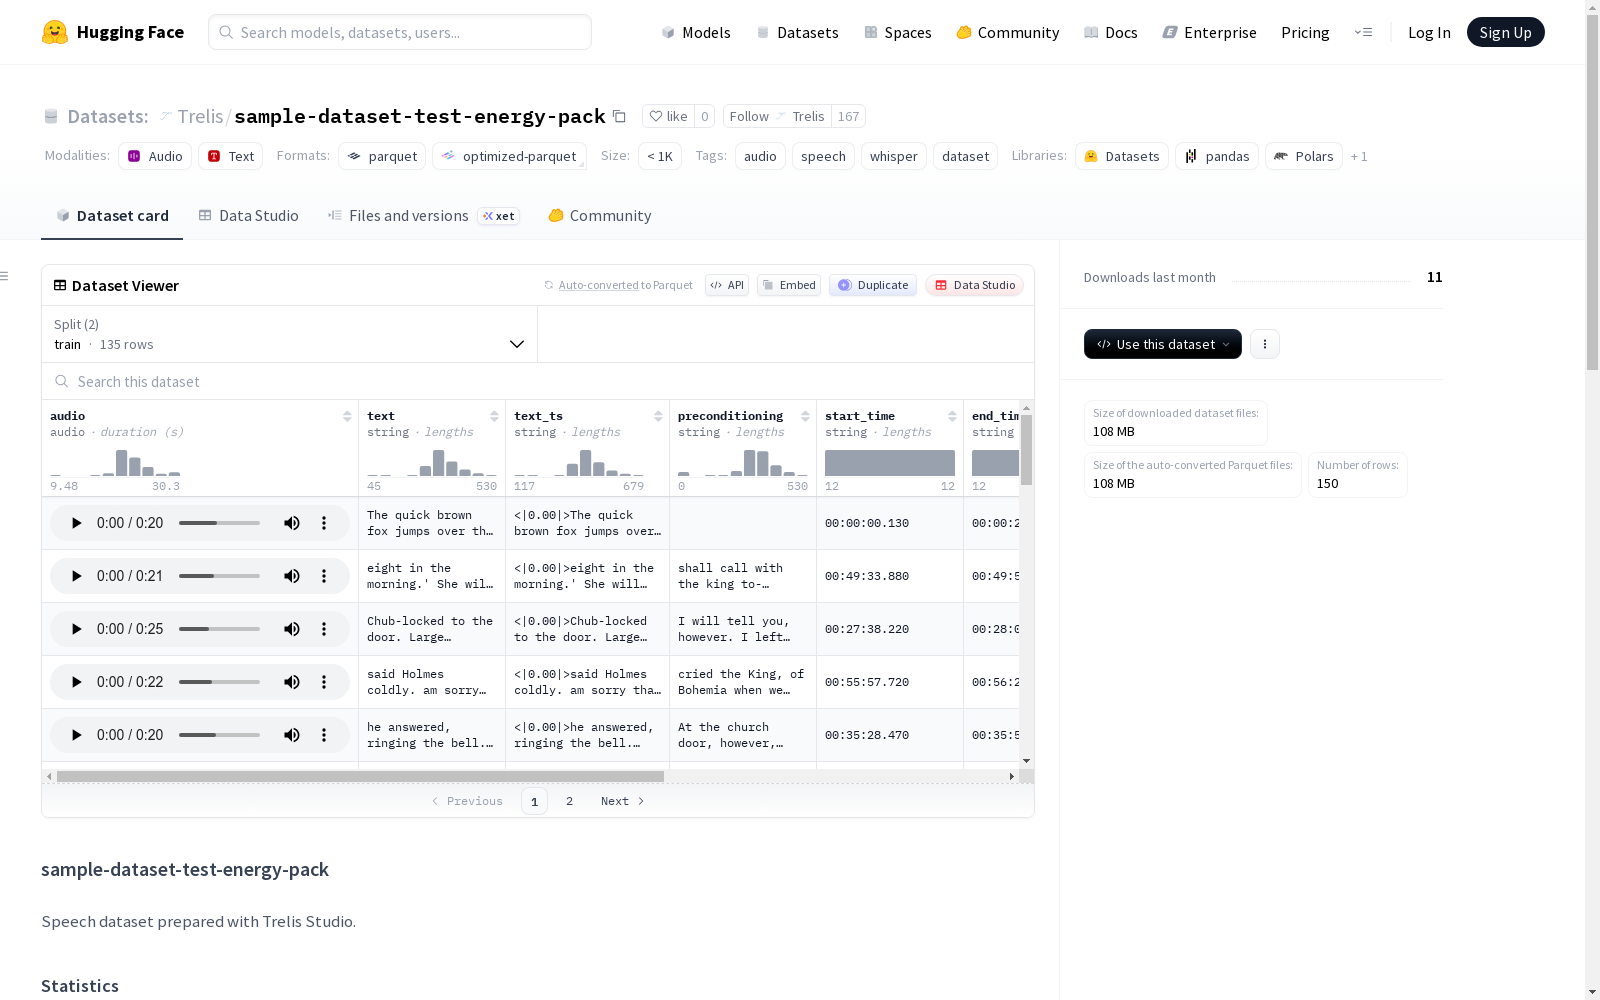
sample-dataset-test-energy-pack 是一个专门为 Whisper 模型训练准备的语音数据集,由 Trelis Studio 处理制作。该数据集包含 6 个源文件,共计 135 个训练样本和 15 个验证样本,总时长为 62.6 分钟。数据集中的音频片段经过 VAD(语音活动检测)处理,去除了静音部分,仅保留语音区域(16kHz 采样率)。主要字段包括:音频片段、纯文本转录、带 Whisper 时间戳标记的转录、片段在原音频中的起止时间、语音持续时间、词级时间戳以及源文件名。该数据集特别适用于 Whisper 模型的时间戳训练,建议采用双桶训练策略:50%使用纯文本转录,50%使用带时间戳标记的转录。
The sample-dataset-test-energy-pack is a speech dataset dedicated to Whisper model training, curated and produced by Trelis Studio. This dataset comprises 6 source files, with a total of 135 training samples and 15 validation samples, with an overall duration of 62.6 minutes. The audio clips in this dataset have been processed via VAD (Voice Activity Detection), where silent segments are removed and only speech regions are preserved, with a sampling rate of 16 kHz. Its core fields include: audio clips, raw text transcriptions, transcriptions with Whisper timestamps, start and end timestamps of the clip within the original audio, speech duration, word-level timestamps, and source file names. This dataset is particularly suitable for timestamp training of Whisper models, and the two-bucket training strategy is recommended: 50% of the training corpus uses raw text transcriptions, while the other 50% uses transcriptions with Whisper timestamps.