
Cloud Incident Reports Dataset
收藏资源简介:
该数据集由阿姆斯特丹自由大学等机构联合构建,收录了AWS、Azure和GCP三大云服务商2016-2024年间的3087份事故报告。数据集平均每份报告含500余词,包含服务名称、地理位置、时间戳等10类结构化字段,通过网页爬取和人工标注方式构建。研究团队采用K-means聚类抽样和多人交叉标注流程确保数据质量,该数据集可用于云计算可靠性分析、根因诊断等AIOps场景,为LLM在IT运维领域的结构化信息抽取提供基准测试资源。
This dataset was jointly constructed by institutions including Vrije Universiteit Amsterdam and other partners through web crawling and manual annotation. It includes 3087 incident reports from three leading cloud service providers, AWS, Azure and GCP, covering the period from 2016 to 2024. Each report contains an average of over 500 words, and encompasses 10 categories of structured fields such as service name, geographic location and timestamp. The research team adopted K-means clustering sampling and multi-person cross-annotation procedures to ensure data quality. This dataset can be applied to AIOps scenarios such as cloud computing reliability analysis and root cause diagnosis, and provides benchmark resources for structured information extraction tasks of Large Language Models (LLMs) in the field of IT operations.
数据集概述
数据集来源
- 数据集存储地址:https://zenodo.org/records/14010282
数据集内容与结构
该数据集用于支持“使用大型语言模型(LLM)进行云事件报告数据提取”的研究。数据集包含来自主要云服务提供商的事件报告。
数据目录结构
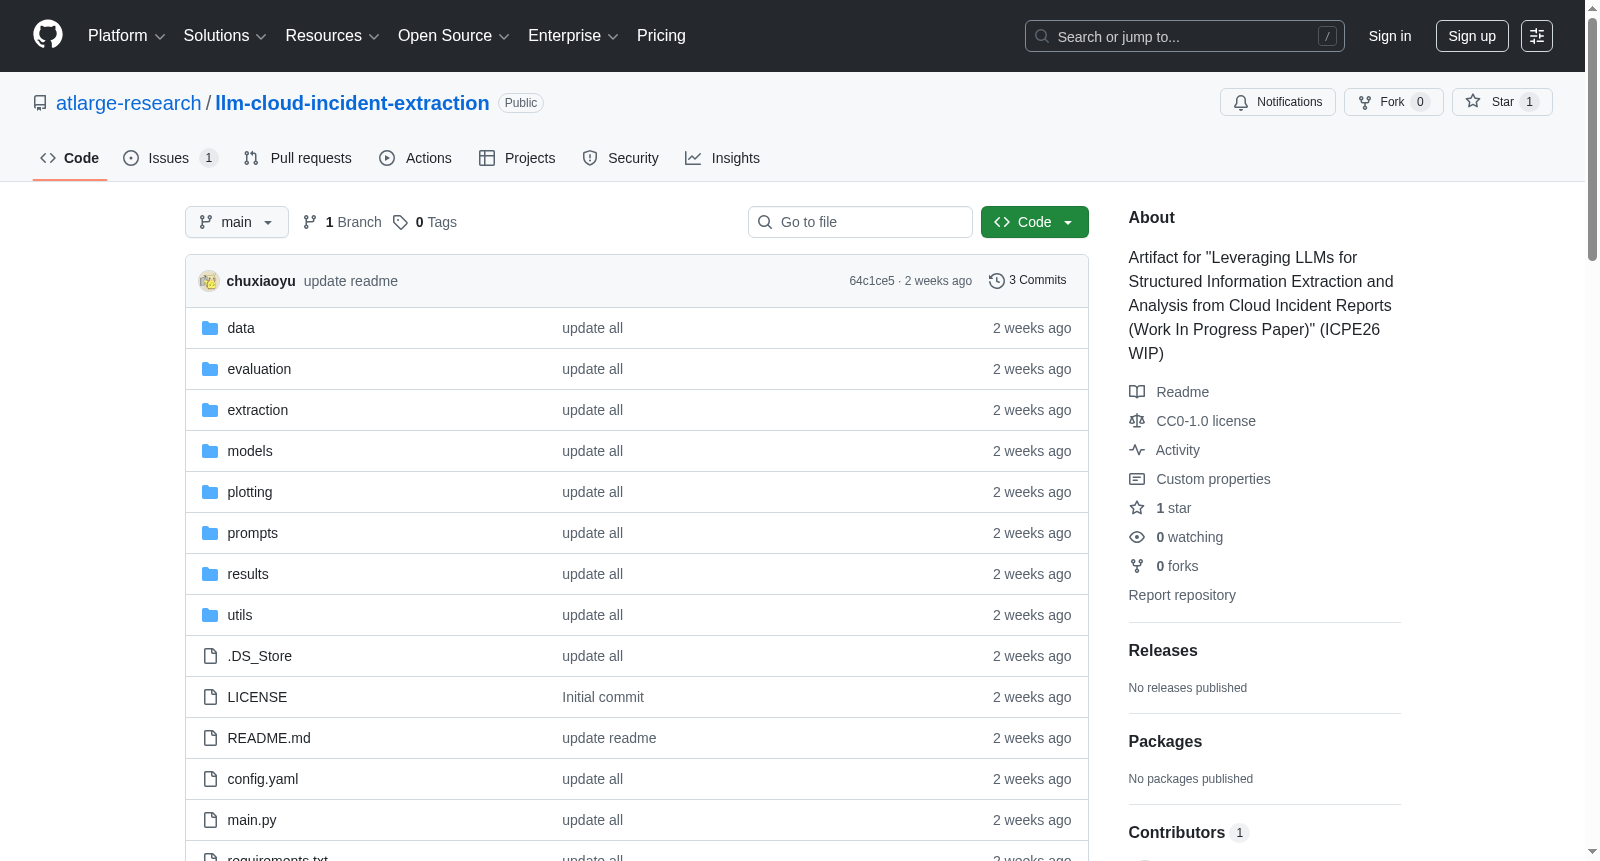
数据集文件按处理阶段组织在 data/ 目录下:
1_raw_data/:原始事件报告。2_clean_data/:经过处理的干净数据。3_sample_data/:通过K-means聚类采样的数据。4_label_data/:用于评估的标注数据。
数据覆盖范围
数据涵盖以下云服务提供商:
- AWS
- AZURE
- GCP
数据处理与用途
- 数据处理脚本
data_process.py用于完成数据清洗、处理和采样。 - 该数据集旨在用于评估不同提示策略下,多种大型语言模型(如GPT、Claude、Gemini)从云事件报告中提取信息的性能。
- 数据集支持完整的实验流程,包括数据提取、结果评估以及论文中图表和表格的生成。
相关文件
- 项目配置文件:
config.yaml(包含API密钥和模型设置)。 - 项目依赖:
requirements.txt。
- 1Leveraging LLMs for Structured Information Extraction and Analysis from Cloud Incident Reports (Work In Progress Paper)阿姆斯特丹自由大学; 阿姆斯特丹大学; 代尔夫特理工大学 · 2026年


