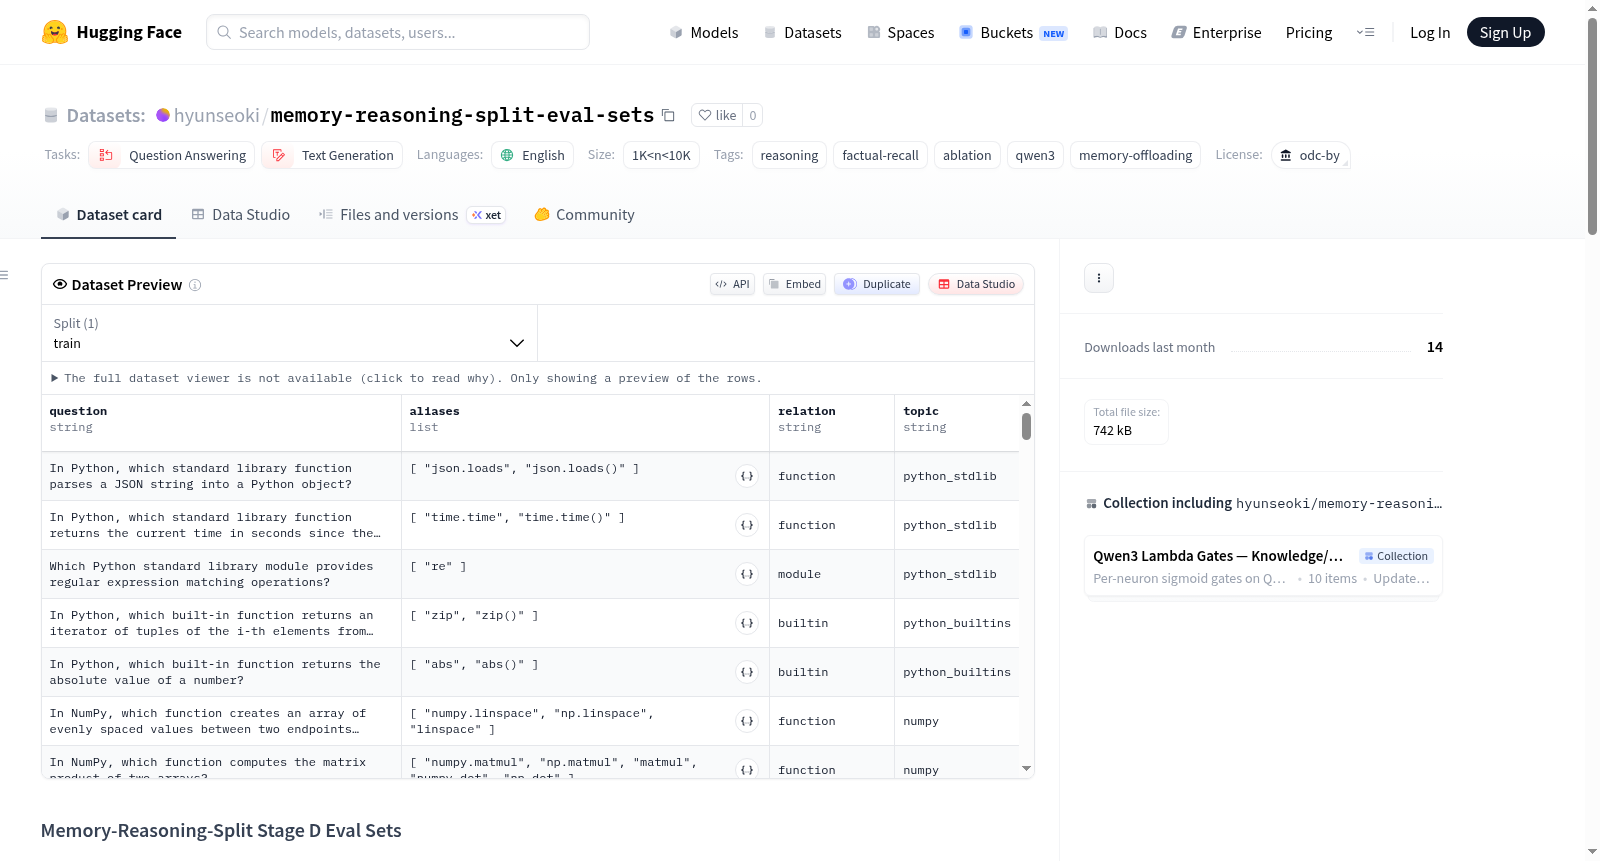
memory-reasoning-split-eval-sets
收藏资源简介:
Memory-Reasoning-Split Stage D Eval Sets 是一个用于测量语言模型在选择性遗忘不同领域知识后,领域事实保留与推理能力之间权衡的评估数据集。数据集包含五个主要文件:popqa_general.jsonl(1232行,通用领域闭卷问答)、math_facts.jsonl(100行,手工整理的数学常数、定理和公式)、code_api_facts.jsonl(101行,手工整理的编程API签名和琐事)、sciq.jsonl(500行,SciQ测试集的子集)和humaneval_prompts.jsonl(164行,HumanEval测试集的完整分割)。所有事实行共享统一的模式,包括问题、别名、关系、主题和来源数据集字段。数据集适用于闭卷事实评估和代码可用性测试,旨在与特定的保留语料库和遗忘语料库配对使用。数据集许可信息包括CC BY-NC 3.0(SciQ)、MIT(PopQA和HumanEval)和CC BY-SA 4.0(手工整理部分)。
The Memory-Reasoning-Split Stage D Eval Sets is an evaluation dataset constructed to measure the trade-off between domain-specific factual retention and reasoning abilities of language models following their selective forgetting of knowledge across various domains. This dataset includes five primary files: popqa_general.jsonl (1232 lines, general-domain closed-book question answering), math_facts.jsonl (100 lines, manually curated mathematical constants, theorems, and formulas), code_api_facts.jsonl (101 lines, manually curated programming API signatures and trivia), sciq.jsonl (500 lines, a subset of the SciQ test set), and humaneval_prompts.jsonl (164 lines, a full split of the HumanEval test set). All fact entries follow a unified schema that includes the fields: question, alias, relation, subject, and source dataset. This dataset is suitable for closed-book factual evaluation and code availability testing, and is intended to be paired with specific retention corpora and forgetting corpora. The dataset's licensing information includes CC BY-NC 3.0 for SciQ, MIT License for PopQA and HumanEval, and CC BY-SA 4.0 for the manually curated portions.
Memory-Reasoning-Split Stage D Eval Sets 数据集概述
数据集基本信息
- 许可证: odc-by
- 任务类别: 问答、文本生成
- 语言: 英语
- 标签: 推理、事实回忆、消融、qwen3、内存卸载
- 数据集名称: Memory-Reasoning-Split Stage D Eval Sets
- 数据规模: 1K<n<10K
数据集描述
本数据集是用于评估在 memory_reasoning_split Stage D/E 遗忘语料消融中,各领域事实退化与推理保留之间权衡的精选闭卷评估集。所有事实行共享统一的模式,以便单一评估器进行评分。
统一模式如下:
{ "question": str, "aliases": list[str], # 任何标准化的别名匹配都计为命中 "relation": str, "topic": str, "source_dataset": str (仅 popqa_general / sciq 子集;自定义分割省略) }
文件构成
| 文件 | 行数 | 类型 | 来源 |
|---|---|---|---|
popqa_general.jsonl |
1232 | 通用领域闭卷问答 | https://huggingface.co/datasets/akariasai/PopQA 测试子集,重塑为包含别名、关系和主题的统一模式 |
math_facts.jsonl |
100 | 手动整理的闭卷事实 | 常数、定理、公式(微积分、线性代数、概率、几何、三角学、数论等) |
code_api_facts.jsonl |
101 | 手动整理的闭卷事实 | Python/NumPy/PyTorch/Pandas/JS/C++/Rust/Go/SQL API 签名以及 shell/git/HTTP 琐事 |
sciq.jsonl |
500 | https://huggingface.co/datasets/allenai/sciq test 分割的子集,经过重塑 |
转换为统一的问答模式 |
humaneval_prompts.jsonl |
164 | 完整的 https://huggingface.co/datasets/openai_humaneval test 分割 |
提示 + 规范解决方案 + 测试 + 入口点 |
设计说明
- 选择
popqa_general的原因:Stage D 的遗忘语料源自维基百科,因此最自然的“你是否破坏了通用领域事实回忆?”探针是通用主题的 PopQA(1232 行,涵盖如occupation、place_of_birth、capital等关系)。它与 https://huggingface.co/datasets/hyunseoki/popqa-mini-ner-knowledge-masks 处的 NER 掩码训练语料配对使用。
预期用途
本数据集旨在作为即插即用的评估套件,用于测量在不同遗忘语料上进行选择性遗忘训练的适配器的各领域事实保留和代码可用性。它与以下资源配对使用:
- 保留语料:https://huggingface.co/datasets/hyunseoki/qwen3-0p6b-openthoughts-self-distill-10k
- NER 掩码遗忘语料:https://huggingface.co/datasets/hyunseoki/popqa-mini-ner-knowledge-masks
- 去重索引:https://huggingface.co/datasets/hyunseoki/openthoughts3-dedup-index
所有资产均归类于 https://huggingface.co/collections/hyunseoki/qwen3-lambda-gates-knowledge-reasoning-disentanglement-69e20c8e64960042ed4c3159 集合下。
许可证与归属
- SciQ 行 © Allen AI (CC BY-NC 3.0)。
- HumanEval 行 © OpenAI (在
openai_humaneval数据集卡片中根据 MIT 许可证发布;请遵循其条款)。 - PopQA 行 © Asai et al. (MIT 许可证)。
- 手动整理的
math_facts和code_api_facts采用 CC BY-SA 4.0 许可证。