opencsg/Fineweb-Edu-Chinese-V2.3
收藏资源简介:
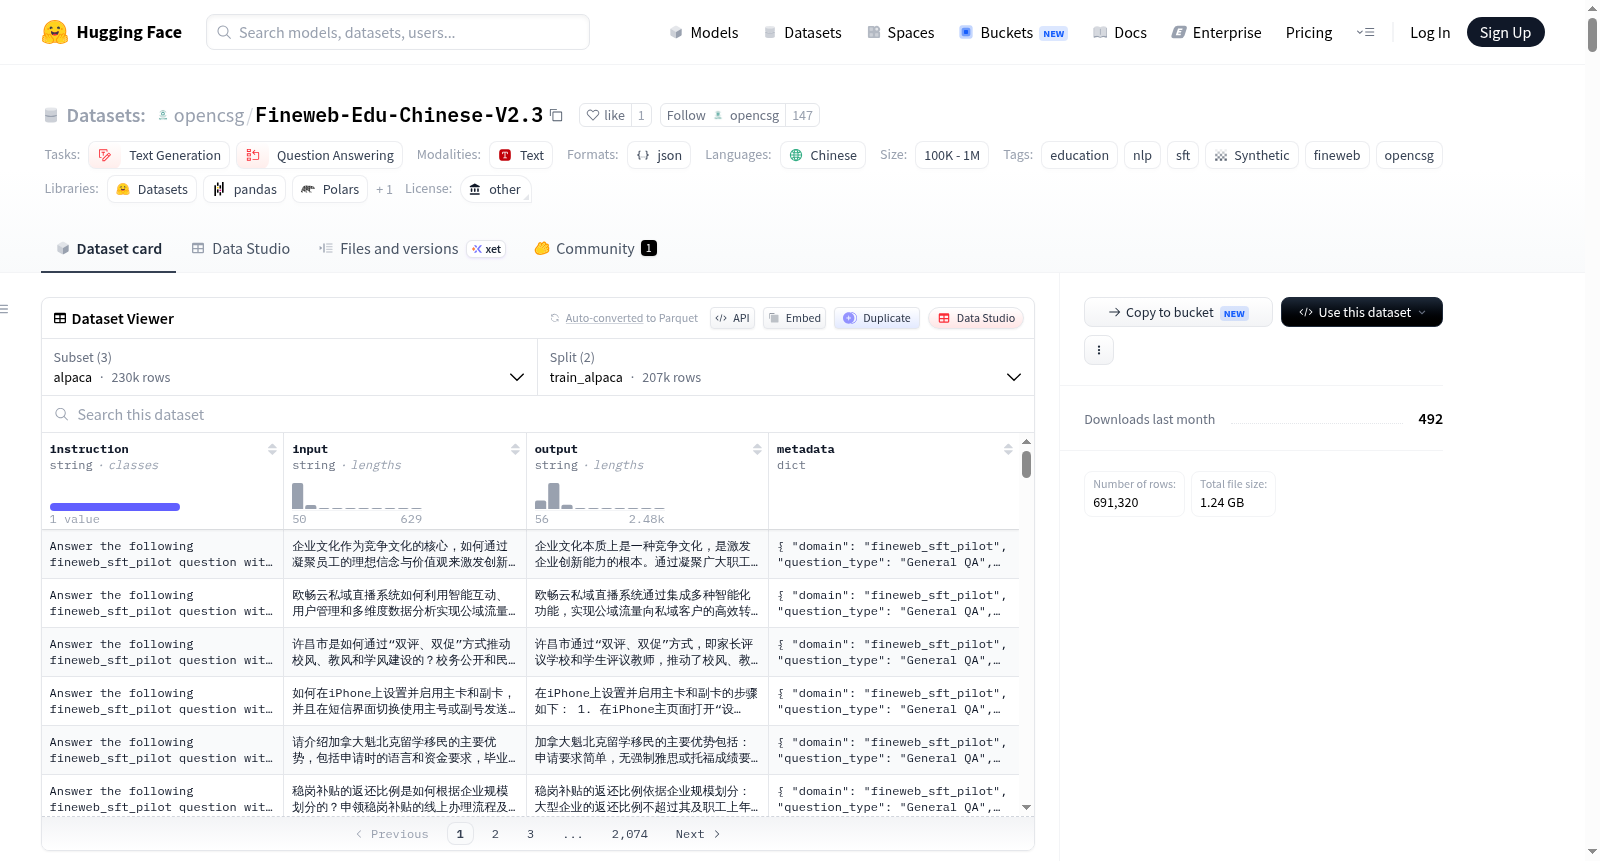
Chinese Fineweb Edu Dataset V2.3 是 OpenCSG 面向中文教育、知识问答、指令微调和文本生成场景构建的高质量中文教育 SFT 数据集。该版本包含 23.04 万条高质量中文教育 QA pairs,并将同一批问答对发布为 Alpaca、Messages、Messages-no-system 三种训练格式。V2.3 是在 V2.2 基础上的质量升级版本,提高了源文本进入生成环节的门槛,并优化了问答生成与过滤逻辑。数据构建从约 2.3T Parquet / raw corpus 中进行高召回候选筛选,通过 GPT-4.1 mini 标注获得监督信号,基于 IEITYuan/Yuan-embedding-2.0-zh 训练中文源文本分类打分器进行排序与选择,最终由 GPT-4.1 mini 完成问答生成,并进行证据对齐、质量过滤和多格式导出。数据集旨在提供更适合直接进入监督微调流程的中文教育问答数据,提升中文教育回答能力、SFT训练输入纯度和训练格式接入便利性。
Chinese Fineweb Edu Dataset V2.3 is a high-quality Chinese educational SFT (Supervised Fine-Tuning) dataset developed by OpenCSG for Chinese education, knowledge question answering, instruction fine-tuning and text generation scenarios. This version includes 230,400 high-quality Chinese educational QA pairs, and releases the same set of Q&A pairs in three training formats: Alpaca, Messages, and Messages-no-system. V2.3 is a quality-upgraded iteration based on V2.2, which raises the threshold for source texts to enter the generation stage, and optimizes the Q&A generation and filtering logic. The dataset construction conducts high-recall candidate screening from approximately 2.3T Parquet/raw corpus, obtains supervision signals via GPT-4.1 mini annotation, trains a Chinese source text classification scorer based on IEITYuan/Yuan-embedding-2.0-zh for ranking and selection, and finally uses GPT-4.1 mini to complete Q&A generation, followed by evidence alignment, quality filtering and multi-format export. The dataset aims to provide Chinese educational Q&A data that is more suitable for direct integration into supervised fine-tuning workflows, and improve the performance of Chinese educational answering capabilities, the purity of SFT training inputs, and the convenience of accessing various training formats.