Codatta/MM-Food-100K
收藏资源简介:
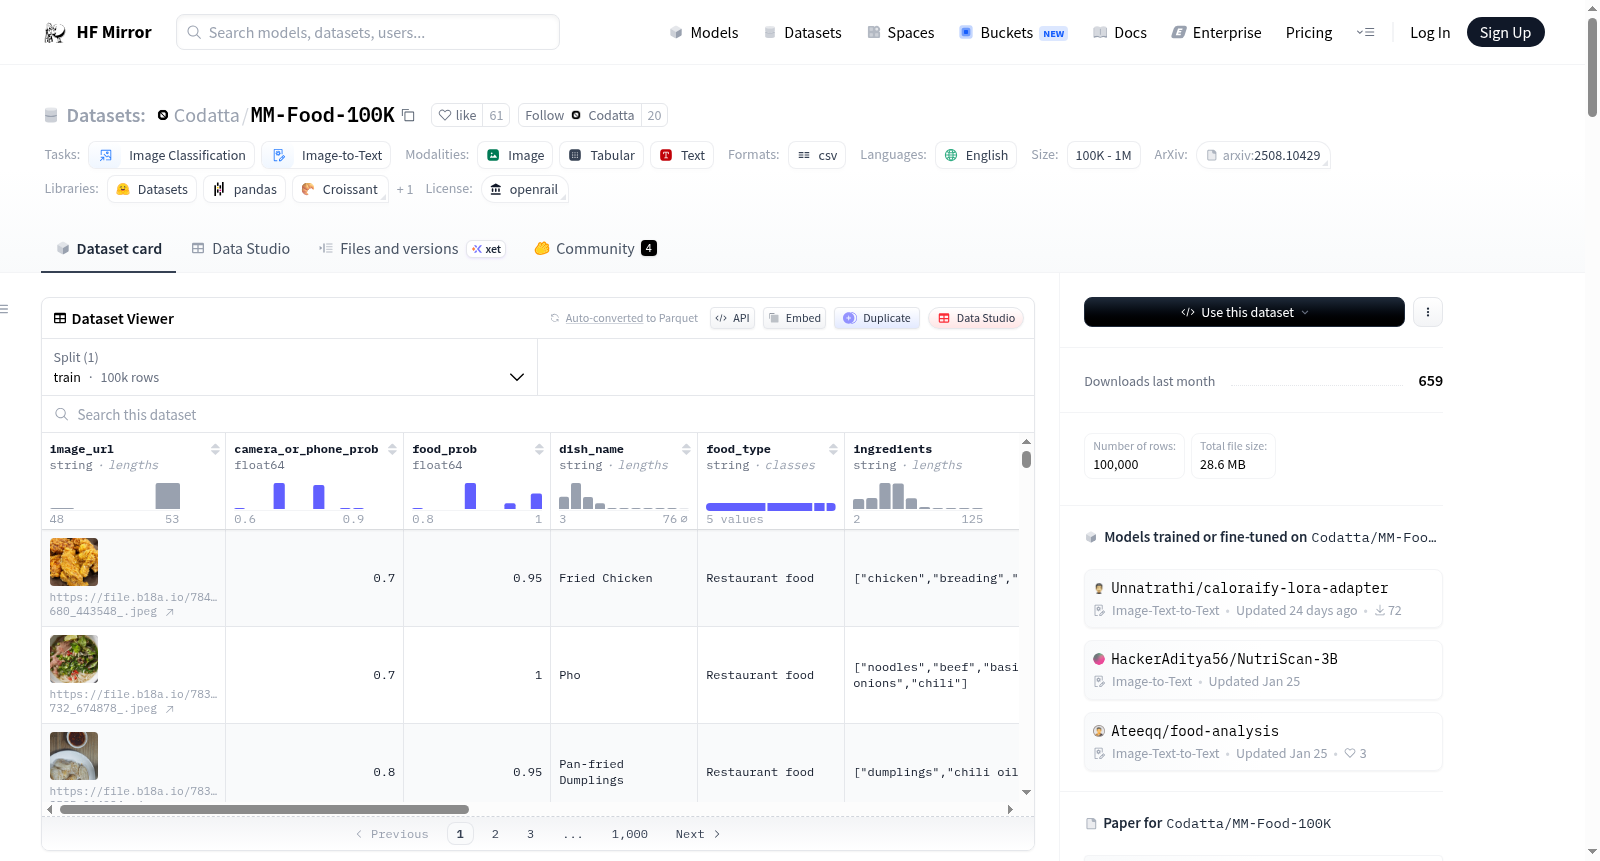
这是一个专门为计算机视觉任务设计的综合食品图像数据集,特别适用于食品识别、分类和营养分析。数据集包含高质量的食品图像和详细的元数据,旨在进行细粒度的食品分析。与传统的仅提供图像分类标签的数据集不同,该资源提供了多级结构化信息,支持更复杂的AI应用程序。每个数据记录都包括一个图像URL和相应的JSON格式的元数据,包含菜品名称、食品类型、配料、份量、营养信息、烹饪方法和图像来源概率等字段。数据集由10万张食品图像组成,涵盖了各种食品类型,包括自制食品、餐厅食品、生蔬果和包装食品。数据收集和标注过程采用了创新的混合标注方法,结合大规模众包数据、人工预标注和先进的AI模型,确保了数据集的高质量和准确性。数据集可用于食品识别和分类、营养评估、食谱推荐系统、健康管理、餐厅自动化和计算机视觉研究等应用。
This is a comprehensive food image dataset designed specifically for computer vision tasks, particularly food recognition, classification, and nutritional analysis. The dataset consists of high-quality food images and detailed metadata, designed for granular food analysis. Unlike traditional datasets that only provide image classification labels, our resource offers multi-level, structured information that supports more complex AI applications. Each data record includes an image URL and corresponding metadata in JSON format, containing fields such as dish name, food type, ingredients, portion size, nutritional profile, cooking method, and image source probability. The dataset is composed of 100,000 food images, covering various food types including homemade food, restaurant food, raw vegetables and fruits, and packaged food. The data collection and annotation process uses an innovative hybrid annotation method, combining large-scale crowdsourced data, human pre-annotation, and advanced AI models to ensure the high quality and accuracy of the dataset. The dataset can be used for food recognition and classification, nutritional estimation, recipe recommendation systems, health management, restaurant automation, and computer vision research applications.