setswana-sentiment
收藏资源简介:
DSFSI Setswana Sentiment是一个用于情感分析的数据集,包含3,555条Setswana语(ISO 639-3: `tsn`)的Twitter推文,由三位母语为Setswana的标注者进行标注。数据集提供了完整的标注时间戳、语言识别元数据以及每位标注者的标签,支持下游建模和标注质量研究。数据集分为训练集(2,762条)、验证集(346条)、测试集(346条)和一个完整配置(3,555条),其中训练/验证/测试集仅包含三种核心情感类别(积极、消极、中性),并按共识标签以80/10/10的比例分层分配。数据集还包含标注者标签、时间戳、共识类型等元数据,适用于情感分类器的训练与评估,以及标注质量研究。数据预处理包括用户名、提及、URL等敏感信息的替换,以及大小写归一化。数据集的主要局限性包括Twitter数据的特定性、标签分布不均衡(消极和中性标签占主导),以及标注时间跨度对一致性的影响。数据集采用Creative Commons Attribution 4.0 International (CC BY 4.0)许可发布。
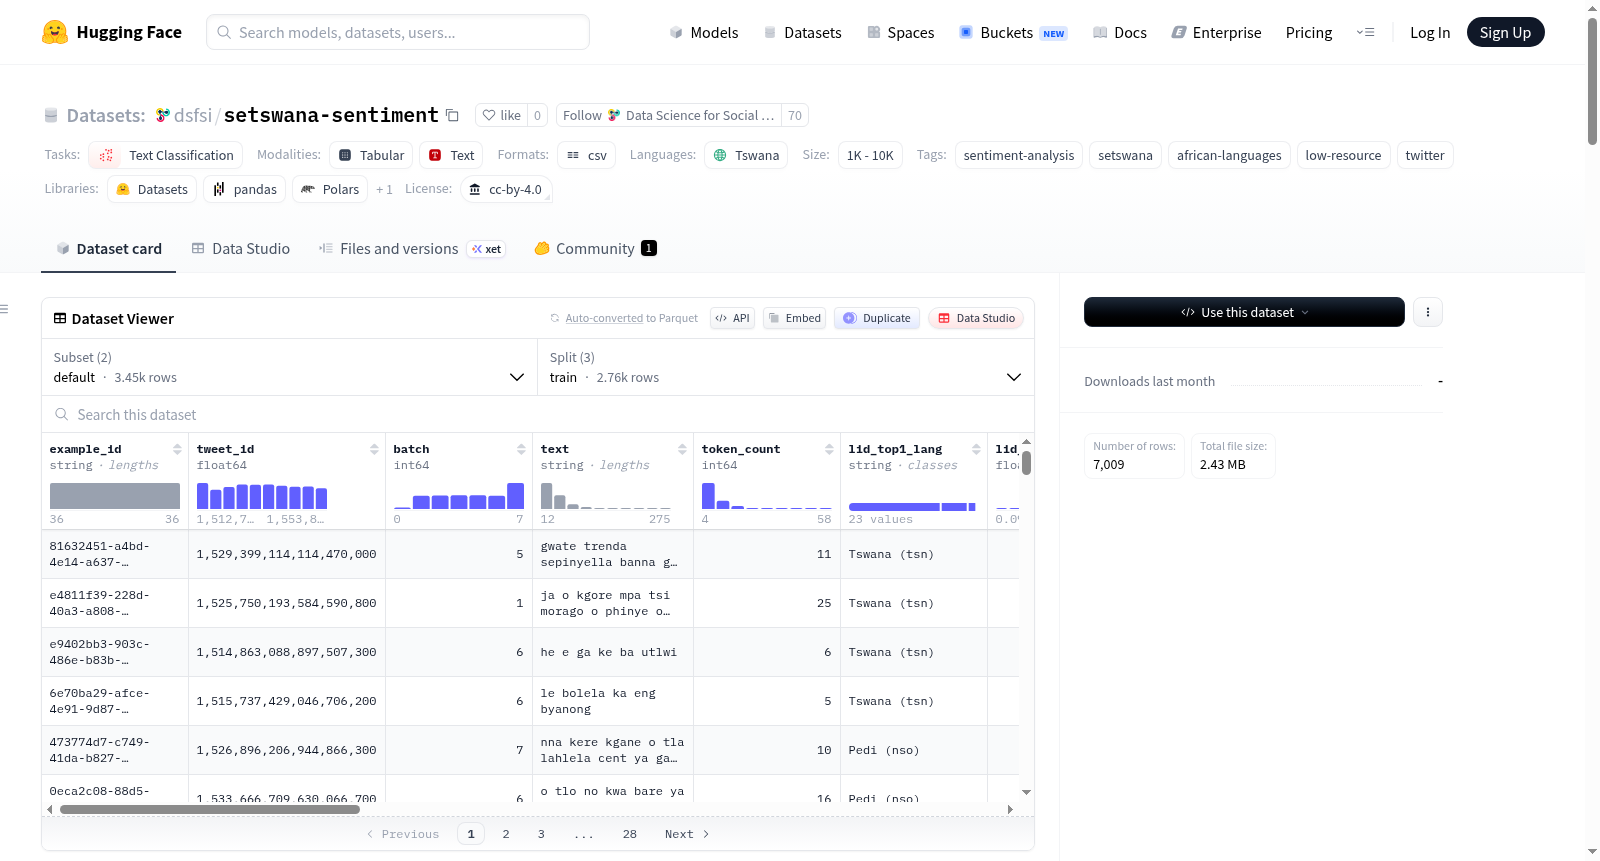
DSFSI Setswana Sentiment is a dataset for sentiment analysis, containing 3,555 Setswana language (ISO 639-3: `tsn`) Twitter tweets annotated by three native Setswana speakers. The dataset provides complete annotation timestamps, language identification metadata, and labels from each annotator, supporting downstream modeling and annotation quality research. The dataset is divided into a training set (2,762 tweets), a validation set (346 tweets), a test set (346 tweets), and a full configuration (3,555 tweets). The training/validation/test sets only include three core sentiment categories (positive, negative, neutral) and are stratified by consensus labels in an 80/10/10 ratio. The dataset also includes metadata such as annotator labels, timestamps, and consensus types, making it suitable for training and evaluating sentiment classifiers, as well as for annotation quality research. Data preprocessing includes the replacement of sensitive information such as usernames, mentions, and URLs, as well as case normalization. The main limitations of the dataset include the specificity of Twitter data, imbalanced label distribution (dominated by negative and neutral labels), and the impact of annotation time span on consistency. The dataset is released under the Creative Commons Attribution 4.0 International (CC BY 4.0) license.
数据集概述
- 数据集名称:DSFSI Setswana Sentiment
- 许可证:Creative Commons Attribution 4.0 International (CC BY 4.0)
- 语言:茨瓦纳语(Setswana,ISO 639-3:
tsn) - 任务类别:文本分类
- 标签:情感分析、茨瓦纳语、非洲语言、低资源语言、Twitter
- 数据集大小:约 3,555 条推文(1K < n < 10K)
数据集结构
数据集包含三个分类划分和一个完整配置:
| 划分 | 样本数 | 用途 |
|---|---|---|
train |
2,762 | 微调/训练 |
validation |
346 | 模型选择和超参数调优 |
test |
346 | 最终评估 |
full |
3,555 | 包含全部推文及逐标注者标签、元数据和时间戳 |
train/validation/test划分仅包含 积极、消极、中立 三个核心情感类别,按共识标签以 80/10/10 比例分层抽样(随机种子 42)。共识标签为Mixed、Indeterminate或Disagreement的样本不包含在这些划分中,但保留在full配置中。
建议使用的列
-
训练/评估情感分类器:
- 输入:
text(已预处理的推文文本) - 目标:
consensus_label(值:Positive、Negative、Neutral)
- 输入:
-
标注质量/分歧研究:
ann1_label、ann2_label、ann3_label(逐标注者标签)ann1_timestamp、ann2_timestamp、ann3_timestamp(UTC 提交时间)consensus_type(共识类型:unanimous、majority、disagreement)
-
语言相关过滤:
lid_top1_lang、lid_top1_score、lid_top2_lang、lid_top2_score、lid_top3_lang、lid_top3_score
列说明
| 列名 | 类型 | 描述 |
|---|---|---|
example_id |
string | 标注样本的唯一标识符 |
tweet_id |
string | 原始 Twitter 状态 ID |
batch |
int | 0 表示训练/校准批次,1–7 表示生产批次 |
text |
string | 预处理后的推文文本(作为模型输入) |
token_count |
int | 推文中的 Token 数量 |
lid_top1_lang |
string | AfroLID 最佳语言预测 |
lid_top1_score |
float | lid_top1_lang 的置信度分数 |
lid_top2_lang |
string | 次佳语言预测 |
lid_top2_score |
float | lid_top2_lang 的置信度分数 |
lid_top3_lang |
string | 第三佳语言预测 |
lid_top3_score |
float | lid_top3_lang 的置信度分数 |
ann1_label |
string | 标注者 1 的标签(积极、消极、中立、混合、不确定) |
ann1_timestamp |
string | 标注者 1 提交标签的 UTC ISO-8601 时间戳 |
ann2_label |
string | 标注者 2 的标签 |
ann2_timestamp |
string | 标注者 2 提交的 UTC 时间戳 |
ann3_label |
string | 标注者 3 的标签 |
ann3_timestamp |
string | 标注者 3 提交的 UTC 时间戳 |
consensus_label |
string | 多数投票标签。若三位标注者全部不一致则为 Disagreement |
consensus_type |
string | 共识类型:unanimous(3/3)、majority(2/3)、disagreement(无多数) |
label_id |
int | (仅划分中)consensus_label 的整数 ID:Positive: 0、Negative: 1、Neutral: 2 |
文本预处理
text 字段已进行预处理:用户名、提及、URL 等潜在识别信息已被替换为占位符 Token,话题标签已规整,文本已转为小写。由于隐私原因,原始推文文本未包含在此数据集中。
标签方案
| 标签 | 描述 |
|---|---|
Positive |
推文表达积极情感 |
Negative |
推文表达消极情感 |
Neutral |
推文表达中立情感 |
Mixed |
推文同时表达积极和消极情感 |
Indeterminate |
推文难以理解、使用其他语言或无法被可靠分类 |
标注者
三位茨瓦纳语母语的本科生对语料进行了标注。身份已匿名化为 Ann.1、Ann.2 和 Ann.3(所有记录中稳定不变)。
完整数据集标签分布
| 标签 | 数量 | 占语料百分比 |
|---|---|---|
| Neutral | 1,489 | 41.9% |
| Negative | 1,445 | 40.6% |
| Positive | 520 | 14.6% |
| Disagreement | 47 | 1.3% |
| Indeterminate | 33 | 0.9% |
| Mixed | 21 | 0.6% |
- 标注者间一致性(Randolphs free-marginal κ):0.76(按惯例为“优秀”水平)。
快速开始
python from datasets import load_dataset
分类划分(仅积极、消极、中立)
ds = load_dataset("dsfsi/setswana-sentiment") print(ds["train"][0]["text"], "→", ds["train"][0]["consensus_label"])
完整数据集(包含所有元数据和逐标注者标签)
full = load_dataset("dsfsi/setswana-sentiment", "full")
预期用途
- 训练和评估茨瓦纳语及相关班图语言的情感分类器。
- 研究标注者分歧、标注质量监控以及多标注者任务中的时间效应。
- 对多语言和非洲语言预训练语言模型进行基准测试。
局限性
- 语料来自 Twitter(2021–2022 年),反映了该平台当时的语境、话题和用户群体。
- 消极和中立标签占主导地位(合计约 82%),积极标签占比不足。
- 主要的成对混淆是消极与中立之间,反映了茨瓦纳语政治和社会评论中常见的间接和讽刺表达——这是数据本身的特性,而非标注者质量问题。
- 标注是异步收集的;每条推文的标注者间时间跨度是一致性的强预测因子,并在每条样本中报告。