nadizik/tech-sentences-error-robustness
收藏资源简介:
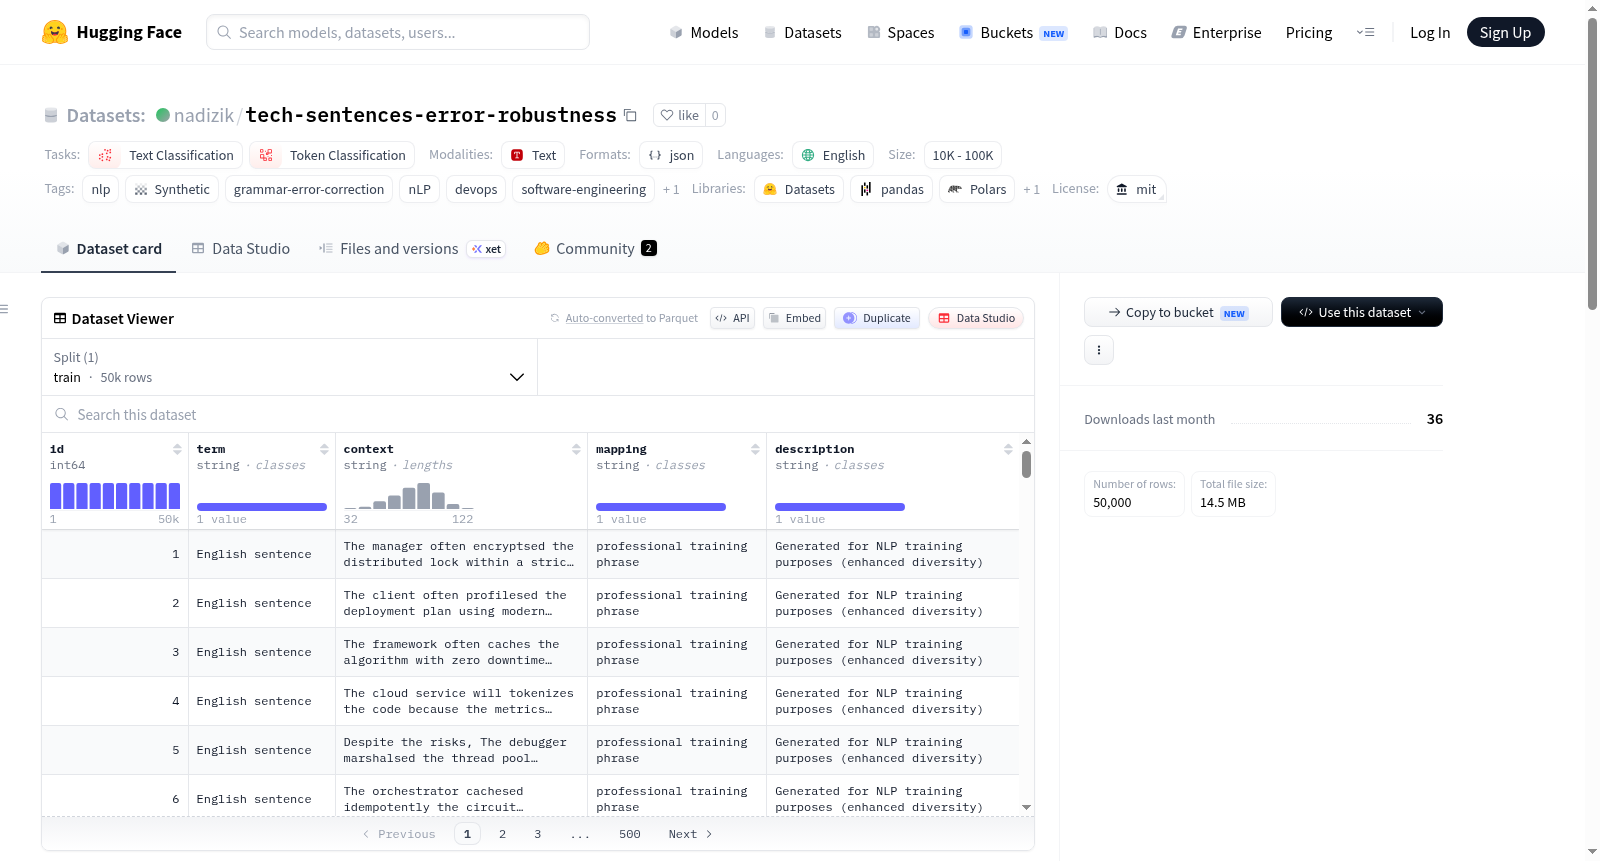
该数据集包含50,000个合成生成的英语句子,专门围绕软件工程、DevOps和IT上下文定制。一个独特特点是存在故意的语法和形态异常,例如动词形式的错误组合(如将过去时与第三人称单数结尾结合,像encryptsed、profilesed,或混合情态动词如will tokenizes、will debugs)。这使得数据集对以下方面非常有价值:1. 鲁棒性测试:评估NLP模型如何处理嘈杂或语法不正确的技术文本;2. 语法错误纠正:训练模型在IT特定上下文中检测和修复动词/语法错误;3. 领域适应:让模型接触技术术语(如DAG、ORM、线程池、分布式锁、DevOps)。数据集结构包括数据实例(如JSON格式)、数据字段(id、term、context、mapping、description),并覆盖多种IT角色和操作,确保技术领域内的高词汇多样性。
This dataset contains 50,000 synthetically generated English sentences, specifically tailored for software engineering, DevOps, and IT contexts. A distinctive feature is the inclusion of intentional grammatical and morphological errors, such as incorrect combinations of verb forms (e.g., combining past tense with third-person singular endings like encryptsed, profilesed, or mixed modal verb constructions such as will tokenizes, will debugs). This renders the dataset highly valuable for three core scenarios: 1. Robustness testing: evaluating how NLP models handle noisy or grammatically incorrect technical text; 2. Grammatical error correction: training models to detect and repair verb and grammatical errors within IT-specific contexts; 3. Domain adaptation: exposing models to specialized technical terminology (e.g., DAG, ORM, thread pool, distributed lock, DevOps). The dataset structure includes data instances formatted in JSON, with data fields covering id, term, context, mapping, and description, and encompasses a wide range of IT roles and operational activities, ensuring high lexical diversity within the technical domain.