SiDiaC
收藏资源简介:
SiDiaC 是第一个全面的僧伽罗语历史语料库,涵盖了从公元前5世纪到20世纪的广阔历史时期。该语料库包含58,000个词汇,跨越46部文学作品,并根据文本的撰写日期进行了仔细的注释。文本来自斯里兰卡国家图书馆,使用Google Document AI OCR进行数字化,随后进行后处理以纠正格式并使正字法现代化。SiDiaC 的构建受到了其他语料库实践的影响,特别是在句法注释和文本规范化策略方面,这些语料库具有低资源语言状态的共同特征。这个语料库根据体裁分为两个层次:初级和次级。初级分类是二元的,将每本书分为非小说或小说,而次级分类更为具体,将文本分组在宗教、历史、诗歌、语言和医学体裁下。尽管面临着对稀有文本的有限访问和依赖二级日期来源的挑战,但 SiDiaC 仍然是僧伽罗语自然语言处理的基础资源,显著扩展了僧伽罗语的可用资源,使词汇变化、新词跟踪、历史句法以及基于语料库的研究成为可能。
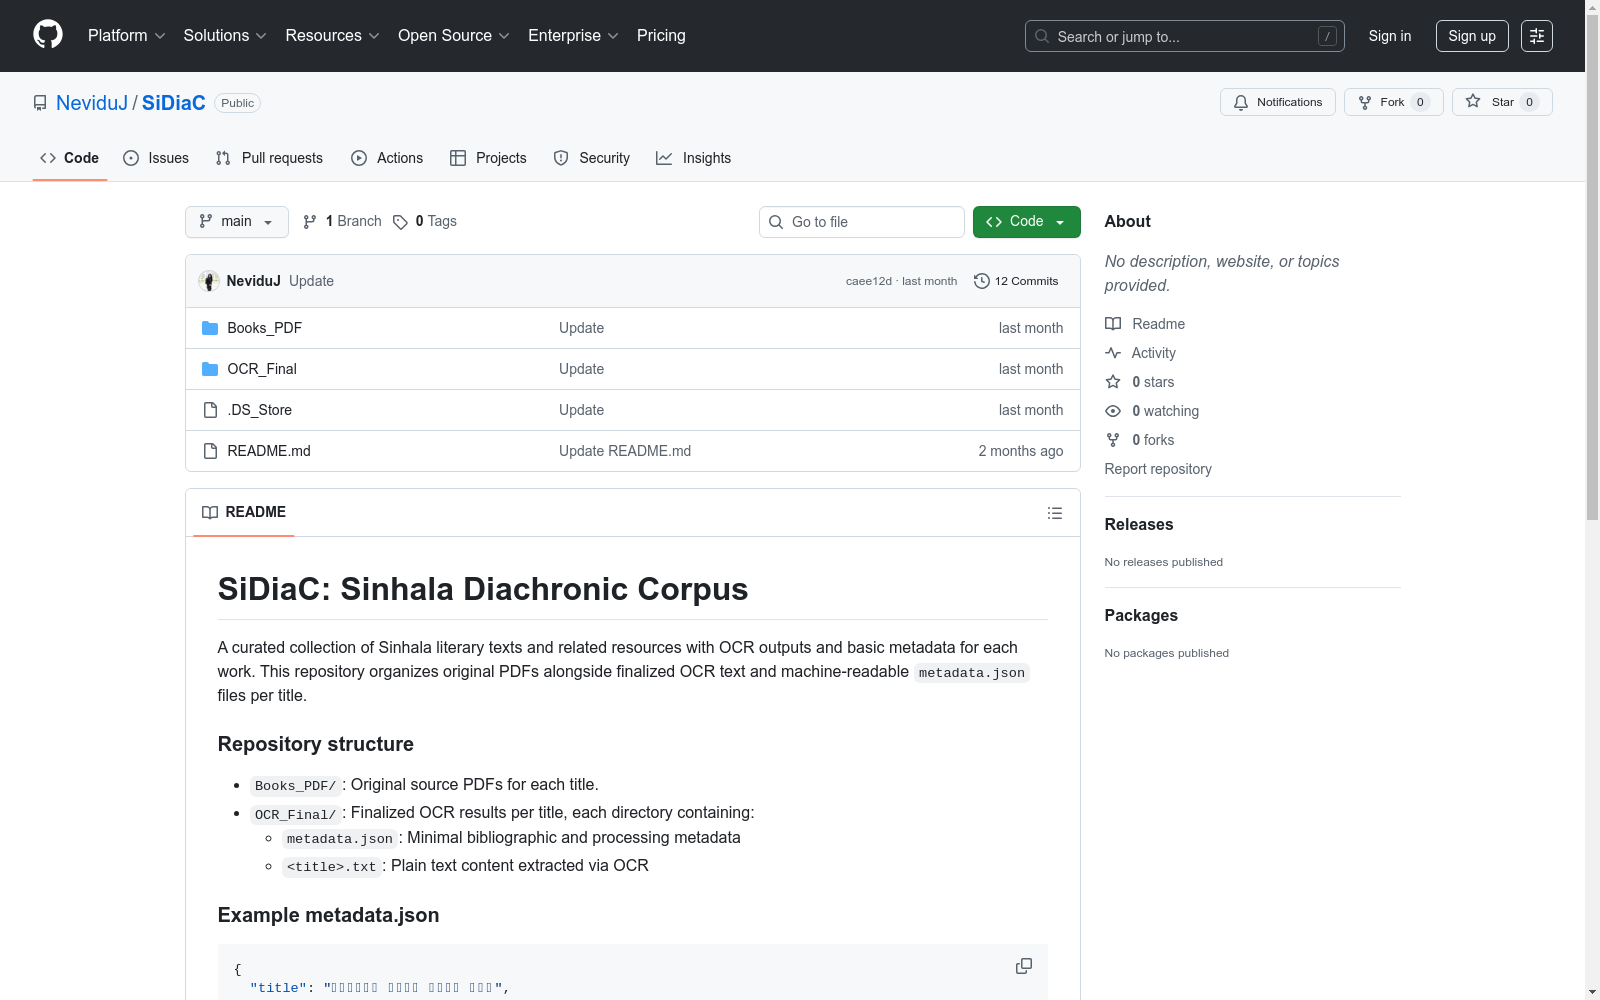
SiDiaC is the first comprehensive historical corpus of Sinhala, covering a broad historical span from the 5th century BCE to the 20th century. It contains 58,000 lexical items across 46 literary works, with meticulous annotations based on the original composition dates of each text. The source texts were retrieved from the National Library of Sri Lanka, digitized using Google Document AI OCR, and then subjected to post-processing to rectify formatting inconsistencies and modernize orthographic conventions. The construction of SiDiaC was informed by established practices from other corpora—particularly those tailored for low-resource languages—specifically in the domains of syntactic annotation and text normalization strategies. This corpus is categorized into two hierarchical tiers by genre: primary and secondary. The primary tier adopts a binary classification scheme, dividing each work into either non-fiction or fiction, while the secondary tier provides more granular categorization, grouping texts under the genres of religious, historical, poetic, linguistic, and medical works. Despite challenges including limited access to rare texts and reliance on secondary date sources, SiDiaC stands as a foundational resource for Sinhala natural language processing (NLP). It has markedly expanded the available linguistic resources for Sinhala, enabling research on lexical variation, new word tracking, historical syntax, and corpus-based studies.