odyssey-v0.5.1-16h-eval-preview-public
收藏资源简介:
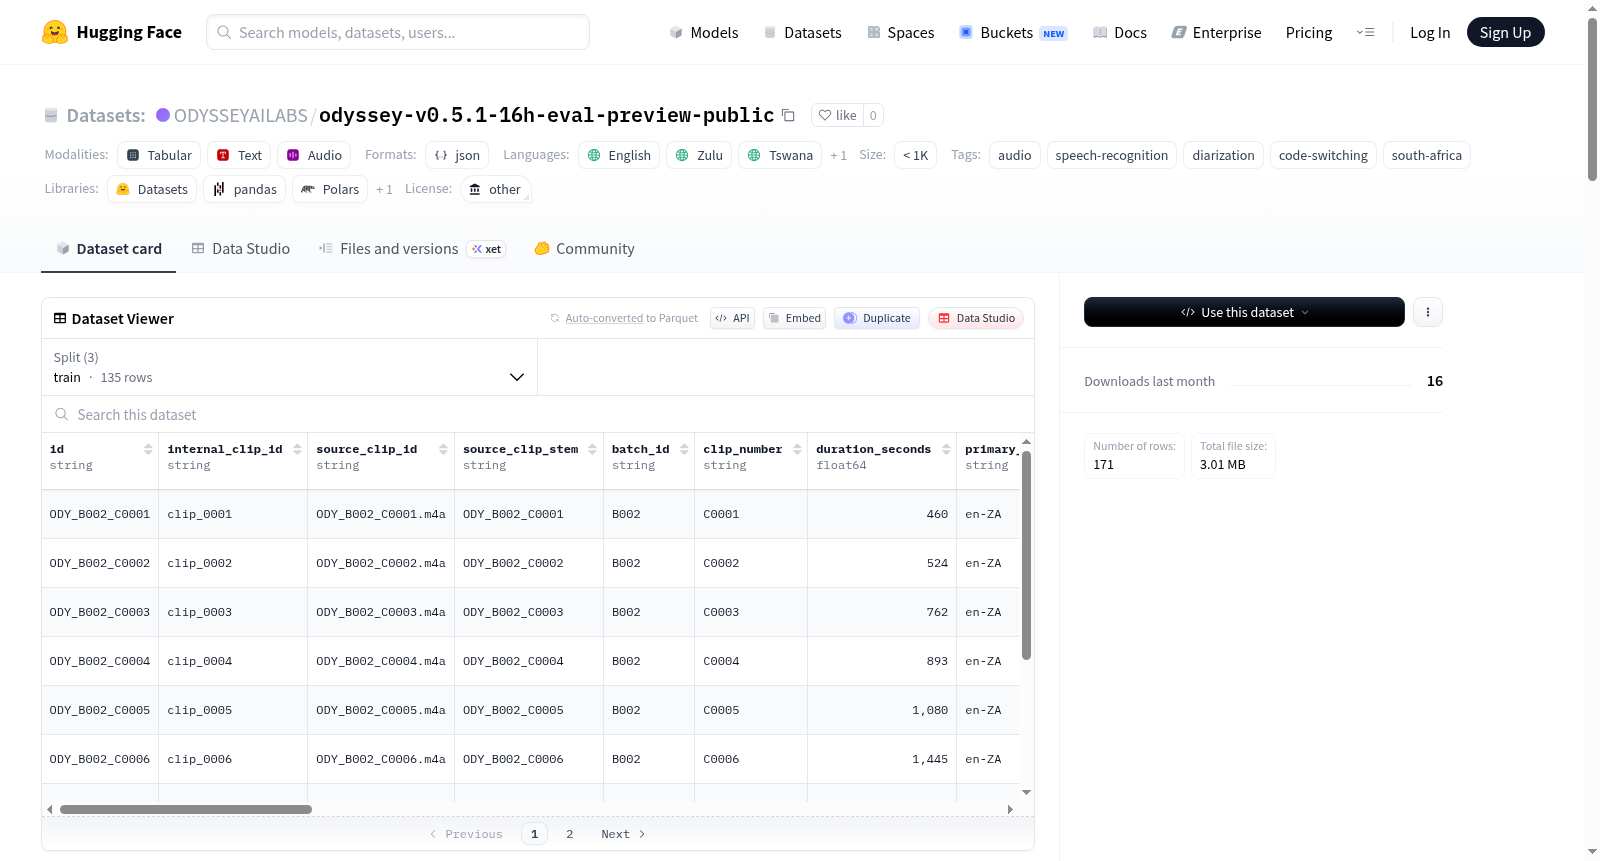
Odyssey V0.5.1 数据集是一个16小时的南非自动语音识别(ASR)评估预览版,专注于展示南非ASR的实际挑战,包括本地城市中的代码切换、多说话人轮流对话和重叠的会话语音。数据集包含171个连续对话片段,总计16.153小时的音频转录和元数据,其中94.7%的片段涉及代码切换,97.1%的片段包含3至5个说话人,94.7%的片段有明确的重叠语音部分。数据采用轻量级的Array-Tuple JSON格式存储,结构为[start, end, speaker, text],并分为训练、验证和测试三个JSONL文件。数据集主要语言为南非英语(en-ZA),同时包含其他南非语言如祖鲁语(zu-ZA)和茨瓦纳语(tn-ZA)等。该数据集旨在用于买家审查、模式验证和转录检查,不包含音频文件,音频需通过单独的受控仓库获取。
Odyssey V0.5.1 Dataset is a 16-hour preview release for South African automatic speech recognition (ASR) evaluation, focusing on demonstrating the real-world challenges of South African ASR systems, including code-switching in local urban contexts, multi-speaker turn-taking conversations, and overlapping conversational speech. The dataset contains 171 continuous dialogue segments, totaling 16.153 hours of audio transcripts and metadata. Specifically, 94.7% of the segments involve code-switching, 97.1% include 3 to 5 speakers, and 94.7% have explicit overlapping speech portions. The data is stored in a lightweight Array-Tuple JSON format with the structure [start, end, speaker, text], and is split into three JSONL files for training, validation, and testing. The primary language of the dataset is South African English (en-ZA), while it also contains other South African languages such as Zulu (zu-ZA) and Tswana (tn-ZA). This dataset is intended for use cases including buyer reviews, model validation and transcription checks, and does not include the actual audio files; audio must be obtained via a separate controlled repository.
🇿🇦 Odyssey V0.5.1 — 16H 评估预览数据集概述
数据集基本信息
- 数据集名称: Odyssey V0.5.1 — 16H Evaluation Preview (Code-Switched ASR)
- 发布机构: Odyssey AI Labs
- 许可证: other
- 语言: 英语 (en)、祖鲁语 (zu)、茨瓦纳语 (tn)、塞索托语 (st)
- 标签: audio、speech-recognition、diarization、code-switching、south-africa
数据集内容与结构
- 数据量: 16.153 小时(包含 171 个连续对话片段)。
- 核心特征:
- 语码转换: 94.7% 的片段(162/171)包含语码转换。
- 说话人复杂性: 97.1% 的片段(166/171)包含 3 至 5 名说话人。
- 显式重叠语音段: 94.7% 的片段(162/171)包含明确标注的重叠语音段。
- 数据来源: 涵盖批次 B002 至 B011(批次 B001 被有意排除在此公共预览范围之外)。
- 架构版本: V0.5.1,采用轻量级 Array-Tuple JSON 载荷 进行分段级结构化,格式为
[start, end, speaker, text]。 - 数据文件: 包含
train.jsonl、validation.jsonl和test.jsonl三个拆分文件,位于data/目录下。 - 辅助文件: 包含
sidecars/目录,用于保存片段级的质量检查(QA)标志和元数据。
语言分布快照
- 主要语言:
en-ZA(171个片段)。 - 次要语言: 包括
af-ZA、afr、nso、null、st-ZA、tn-ZA、ts-ZA、unknown、xho、zho、zu-ZA、zul。
使用说明与限制
- 性质: 此版本为 公开的转录文本与元数据预览,不包含音频访问权限。音频位于一个配套的门控仓库中。
- 预期用途: 仅用于买方审查、架构验证、转录文本检查以及数据摄取规划。
- 限制: 并非生产许可证授权。任何用于训练、微调、重新分发、发布衍生数据集或商业部署的行为,都需要与 Odyssey AI Labs 另行签订书面协议。
- 配套音频仓库建议名称:
odyssey-v0.5.1-16h-eval-audio-gated。