laion/moss-character-voices-top3-captioned
收藏资源简介:
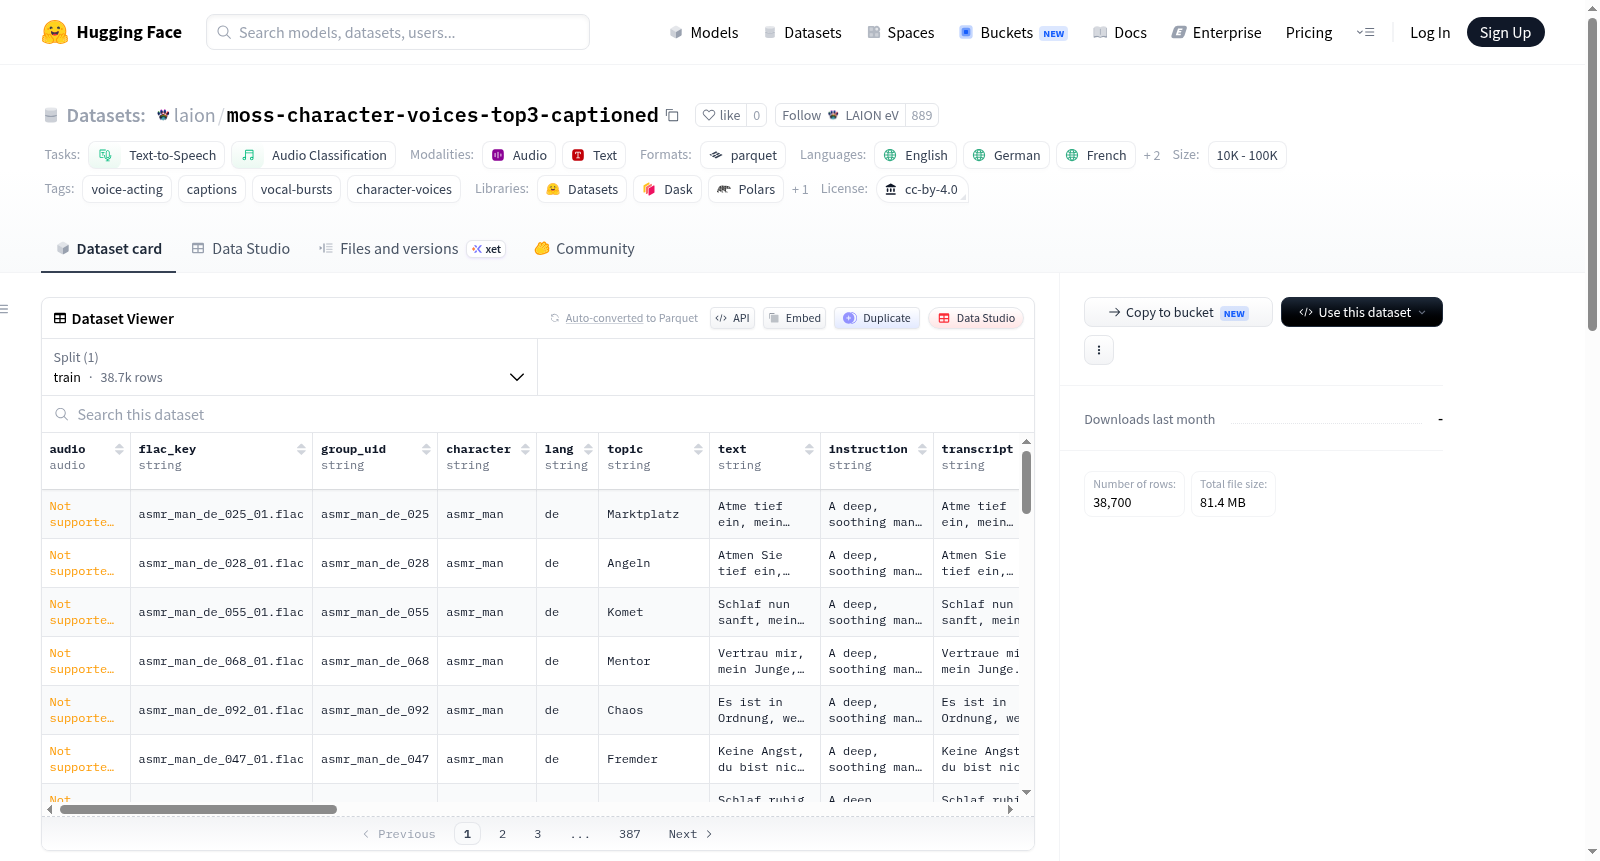
MOSS角色语音数据集——每组前三名,带标注(训练就绪版)是基于laion/moss-character-voices-bestof64数据集中所有约12,900组数据的每组前三名样本(根据奖励模型排名0/1/2),总计约38,700个样本。每个样本都使用LAION语音表演标注流水线进行了两种标注:caption_procedural(程序化语音标注,提供简洁标签和内联确认的语音爆发)和caption_llm(基于LLM的全面语音表演标注,将程序化草稿重写为自然语言并保留语音爆发位置)。数据集包含所有分数和元数据,可直接用于训练,数据以分片Parquet格式(data/train-*-of-00129.parquet)提供。字段包括音频、标注、文本、转录、角色、语言、主题、指令等元数据,以及奖励分数、排名、种子、持续时间、VoiceNet维度、EmoNet情绪、真实性、语音爆发混合、性别等评分和特征。许可证为CC-BY-4.0。
MOSS Character Speech Dataset – Top 3 per Group with Annotations (Training-Ready Version) is derived from the top 3 samples per group (ranked 0/1/2 by the reward model) across approximately 12,900 groups of data in the laion/moss-character-voices-bestof64 dataset, totaling approximately 38,700 samples in total. Each sample has undergone two types of annotations via the LAION Speech Performance Annotation Pipeline: caption_procedural (procedural speech annotation, which provides concise labels and inline-confirmed speech bursts) and caption_llm (comprehensive speech performance annotation based on LLM, which rewrites procedural drafts into natural language while retaining the positions of speech bursts). The dataset includes all scores and metadata, and is ready for direct training. The data is provided in sharded Parquet format (data/train-*-of-00129.parquet). The fields cover metadata such as audio, annotations, text, transcription, character, language, topic, instruction, as well as various scores and features including reward score, rank, seed, duration, VoiceNet dimensions, EmoNet emotion, authenticity, speech burst mixture, gender, and more. The license for this dataset is CC-BY-4.0.
数据集概述
- 数据集名称:MOSS Character Voices — Top-3 per Group, Captioned (training-ready)
- 数据集维护者:LAION eV
- 许可证:CC-BY-4.0
- 规模:12.8 GB,包含 38,400 行数据(约 10K - 100K 样本量级)
任务与模态
- 任务:文本转语音 (Text-to-Speech)、音频分类 (Audio Classification)
- 模态:表格 (Tabular)、文本 (Text)
- 格式:Parquet
- 语言:英语、德语、法语 (+2种)
- 标签:voice-acting, captions, vocal-bursts, character-voices
数据集构成
该数据集是 laion/moss-character-voices-bestof64 的一个子集,从中选取了每个组的 Top-3 (根据奖励模型排名 rank 0/1/2),总计约 12,900 个组,共约 38,700 个样本。数据被切分为 data/train-*-of-00129.parquet 文件。
核心字段说明
| 字段 | 描述 |
|---|---|
audio |
FLAC 格式的音频片段 |
caption_procedural |
程序化语音描述:包含强度、维度标签,并内联插入已确认的嗓音爆发点(vocal burst);同时包含基于 Empathic-Insight 的性别门控。 |
caption_llm |
全面语音表演注释:基于程序化描述,由 Gemma-4-E4B 改写为自然语言,嗓音爆发点位置与程序化描述一致。每条注释包含 GENERAL: 语音描述和 SCRIPT: 逐句内容(含 (delivery cue) 和 (Burst Name))。 |
text / transcript |
目标文本 / ASR 转写文本 (Parakeet) |
character, lang, topic, instruction |
生成元数据(角色、语言、主题、指令) |
reward, rank, seed, duration_s |
奖励模型分数、组内排名 (0/1/2)、随机种子、音频时长 |
voicenet_dims, emonet |
JSON:57 维 VoiceNet 特征 (0–6) 和 40 维 EmoNet 情感特征 |
genuineness, burst_blend, ei_gender, gender_gated |
真实性评分 (0–6)、嗓音爆发混合度、Empathic-Insight 性别评分 (−2 男性化至 +2 女性化)、性别是否被门控过滤 |
vocal_bursts |
JSON 列表,包含已确认的嗓音爆发点 {label, start, end, dur, prob} |
src_* |
源数据集 (moss-character-voices-bestof64) 的奖励模型子分数及元数据 |