metamathqa-r1-mini
收藏资源简介:
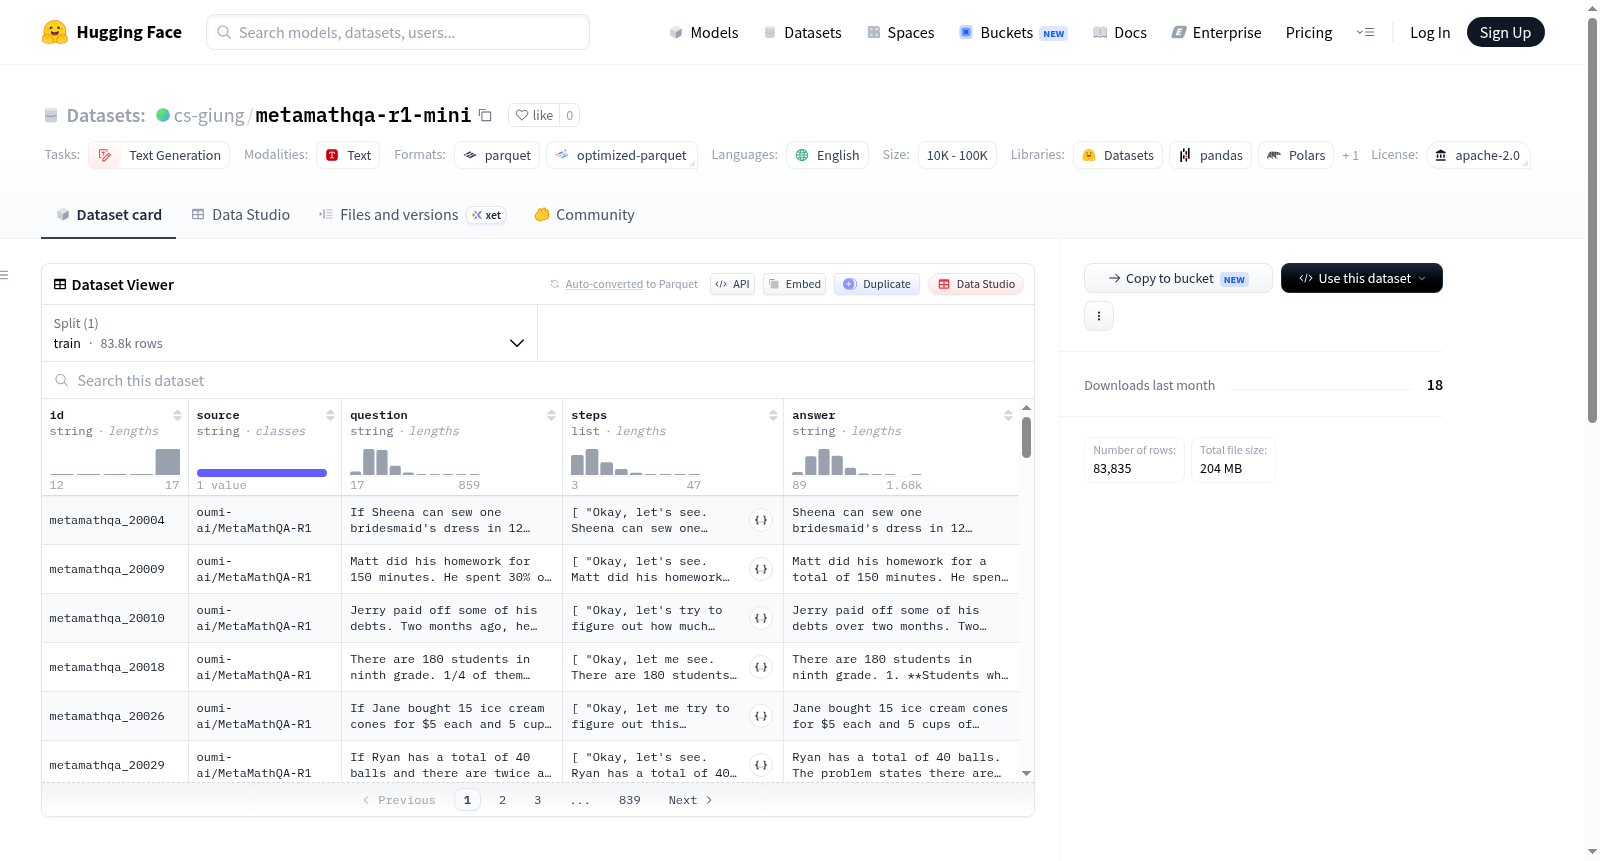
MetaMathQA R1 Mini 是一个纯文本、长度受限的推理数据集,源自 oumi-ai/MetaMathQA-R1 数据集。该数据集包含 83,835 个完整的双轮对话响应,每个样本由以下字段组成:id(源对话ID)、source(数据来源,固定为 oumi-ai/MetaMathQA-R1)、question(精简后的源提示)、steps(有序推理步骤列表,来自思考过程,并去除了重复的最终答案单元)、answer(完整的润色解释,而非简短的参考答案)。每个样本的 steps 数量在 3 到 47 之间,每个 answer 至少包含 15 个单词,并以解释性结论结尾。数据集经过了严格的过滤,移除了不完整响应、依赖图像的行、仅包含答案的样本、重复相邻问题句子的样本以及超过 Llama 3 1024 token 限制的序列。该数据集适用于文本生成任务,尤其是需要多步推理的场景,如数学推理。
MetaMathQA R1 Mini is a pure-text, length-constrained reasoning dataset derived from the oumi-ai/MetaMathQA-R1 dataset. It contains 83,835 complete two-turn dialogue responses, each sample consisting of the following fields: id (source dialogue ID), source (data source, fixed as oumi-ai/MetaMathQA-R1), question (trimmed source prompt), steps (ordered list of reasoning steps from the thinking process, with duplicate final answer units removed), and answer (a complete polished explanation, not a short reference answer). The number of steps per sample ranges from 3 to 47, and each answer contains at least 15 words, ending with an explanatory conclusion. The dataset underwent strict filtering, removing incomplete responses, image-dependent rows, answer-only samples, samples with repeated adjacent question sentences, and sequences exceeding the Llama 3 1024 token limit. This dataset is suitable for text generation tasks, especially those requiring multi-step reasoning, such as mathematical reasoning.
MetaMathQA R1 Mini (Explanatory) 数据集详情
基本信息
- 数据集名称: MetaMathQA R1 Mini (Explanatory)
- 许可证: Apache 2.0
- 任务类型: 文本生成 (Text Generation)
- 语言: 英语
- 数据规模: 10K-100K 条样本
- 数据大小: 数据集约 238.3 MB,下载大小约 204 MB
数据概述
该数据集是从 oumi-ai/MetaMathQA-R1 数据集构建的纯文本、长度受限的推理数据集,包含 83,835 条完整的两轮对话响应,未进行行数上限限制、采样或打乱操作。
数据字段说明
| 字段名 | 数据类型 | 描述 |
|---|---|---|
id |
string | 源对话ID |
source |
string | 数据来源,固定为 oumi-ai/MetaMathQA-R1 |
question |
string | 修剪后的源提示问题 |
steps |
list[string] | <think> 内部的有序推理单元,已移除重复的终止 Final Answer 单元 |
answer |
string | </think> 之后的完整精炼解释,非简单的参考答案 |
数据质量要求
- 每条数据包含 3 到 47 个推理步骤
- 每个回答至少包含 15 个单词,并包含解释性结论
- 已排除以下类型的数据:不完整响应、依赖图像的行、裸答案、重复相邻问题的句子、超过 Llama 3 的 1,024 token 限制的序列
数据划分
数据集仅包含 train 划分,共 83,835 个样本,字节数为 238,257,703。
来源追溯
- 源修订版本:
84f7a518a6f1ea426111be6954dedf37975b93df - 输出 JSONL SHA-256:
fd52fd51bece0fd1c3ded4ed75686fb1c9114ca4d8ff5e398959dd340f5d9271 - 完整的映射、过滤规则、拒绝统计、分词器指纹及字节级完整性数据见
construction_manifest.json文件。