unlearning-cleanslate/eval-20-debug-llama-3_1-8b-simnpo-gentle-igm-10b-target-100-localtrain-checkpoint-1
收藏资源简介:
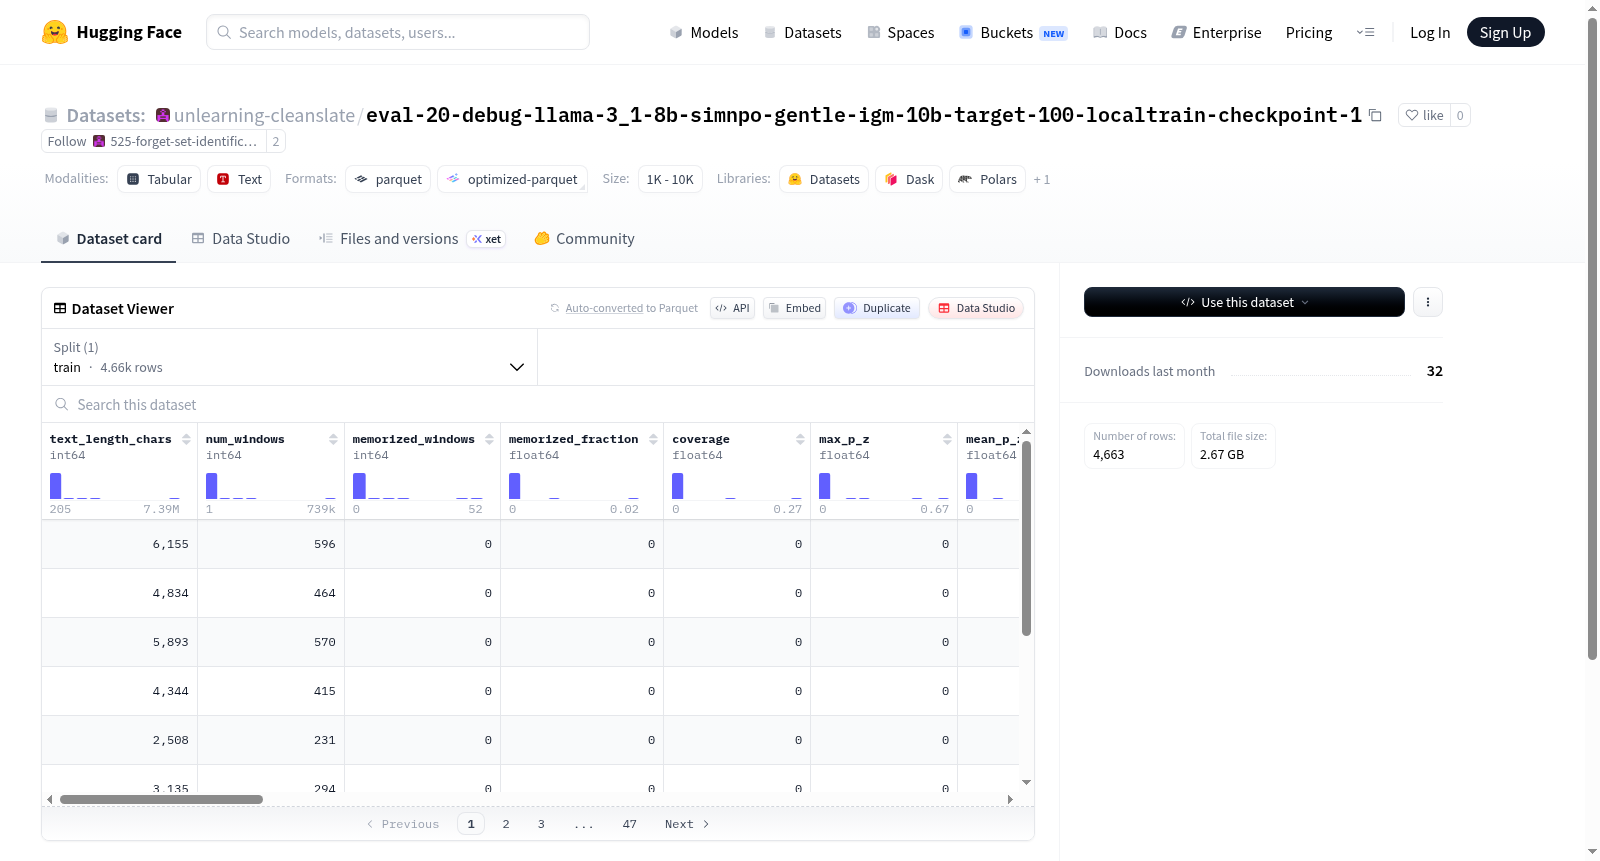
该数据集是一个用于评估文本记忆度的数据集,包含4663个训练示例,总大小约为2.67 GB。数据特征包括文本长度、窗口数量、记忆窗口数、记忆比例、覆盖率、概率统计指标(如最大、平均、中位数、最小和标准差概率)以及最佳窗口相关信息(如索引、概率、种子、目标文本、起始和结束字符)。此外,还包含评估模型、窗口大小、步长、评估阈值等元数据,以及内容标识符、标题、创作者和年份信息。每个样本还包含窗口列表,详细记录每个窗口的结束字符、索引、是否记忆、对数概率、目标令牌数量、概率、种子、起始字符、目标文本、目标对数概率和目标排名。数据集适用于自然语言处理任务,特别是文本记忆分析和模型评估。
This dataset is designed for evaluating text memorization, comprising 4663 training examples with a total size of approximately 2.67 GB. The features include text length, number of windows, memorized windows, memorized fraction, coverage, probability statistics (such as maximum, mean, median, minimum, and standard deviation probabilities), and best window-related information (e.g., index, probability, seed, target text, start and end characters). It also includes metadata like evaluation model, window size, stride, evaluation threshold, as well as content identifier, title, creators, and year. Each sample contains a list of windows detailing end character, index, memorization status, log probability, number of target tokens, probability, seed, start character, target text, target log probabilities, and target ranks. The dataset is suitable for natural language processing tasks, particularly text memorization analysis and model evaluation.