fineweb-edu-2015-qwen2
收藏资源简介:
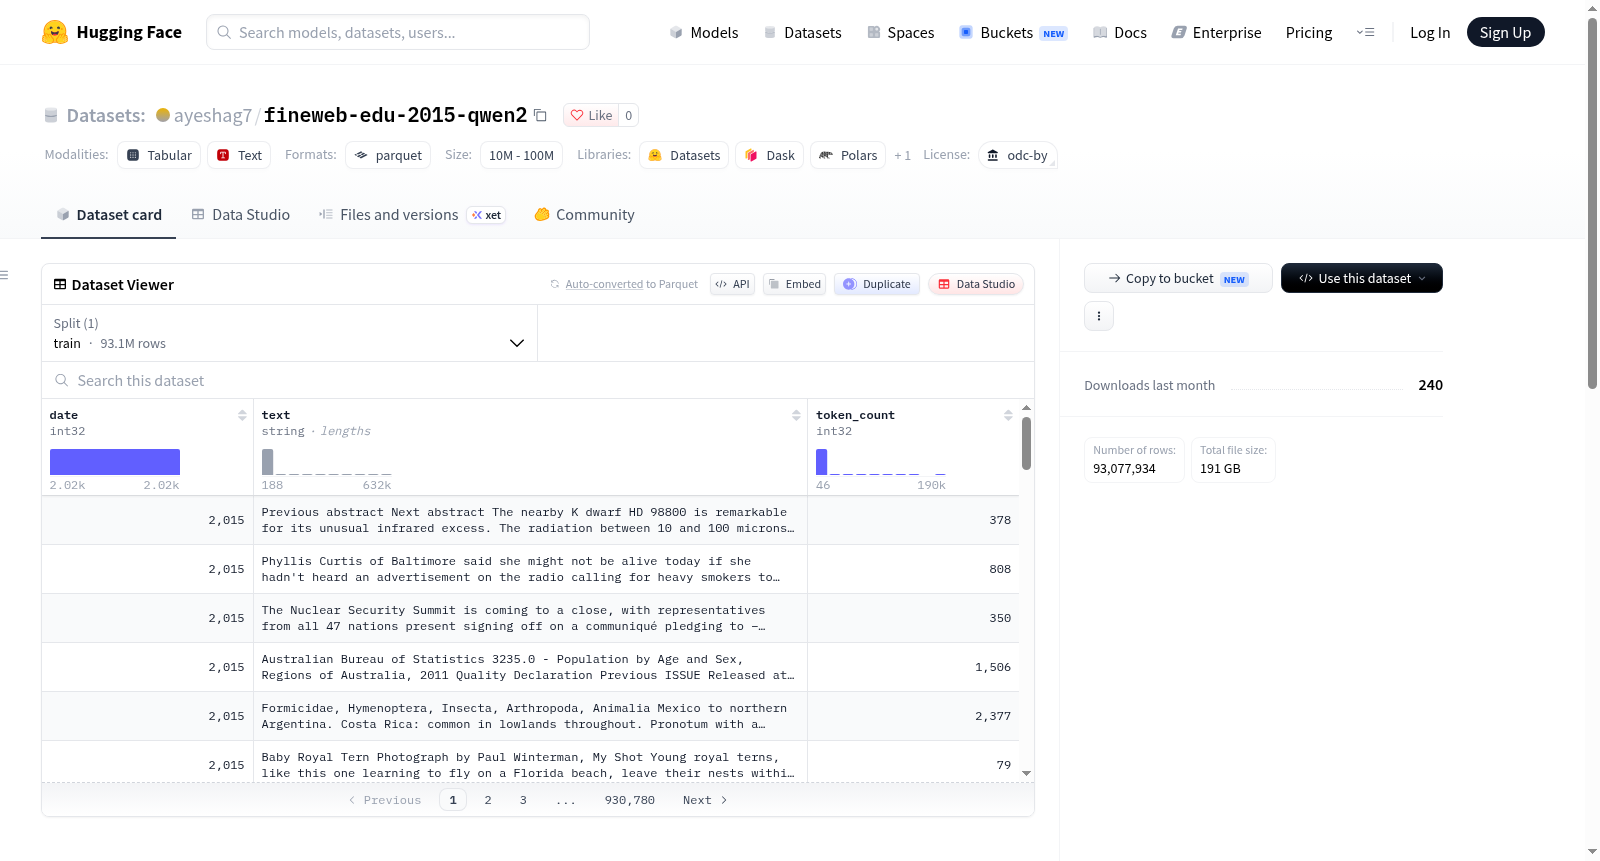
FineWeb-Edu 2015 是 FineWeb-Edu 数据集的一个子集,专为 FinMoE 项目的继续预训练而准备。该数据集包含 93,077,934 个文档,共计约 1000 亿 Qwen2-7B tokens。每个文档包含三个字段:date(int32 类型,固定为 2015 年)、text(字符串类型,未修改的原始文档文本)、token_count(int32 类型,使用 Qwen2-7B 分词器在原始文本上计数得到的 token 数,未添加特殊 token 且不截断)。数据来源于 HuggingFaceFW/fineweb-edu 数据集在 2015 年的全部 10 个 CommonCrawl 转储(共 134 个分片)。为了达到 100B token 的目标,采用了可复现的随机 shuffle:为每个文档分配一个基于随机种子的均匀采样 u(种子为 20150101 + 分片索引),按 u 排序后依次选取文档,累积 Qwen2-7B token 数,在首个超过目标值的文档之前停止,只保留完整文档。最终的截止条件为 u < 0.919854179101843。处理详情(包括软件包版本)记录在 processing_metadata.json 文件中。
FineWeb-Edu 2015 is a subset of the FineWeb-Edu dataset, prepared for the continued pretraining of the FinMoE project. It contains 93,077,934 documents, totaling approximately 100 billion Qwen2-7B tokens. Each document consists of three fields: date (int32 type, fixed as 2015), text (string type, unmodified original document text), and token_count (int32 type, counted using the Qwen2-7B tokenizer on the original text, without adding special tokens or truncation). The data comes from all 10 CommonCrawl dumps (134 shards) of 2015 from the HuggingFaceFW/fineweb-edu dataset. To achieve the target of 100B tokens, a reproducible random shuffle was used: assign a uniform sample u based on a random seed (seed = 20150101 + shard index) to each document, sort by u, select documents sequentially, accumulate Qwen2-7B token count, stop before the first document that exceeds the target, keeping only complete documents. The final cutoff condition is u < 0.919854179101843. Processing details (including software package versions) are recorded in the processing_metadata.json file.
数据集概述
基本信息
- 数据集名称:FineWeb-Edu 2015, Qwen2-7B token counts
- 许可证:odc-by
- 文档数量:93,077,934
- Token 数量:99,999,999,500 Qwen2-7B tokens
- 用途:作为 FinMoE 项目的一部分,用于持续预训练(continued pretraining)
数据列结构
| 列名 | 类型 | 含义 |
|---|---|---|
date |
int32 | FineWeb 年份,即 2015 |
text |
string | 文档文本,未做修改 |
token_count |
int32 | text 中的 Qwen2-7B token 数量 |
数据来源
- 来源数据集:HuggingFaceFW/fineweb-edu,revision 为
87f09149ef4734204d70ed1d046ddc9ca3f2b8f9 - 覆盖 2015 年全部 10 个 CommonCrawl dumps(134 个分片)
Token 计数方式
- 使用模型:Qwen/Qwen2-7B,revision 为
453ed1575b739b5b03ce3758b23befdb0967f40e - 计数参数:
add_special_tokens=False、truncation=False - 在原始文本上进行计数
- FineWeb-Edu 自带的
token_count列基于 GPT-2,已被丢弃,未复制使用
选择方法
- 2015 年的数据量超过 100B token 的目标
- 每个文档被分配一个
u值,取自random.Random(20150101 + shard_index)的均匀抽样,按行顺序取得 - 按
u排序可实现可复现的文档级随机打乱 - 按该顺序累积实际 Qwen2 token 计数,在第一个会使总数超过目标的文档之前停止,仅保留完整文档
- 最终截止值为
u < 0.919854179101842
补充说明
- 完整细节(包括包版本信息)记录于
processing_metadata.json