open-llm-leaderboard-eda
收藏资源简介:
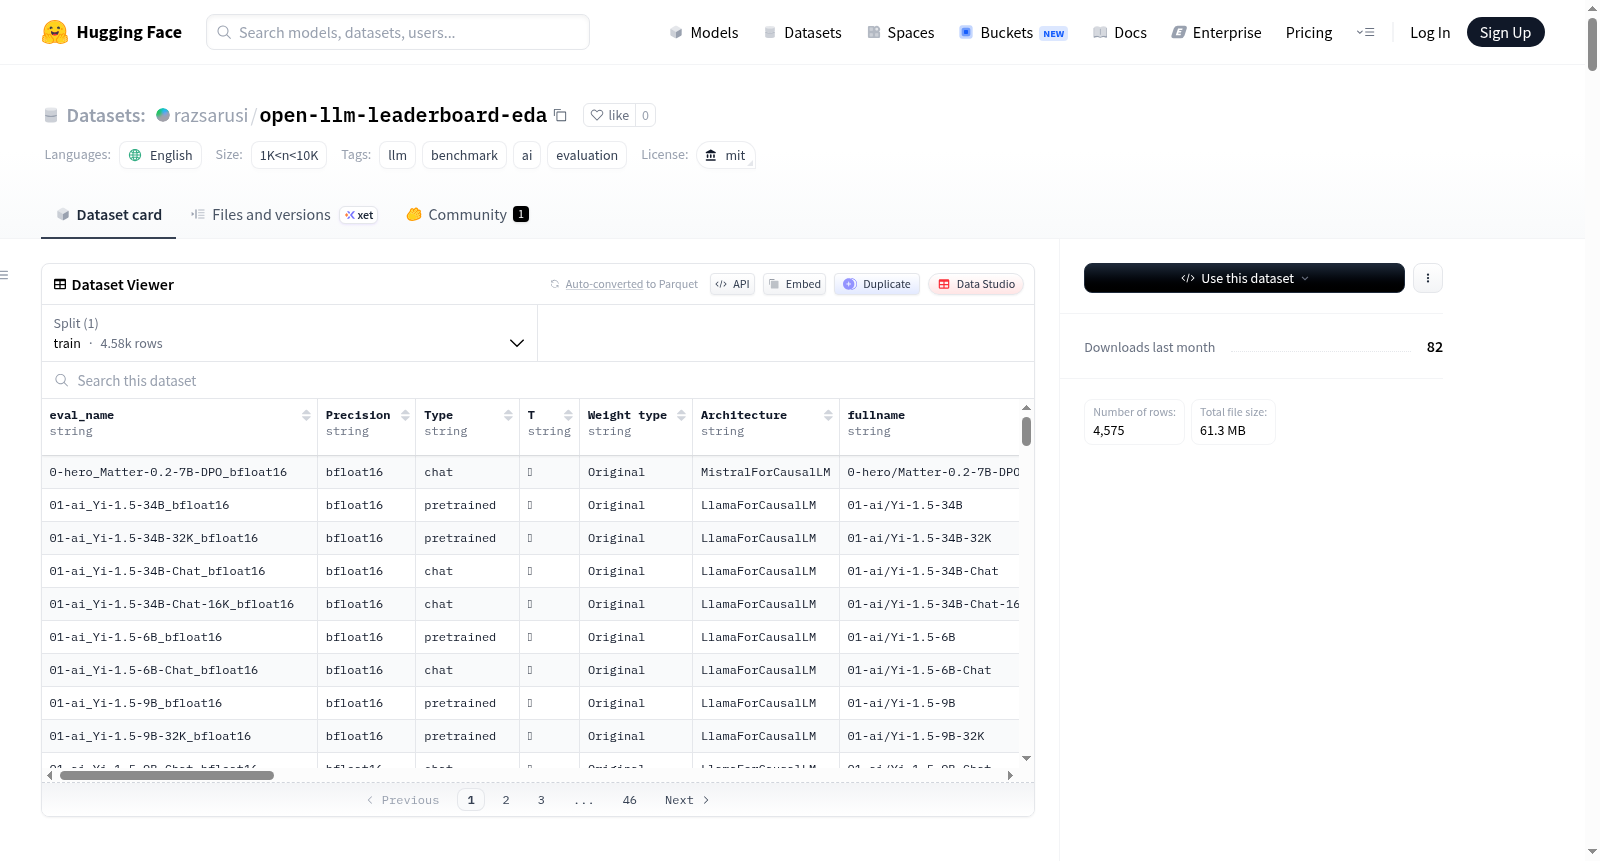
该数据集来自HuggingFace的Open LLM Leaderboard,包含4,575条大型语言模型(LLM)评估记录,涵盖模型大小、训练类型、架构以及在6个标准化基准测试中的得分。数据集共35列,关键字段包括平均得分(`Average`)、参数数量(`#Params (B)`)、模型类型(`Type`)、架构(`Architecture`)、碳足迹(`CO2 cost (kg)`)和HuggingFace Hub点赞数(`Hub likes`)。基准测试包括IFEval(指令跟随能力)、BBH(复杂推理)、MMLU-PRO(专业知识)、MATH Lvl 5(高等数学)、MUSR(多步推理)和GPQA(研究生级科学问题)。数据集经过清洗,去除了重复项和无效值,适用于分析LLM性能影响因素、基准测试难度比较以及模型效率研究。
This dataset is sourced from the HuggingFace Open LLM Leaderboard, containing 4,575 large language model (LLM) evaluation records covering model size, training type, architecture, and scores across six standardized benchmark tests. The dataset consists of 35 columns, with key fields including `Average`, `#Params (B)`, `Type`, `Architecture`, `CO2 cost (kg)`, and `Hub likes`. The covered benchmark tests are IFEval (instruction-following capability), BBH (complex reasoning), MMLU-PRO (professional knowledge), MATH Lvl 5 (advanced mathematics), MUSR (multi-step reasoning), and GPQA (graduate-level scientific questions). The dataset has been cleaned to remove duplicates and invalid values, making it suitable for analyzing factors affecting LLM performance, comparing benchmark difficulty, and researching model efficiency.