wiki1m-for-simcse
收藏资源简介:
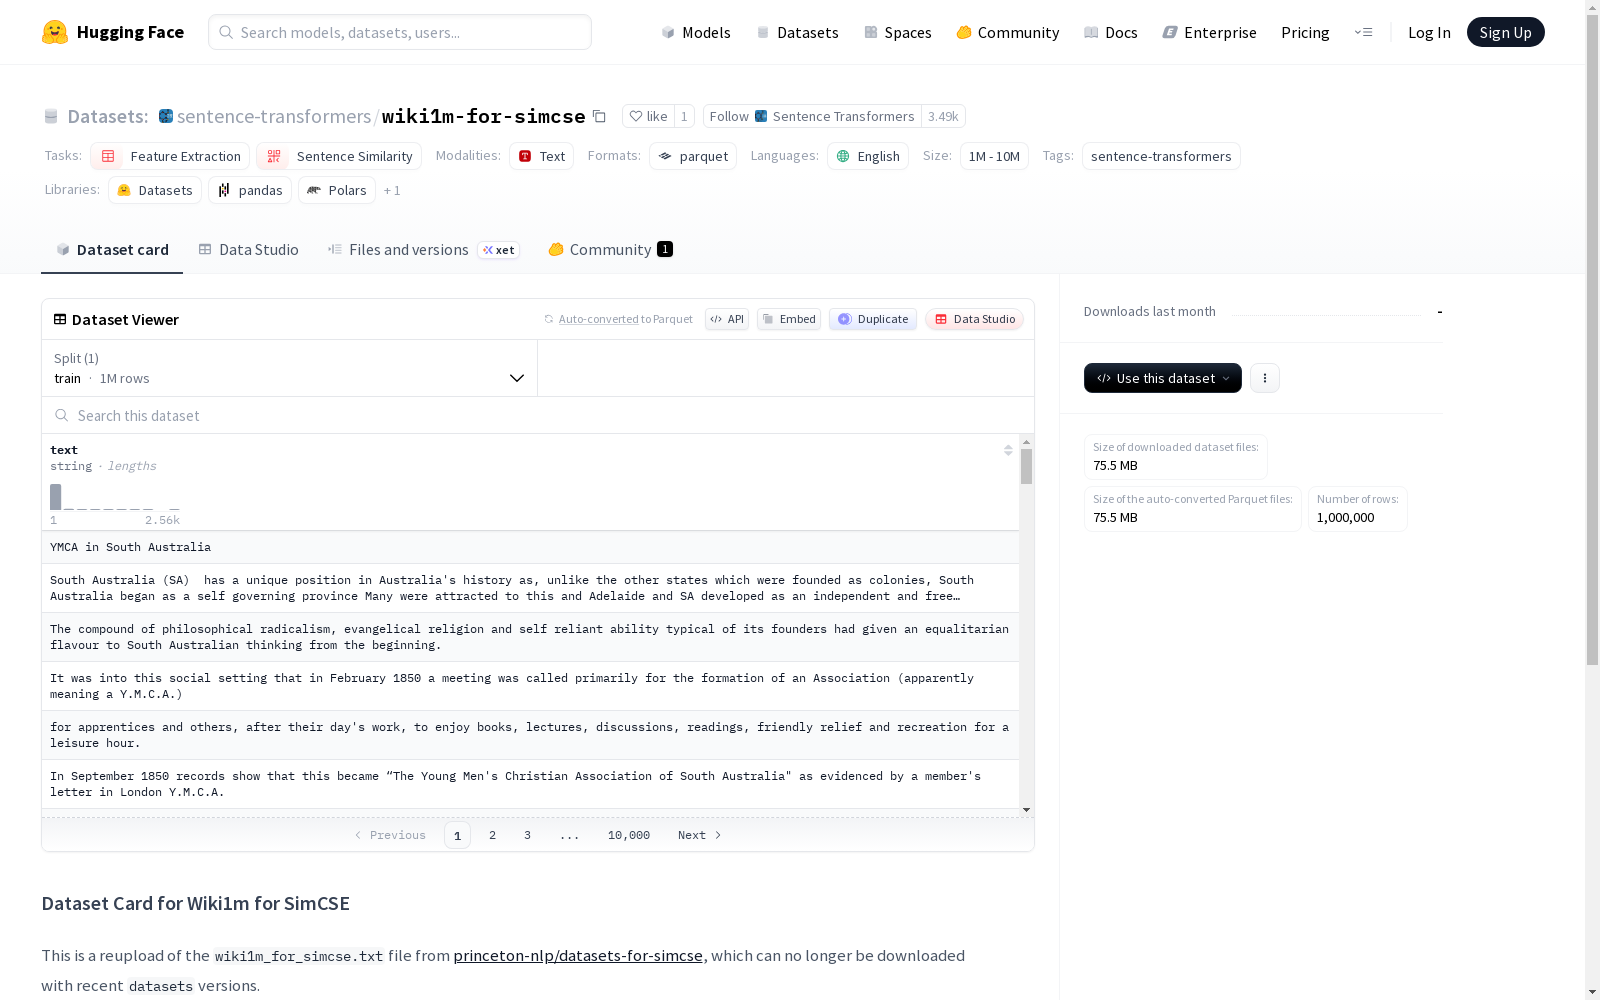
该数据集是专为SimCSE模型设计的Wikipedia文本集合,包含1,000,000条英文文本样本,总大小约为123MB。数据来源于princeton-nlp/datasets-for-simcse的重新上传版本,以解决原数据集在新版datasets库中的兼容性问题。数据集仅包含一个文本字段('text'),存储格式为字符串,未进行去重处理。适用于句子相似度计算和特征提取等自然语言处理任务。示例数据格式为{'text': 'YMCA in South Australia'}。
This dataset is a Wikipedia text collection specifically designed for the SimCSE model, containing 1,000,000 English text samples with a total size of approximately 123 MB. It is a reuploaded version sourced from princeton-nlp/datasets-for-simcse, intended to resolve the compatibility issues of the original dataset with the latest version of the datasets library. The dataset only includes a single text field ('text'), stored in string format, and no deduplication has been performed. It is applicable to natural language processing tasks such as sentence similarity calculation and feature extraction. The example data format is {'text': 'YMCA in South Australia'}.
Wiki1m for SimCSE 数据集概述
数据集基本信息
- 数据集名称:Wiki1m for SimCSE
- 数据集来源:此数据集是
princeton-nlp/datasets-for-simcse中wiki1m_for_simcse.txt文件的重上传版本。 - 语言:英语
- 多语言性:单语
- 数据规模:100万条 < 数据量 < 1000万条
- 任务类别:特征提取、句子相似度
- 标签:sentence-transformers
数据集内容与结构
- 特征列:仅包含一个名为
text的列,数据类型为字符串。 - 数据示例:
{text: YMCA in South Australia} - 数据拆分:仅包含一个训练集。
- 训练集样本数:1,000,000
- 训练集大小:123,038,621 字节
- 数据集总大小:123,038,621 字节
- 下载大小:75,484,133 字节
数据处理说明
- 收集策略:使用
datasets==2.21.0版本下载princeton-nlp/datasets-for-simcse数据集后重新上传,以使其格式与当前datasets库兼容。 - 去重处理:未进行去重。