marin-community/openthoughts4-science-26041-prompts-qwen3-30b-a3B-thinking-2507-n8-flattened-logprobs-k16
收藏资源简介:
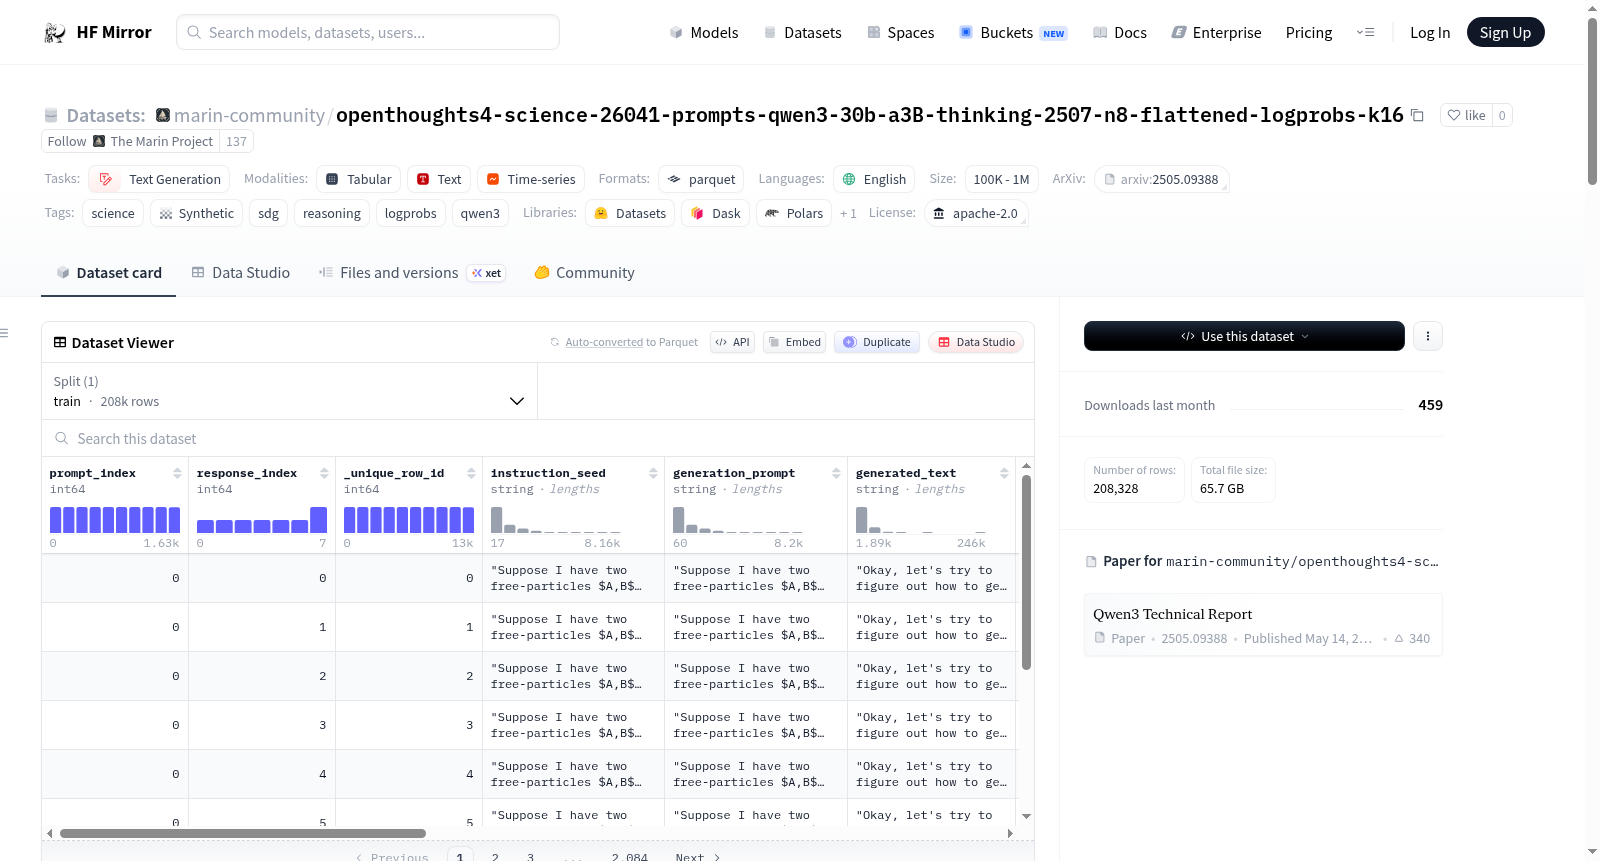
该数据集是由Qwen/Qwen3-30B-A3B-Thinking-2507模型在Marin OpenThoughts-4科学SDG提示集上生成的合成数据。每个提示被采样8次,并且对于每个生成的令牌,数据集存储了所选令牌的对数概率以及词汇表中前16个对数概率。数据集包含208,328行,每行对应一个提示和样本索引对。数据集的模式包括标识符列和生成列,其中生成列包括生成的文本、令牌ID、对数概率等。数据集以parquet格式分片存储,约3,600个文件。
This dataset is synthetic data generated by the Qwen/Qwen3-30B-A3B-Thinking-2507 model on the Marin OpenThoughts-4 scientific SDG prompt set. Each prompt is sampled 8 times, and for each generated token, the dataset stores the log probability of the selected token along with the top 16 log probabilities from the vocabulary. The dataset contains 208,328 rows, where each row corresponds to a pair of prompt and sample index. The dataset schema includes identifier columns and generation columns, with the generation columns covering generated text, token IDs, log probabilities, and other related contents. The dataset is stored in sharded parquet format, with approximately 3,600 files in total.