multilingual-code-comments
收藏资源简介:
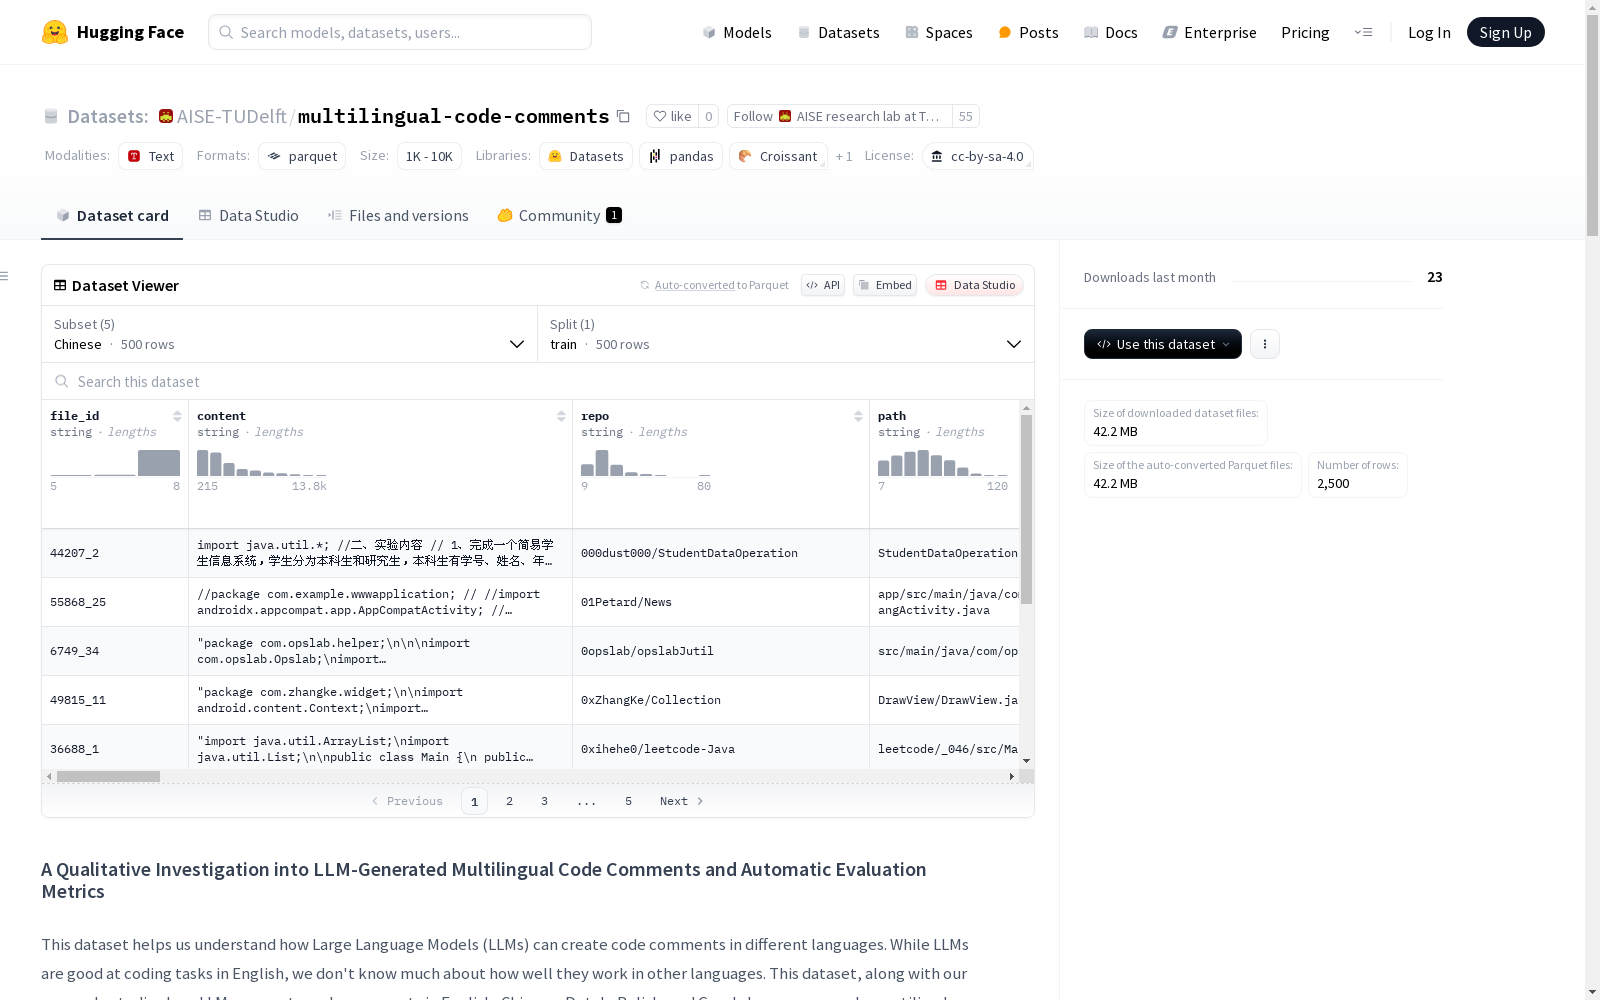
该数据集包含由大型语言模型(LLM)生成的不同语言的代码注释,如CodeQwen、StarCoder、Granite、CodeLlama和CodeGemma。数据集分为英语、中文、荷兰语、波兰语和希腊语五个子集,每个子集包含500个代码注释。注释是通过查询GitHub API获取常见词汇并从存储库中收集数据生成的。数据集还包括专家对生成注释的评价、错误代码以及用于比较原始和生成注释的指标。README提供了数据集特征的描述、生成注释的过程以及如何加载数据集子集的说明。
This dataset contains code comments in various languages generated by large language models (LLMs), including CodeQwen, StarCoder, Granite, CodeLlama, and CodeGemma. It is divided into five subsets corresponding to English, Chinese, Dutch, Polish, and Greek, with each subset containing 500 code comments. The comments were generated by querying the GitHub API to retrieve common vocabulary and collecting data from software repositories. Additionally, the dataset includes expert evaluations of the generated comments, erroneous code samples, and metrics for comparing original and generated comments. The accompanying README file provides descriptions of the dataset's characteristics, the process of generating the comments, and instructions on how to load each subset of the dataset.