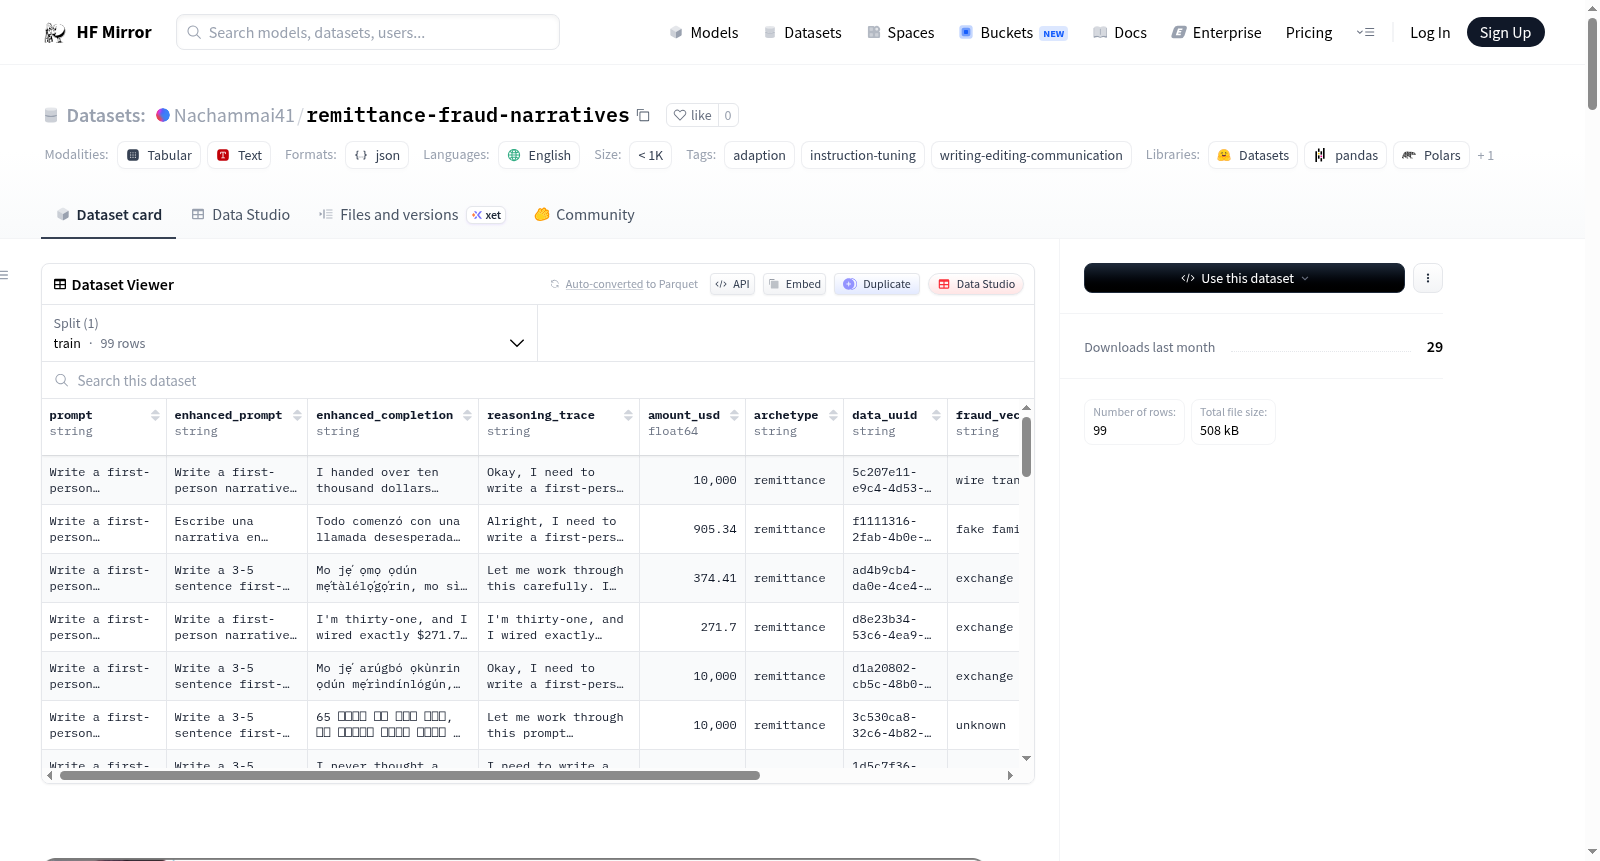
Nachammai41/remittance-fraud-narratives
收藏资源简介:
--- annotations_creators: [] language: - en language_creators: [] license: [] multilinguality: - monolingual pretty_name: 'remittance_fraud_narratives' size_categories: - n<1K source_datasets: - 'original' tags: - adaption - instruction-tuning - writing-editing-communication task_categories: [] task_ids: [] ---  This dataset is a remastered version prepared using [Adaption's](https://adaptionlabs.ai/app/auth) Adaptive Data platform. # remittance_fraud_narratives This dataset contains prompts designed to generate first-person narratives about financial fraud targeting immigrant communities via cross-border remittance services. Each entry specifies details such as the fraud vector, financial instrument, transaction amount, sender demographics, and language context. The samples currently show null completions, indicating this is a prompt collection for generating synthetic victim or participant stories in multiple languages. ### Dataset size There are 99 data points in this dataset. This is an instruction tuning dataset. ### Quality of Remastered Dataset The final quality is A, with a relative quality improvement of 86.0%. ### Domain - Writing-editing-communication (100%) ### Language - English (100%) ### Tone - Anecdotal (100%) ### Evaluation Results - **Quality Gains:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/278a2951-fc5b-49f3-b78d-fcc2e75b7753.png" alt="QualityGains" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> - **Grade Improvement:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/3995e54b-dc04-4e62-a109-127e7ca8ec39.png" alt="Grade" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> - **Percentile Chart:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/a968a6d6-d46d-456b-a738-65b62c0f215a.png" alt="Percentile Chart" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> # Underserved Financial Fraud Dataset ### Synthetic fraud detection data for underrepresented_communities **Created with Adaptive Data by Adaption** | CC BY 4.0 | 5 languages --- ## What This Is A synthetic financial fraud dataset covering **four underserved community archetypes** — populations that rely on remittance transfers, gig economy payouts, prepaid cards, and ITIN-based transactions. These communities are disproportionately targeted by fraud, yet no open-source fraud dataset has ever modeled their financial behavior. This dataset fills that gap. --- ## The Four Archetypes | Archetype | Who | Fraud Vectors | Languages | |---|---|---|---| | **Remittance Sender** | Immigrants sending money cross-border via Western Union, Remitly, MoneyGram | Emergency call scams, fake exchange rate bonuses, interception | es, ht, yo, hi, en | | **Gig Worker** | Uber, DoorDash, Instacart workers paid via CashApp, Venmo | Account takeover, SIM swap, fake platform support calls | en, hi, vi, es, yo | | **Unbanked Cash-In User** | Populations using prepaid cards and retail kiosks | Predatory micro-loans, load-fee scams, fake utility kiosks | en, es, vi, yo, hi | | **ITIN Entrepreneur** | Immigrant small business owners with no SSN | Synthetic identity fraud, fake tax returns, mule accounts | en, es, hi, ta, vi | ## Languages `en` English | `es` Spanish | `hi` Hinglish | `ht` Haitian Creole | `yo` Yoruba | `vi` Vietnamese | `ta` Tamil | `ta-en` Tamil-English --- ## What Makes It Different **No existing fraud dataset covers this population.** PaySim simulates generic mobile money. Sparkov models middle-class credit cards. IEEE-CIS captures e-commerce. None remittance kiosks, gig payouts, or ITIN-linked accounts. **Generated with diffusion, not rules.** Tabular data generated using Tab-DDPM (denoising diffusion for tabular data) — learns joint correlations across behavioral features, not just independent column sampling. Trained on A100 GPU via Google Colab Pro. **Multilingual narrative text.** Every fraud transaction has a `narrative_text` field — the scam message or fraud description in the community's language. Generated by Adaptive Data by Adaption. Quality score improved from E (5.0) to A (9.2–9.4). **Reasoning traces.** 390 chain-of-thought fraud analysis examples — step-by-step investigator reasoning grounded in community-specific fraud signals. No existing fraud dataset includes this. Built for fine-tuning financial language models (FinBERT, Gemma). --- ## How It Was Built ``` 1. Scrape 1,040 real fraud narratives from CFPB, BBB Scam Tracker, and Reddit archive (Pullpush.io) 2. Profile Behavioral distributions per archetype derived from scraped narratives — amounts, channels, corridors, fraud vectors, language mix 3. Generate Tab-DDPM trains on 5,000 seed rows per archetype, learns joint feature correlations, generates 5,000 synthetic transactions per archetype 4. Narrate Adaptive Data by Adaption fills narrative_text in 8 languages per transaction's fraud context 5. Trace 390 reasoning traces generated — chain-of-thought fraud analysis for fine-tuning use ``` --- ## Schema (Key Fields) | Field | Type | Description | |---|---|---| | `transaction_id` | uuid | Unique identifier | | `archetype` | categorical | remittance / gig_worker / unbanked / itin | | `amount_usd` | float | Transaction amount | | `channel` | categorical | retail_kiosk / mobile_app / p2p / bank_wire | | `fraud_vector` | categorical | Specific scam type | | `is_fraud` | bool | Ground truth label | | `fraud_confidence` | float | 0.0–1.0 label confidence | | `narrative_text` | string | Scam description in community language | | `narrative_language` | categorical | ISO 639-1 language code | | `reasoning_trace` | string | Chain-of-thought fraud analysis (sampled rows) | ## Intended Use - Training fraud detection models on underserved community transaction patterns - Benchmarking existing models (IEEE-CIS trained) against this population - Fine-tuning financial language models on multilingual fraud narratives - Research into AI fairness and financial inclusion - NLP research on under-resourced financial language --- ## What This Is Not This is a **fully synthetic** dataset. No real transaction data. No PII. Behavioral distributions are informed by public fraud narratives and World Bank remittance corridor data — not empirically measured transaction logs. Like all synthetic fraud datasets (PaySim, Sparkov, Cifer-AF), ground truth validation against real data is not possible due to privacy constraints. --- ## Origin This dataset was created as part of the **Uncharted Data Challenge** by Adaption Labs (April 2026). It extends the [Fraud Detection Framework](https://github.com/nachammai779/Fraud-Detection-Framework---An-Agentic-RAG-Pipeline-with-Custom-Financial-SLM) — an Agentic RAG pipeline with a custom Financial SLM built on the IEEE-CIS dataset (AUC-ROC 0.9486). The underserved dataset enables direct benchmarking: how does a model trained on mainstream data perform on populations it has never seen? --- ## Citation ```bibtex @dataset{palaniappan2026underserved, author = {Palaniappan, Nachammai}, title = {Underserved Financial Fraud Dataset}, year = {2026}, publisher = {HuggingFace}, note = {Created with Adaptive Data by Adaption. Uncharted Data Challenge, Adaption Labs.}, url = {https://huggingface.co/datasets/nachammai779/underserved-financial-fraud} } ``` --- ## Credits - **Adaptive Data by Adaption** — Narrative generation and dataset enrichment - **Tab-DDPM** (Kotelnikov et al., 2022) — Tabular diffusion model - **CFPB** — Consumer Financial Protection Bureau public complaint database - **BBB Scam Tracker** — Better Business Bureau public scam reports - **Pullpush.io** — Reddit archive API --- *License: CC BY 4.0 — Free to use with attribution*
annotations_creators: [] language: - en language_creators: [] license: [] multilinguality: - monolingual pretty_name: 'remittance_fraud_narratives' size_categories: - n<1K source_datasets: - 'original' tags: - adaption - instruction-tuning - writing-editing-communication task_categories: [] task_ids: []  本数据集为经重制的版本,依托Adaption(Adaption Labs)的Adaptive Data平台制作完成。 # 汇款欺诈叙事数据集 本数据集包含用于生成第一人称叙事的提示词,这类叙事围绕通过跨境汇款服务针对移民社区实施的金融欺诈展开。每条提示均包含欺诈手段、金融工具、交易金额、汇款者人口统计特征以及语言环境等细节。当前样本的补全结果为空,表明该数据集为一组提示词集合,用于生成多语种的虚构受害者或参与者故事。 ### 数据集规模 本数据集共包含99条数据,属于指令微调数据集。 ### 重制数据集质量 最终质量评级为A级,相对质量提升幅度达86.0%。 ### 应用领域 - 写作-编辑-沟通(占比100%) ### 语言 - 英语(占比100%) ### 语气 - 轶事式(占比100%) ### 评估结果 - **质量提升情况:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/278a2951-fc5b-49f3-b78d-fcc2e75b7753.png" alt="QualityGains" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> - **评级提升情况:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/3995e54b-dc04-4e62-a109-127e7ca8ec39.png" alt="Grade" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> - **百分位分布图:** <img src="https://proteus-prod-public.s3.us-east-1.amazonaws.com/temp/a968a6d6-d46d-456b-a738-65b62c0f215a.png" alt="Percentile Chart" style="max-width: 50%; display: block; margin-left: auto; margin-right: auto;" /> # 服务不足群体金融欺诈数据集 ### 面向代表性不足社区的合成式欺诈检测数据集 **由Adaption的Adaptive Data平台制作** | 知识共享署名4.0(CC BY 4.0) | 覆盖5种语言 --- ## 数据集概述 本数据集为合成式金融欺诈数据集,覆盖**四类服务不足群体原型**——依赖跨境汇款、零工经济薪酬、预付卡以及ITIN(个人纳税人识别号,Individual Taxpayer Identification Number)交易的人群。这类群体成为欺诈目标的比例远超平均水平,但目前尚无开源欺诈数据集对其金融行为进行建模。本数据集填补了这一空白。 --- ## 四类群体原型 | 原型类别 | 目标人群 | 欺诈手段 | 支持语言 | |---|---|---|---| | **汇款发送者** | 通过西联汇款、Remitly、速汇金等渠道进行跨境汇款的移民 | 紧急呼叫诈骗、虚假汇率返利诈骗、汇款拦截诈骗 | es, ht, yo, hi, en | | **零工劳动者** | 通过CashApp、Venmo领取报酬的优步、DoorDash、Instacart平台零工 | 账户接管、SIM卡换绑、虚假平台客服呼叫诈骗 | en, hi, vi, es, yo | | **无银行账户现金充值用户** | 使用预付卡与零售服务点进行充值的人群 | 掠夺性小额贷款、充值手续费诈骗、虚假公用事业服务点诈骗 | en, es, vi, yo, hi | | **ITIN创业者** | 无社会安全号(Social Security Number,SSN)的移民小微企业主 | 合成身份欺诈、虚假纳税申报、傀儡账户诈骗 | en, es, hi, ta, vi | ## 支持语言 `en` 英语 | `es` 西班牙语 | `hi` 印式英语 | `ht` 海地克里奥尔语 | `yo` 约鲁巴语 | `vi` 越南语 | `ta` 泰米尔语 | `ta-en` 泰米尔语-英语 --- ## 本数据集的独特优势 **暂无同类公开数据集覆盖此类群体**:PaySim仅模拟通用移动货币交易,Sparkov针对中产阶级信用卡交易建模,IEEE-CIS数据集聚焦电子商务场景,均未覆盖汇款服务点、零工薪酬结算或ITIN关联账户的欺诈场景。 **基于扩散模型生成,而非规则模板**:表格数据通过Tab-DDPM(表格数据去噪扩散模型)生成,能够学习行为特征间的联合相关性,而非仅对单列进行独立采样。模型基于Google Colab Pro平台,在A100 GPU上完成训练。 **多语种叙事文本**:每笔欺诈交易均包含`narrative_text`字段,即使用目标社区语言撰写的诈骗话术或欺诈描述。由Adaption的Adaptive Data平台生成,质量评分从E级(5.0)提升至A级(9.2–9.4)。 **推理溯源信息**:包含390条思维链式欺诈分析示例,即基于社区专属欺诈特征的调查人员分步推理过程。目前尚无任何欺诈数据集包含此类内容,本数据集专为金融大语言模型(如FinBERT、Gemma)的微调设计。 --- ## 数据集构建流程 1. 数据爬取:从美国消费者金融保护局(CFPB,Consumer Financial Protection Bureau)、美国商业改进局(BBB,Better Business Bureau)欺诈追踪平台以及Reddit存档网站(Pullpush.io)爬取1040条真实欺诈叙事文本 2. 特征建模:基于爬取的叙事文本,提取各类原型的行为分布特征,包括交易金额、渠道、汇款走廊、欺诈手段与语言分布 3. 数据生成:针对每类原型,使用5000条种子数据训练Tab-DDPM模型,学习特征间的联合相关性,最终每类原型生成5000条合成交易数据 4. 叙事生成:由Adaption的Adaptive Data平台为每笔交易基于欺诈场景生成8种语言的`narrative_text`字段内容 5. 推理溯源:生成390条思维链式欺诈分析文本,用于模型微调 --- ## 数据Schema(核心字段) | 字段名 | 数据类型 | 字段说明 | |---|---|---| | `transaction_id` | 通用唯一识别码(UUID) | 唯一标识符 | | `archetype` | 分类变量 | 原型类别,可选值为remittance(汇款发送者)、gig_worker(零工劳动者)、unbanked(无银行账户用户)、itin(ITIN创业者) | | `amount_usd` | 浮点型 | 以美元计价的交易金额 | | `channel` | 分类变量 | 交易渠道,可选值为零售服务点、移动应用、P2P转账、银行电汇 | | `fraud_vector` | 分类变量 | 具体欺诈类型 | | `is_fraud` | 布尔型 | 欺诈标签(真实值) | | `fraud_confidence` | 浮点型 | 标签置信度,取值范围0.0–1.0 | | `narrative_text` | 字符串型 | 目标社区语言撰写的欺诈描述文本 | | `narrative_language` | 分类变量 | ISO 639-1标准语言代码 | | `reasoning_trace` | 字符串型 | 思维链式欺诈分析文本(仅部分样本包含) | ## 预期应用场景 - 针对服务不足群体的交易模式训练欺诈检测模型 - 基于本数据集对现有模型(如基于IEEE-CIS训练的模型)进行基准测试 - 基于多语种欺诈叙事文本微调金融大语言模型 - 开展AI公平性与金融包容性相关研究 - 针对资源匮乏的金融领域语言开展自然语言处理研究 --- ## 数据集局限性说明 本数据集为**完全合成生成**的数据集,不包含任何真实交易数据与个人可识别信息(Personally Identifiable Information,PII)。其行为分布特征基于公开欺诈叙事文本与世界银行汇款走廊数据构建,而非基于实测交易日志。与所有合成式欺诈数据集(如PaySim、Sparkov、Cifer-AF)一样,由于隐私限制,无法基于真实交易数据对本数据集的标签真实性进行验证。 --- ## 数据集起源 本数据集由Adaption Labs于2026年4月发起的**未知数据挑战赛(Uncharted Data Challenge)**中开发。本数据集扩展了[欺诈检测框架](https://github.com/nachammai779/Fraud-Detection-Framework---An-Agentic-RAG-Pipeline-with-Custom-Financial-SLM)——一个基于IEEE-CIS数据集构建的智能检索增强生成(Retrieval Augmented Generation,RAG)管道,搭载自定义金融大语言模型(AUC-ROC值为0.9486)。本服务不足群体数据集可用于直接基准测试:基于主流数据训练的模型在从未接触过的群体数据上表现如何? --- ## 引用格式 bibtex @dataset{palaniappan2026underserved, author = {Palaniappan, Nachammai}, title = {Underserved Financial Fraud Dataset}, year = {2026}, publisher = {HuggingFace}, note = {Created with Adaptive Data by Adaption. Uncharted Data Challenge, Adaption Labs.}, url = {https://huggingface.co/datasets/nachammai779/underserved-financial-fraud} } --- ## 致谢 - **Adaption的Adaptive Data平台**:负责叙事文本生成与数据集富集 - **Tab-DDPM(Kotelnikov等人,2022)**:表格数据扩散模型 - **美国消费者金融保护局(CFPB)**:公开投诉数据库 - **美国商业改进局(BBB)欺诈追踪平台**:公开欺诈报告数据库 - **Pullpush.io**:Reddit存档API --- *许可证:CC BY 4.0 — 标注来源即可自由使用*