
trollek/ThoughtfulAssistant-v01
收藏官方服务:
资源简介:
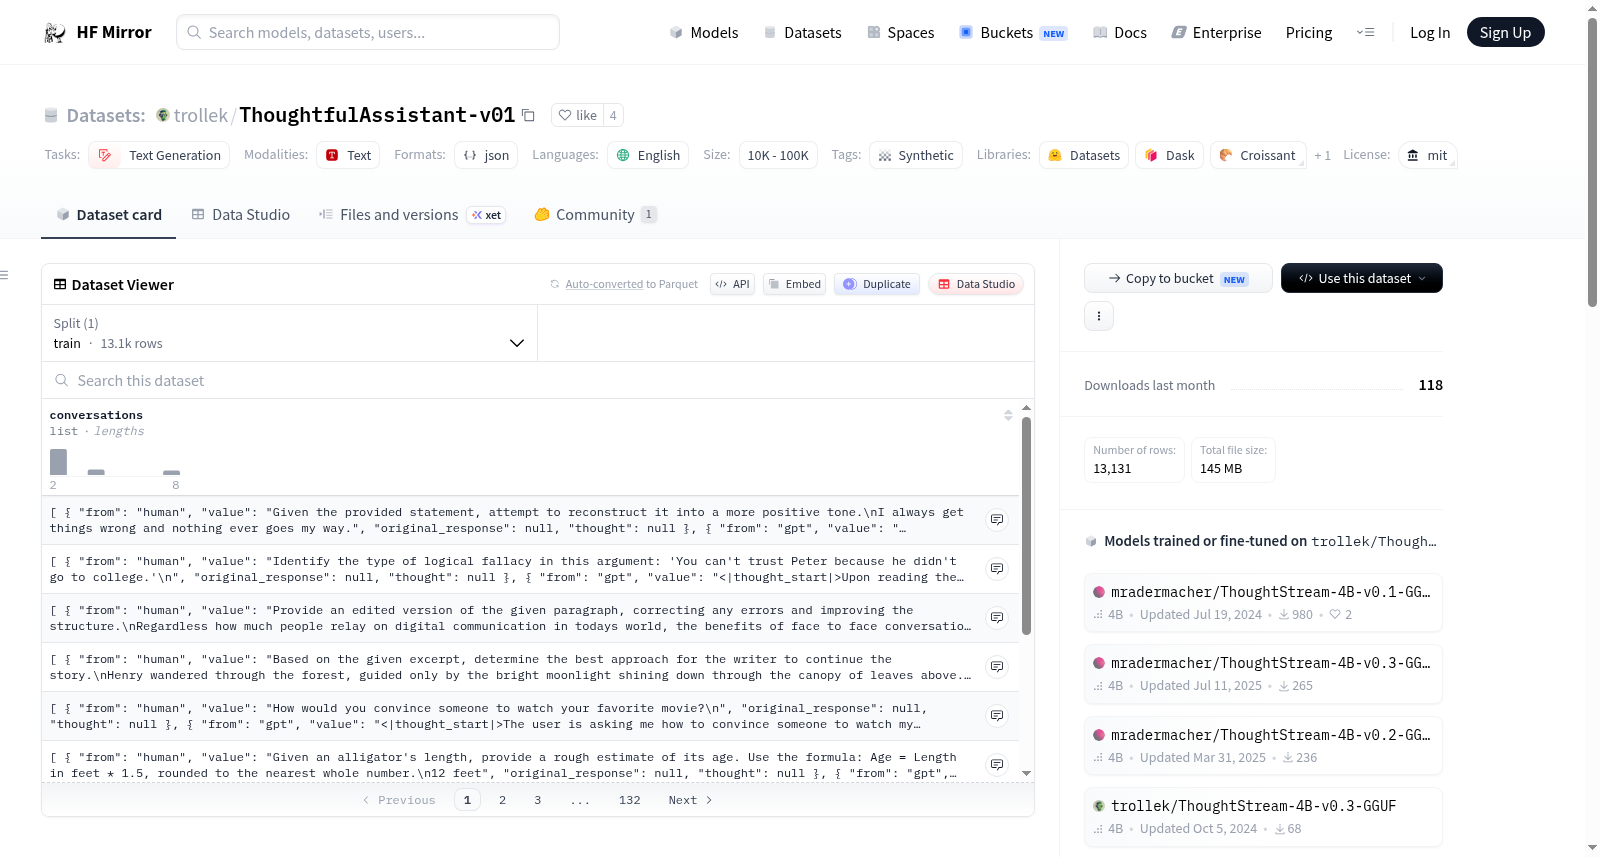
该数据集的创建目的是教导语言模型在回答问题之前进行思考。通过特定的提示模板生成响应背后的推理过程,并将这些推理过程格式化。数据集的内容来源于多个已存在的数据集,并经过过滤和整合。生成推理过程所使用的模型包括Mistral-7B-Instruct-v0.3和Nous-Hermes-2-Mixtral-8x7B-DPO。数据集的格式为JSON,包含用户指令和模型响应的结构,其中模型响应包括推理过程和原始响应。
This dataset is designed to train language models to think before answering questions. By using a specific prompt template to generate responses that include the thought process, the dataset format includes human instructions and GPT responses, where the GPT responses contain thought start and end markers, as well as the original response. The construction of the dataset involves filtering multi-turn conversations from multiple source datasets and using specific models to generate thought content.
提供机构:
trollek搜集汇总
数据集介绍
背景与挑战
背景概述
该数据集是用于训练语言模型在生成回答前进行思考的合成对话数据集,包含约13k条多轮对话,每条对话的GPT回答前都插入了思考过程(thought/rationale)。数据主要源自Capybara、Magpie等数据集,并通过Mistral-7B等模型生成思考内容,以增强模型推理能力。
以上内容由遇见数据集搜集并总结生成


