lemexp-commercial-llm-experiment-results
收藏资源简介:
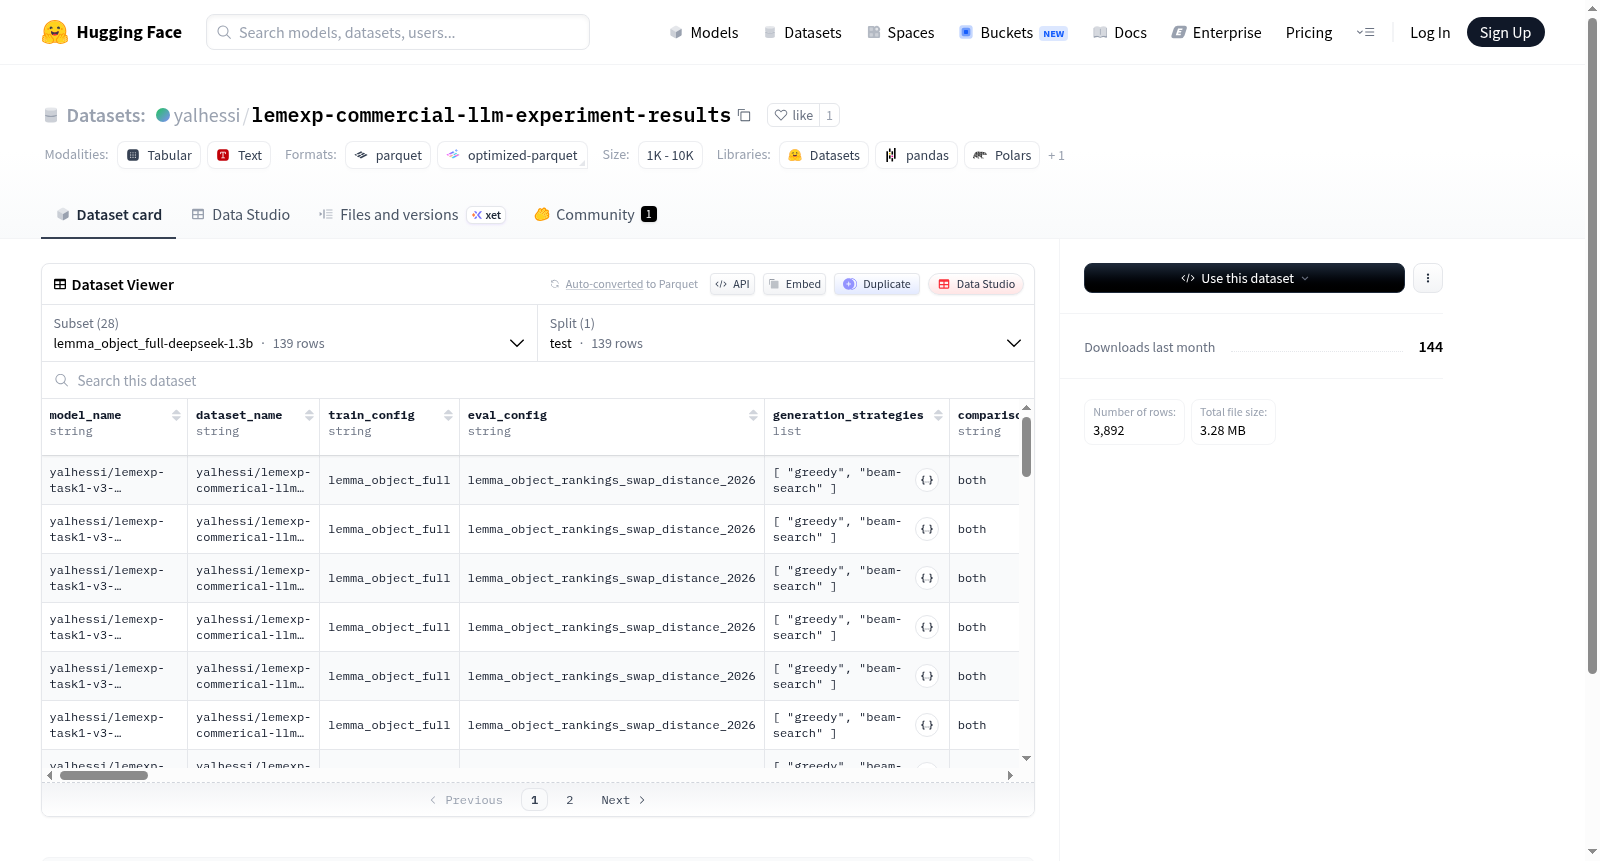
该数据集是一个用于评估语言模型在自动定理证明任务中性能的基准数据集,特别关注于Isabelle定理证明器环境中的引理对象生成。数据集包含多个配置,分别对应不同的模型(如DeepSeek-1.3b、DeepSeek-6.7b和Llama)和任务变体(完整引理对象、无定义完整引理对象、小型引理对象)。每个配置包含139个测试样本,每个样本提供了定理证明相关的上下文信息,包括理论文件、引理名称、引理命令、符号、类型、定义、模板以及期望的输出(引理对象)。数据集的核心是模型生成的预测结果及其评估指标,涵盖了贪婪解码和集束搜索两种生成策略。评估指标包括基于字符串的Levenshtein距离分数,以及通过Isabelle验证的布尔匹配结果和成功计数。该数据集适用于研究形式化方法、自动定理证明、代码生成以及语言模型在结构化逻辑推理任务中的能力评估。
This dataset is a benchmark dataset for evaluating the performance of language models on automated theorem proving tasks, with a specific focus on lemma object generation in the Isabelle theorem prover environment. The dataset includes multiple configurations corresponding to different models (e.g., DeepSeek-1.3b, DeepSeek-6.7b, and Llama) and task variants (full lemma objects, complete lemma objects without definitions, small lemma objects). Each configuration contains 139 test samples, with each sample providing context information related to theorem proving, including theory files, lemma names, lemma commands, symbols, types, definitions, templates, and the expected output (lemma objects). The core of the dataset consists of the model-generated prediction results and their evaluation metrics, covering two generation strategies: greedy decoding and beam search. The evaluation metrics include string-based Levenshtein distance scores, as well as Isabelle-verified boolean matching results and success counts. This dataset is applicable to research on formal methods, automated theorem proving, code generation, and the evaluation of language models' capabilities in structured logical reasoning tasks.