voice_deepfake_detection_dataset
收藏资源简介:
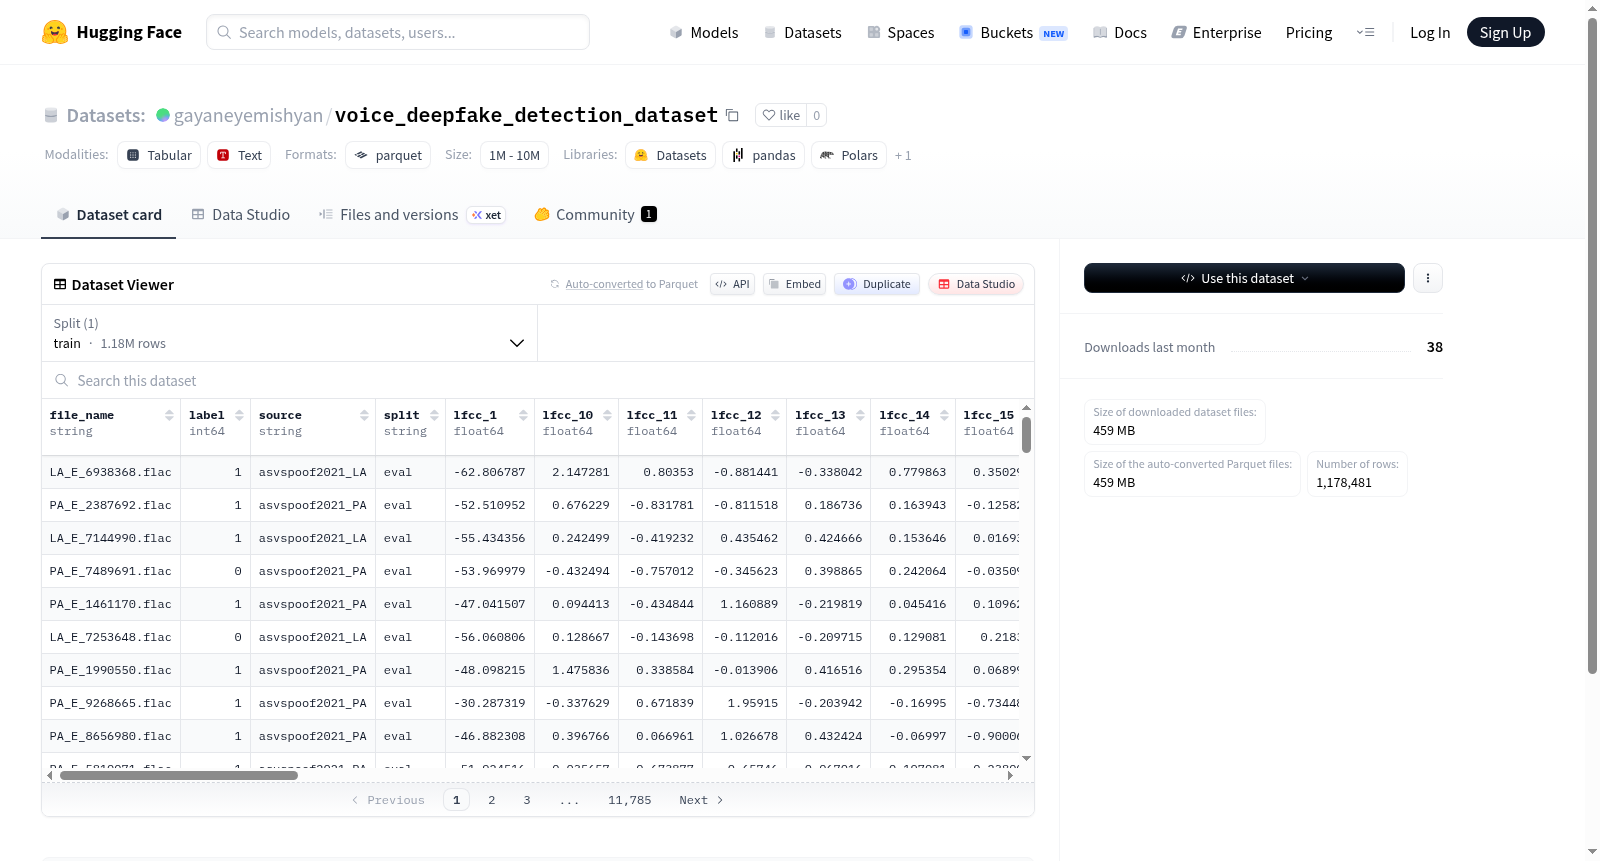
该数据集包含1,178,481个训练样本,每个样本包含多个音频特征,包括20个线性频率倒谱系数(LFCC)和20个梅尔频率倒谱系数(MFCC)。数据集还包含文件名、标签、来源和分割信息。尽管README未明确说明数据集的具体用途,但基于其特征结构,它可能适用于音频分类或相关任务。数据集仅包含一个训练分割,总大小为442,667,808字节,下载大小为458,761,298字节。
This dataset contains 1,178,481 training samples, each of which includes multiple audio features, specifically 20 Linear Frequency Cepstral Coefficients (LFCC) and 20 Mel-Frequency Cepstral Coefficients (MFCC). The dataset also includes file names, labels, source information, and split information. Although the README does not explicitly specify the specific intended use of this dataset, based on its feature structure, it may be suitable for audio classification or related tasks. This dataset only contains one training split, with a total size of 442,667,808 bytes and a download size of 458,761,298 bytes.
数据集概述
基本信息
- 数据集名称: voice_deepfake_detection_dataset
- 托管地址: https://huggingface.co/datasets/gayaneyemishyan/voice_deepfake_detection_dataset
- 默认配置: default
数据集规模
- 下载大小: 458,761,298 字节
- 数据集大小: 442,667,808 字节
- 数据分割: 仅包含训练集(train)
- 训练集样本数量: 1,178,481 条
- 训练集大小: 442,667,808 字节
数据特征
数据集包含以下特征(列):
元数据特征
file_name: 字符串类型,文件名。label: 64位整数类型,标签。source: 字符串类型,数据来源。split: 字符串类型,数据分割标识。
音频特征
- LFCC特征: 包含
lfcc_1至lfcc_20,共20个线性频率倒谱系数特征,均为64位浮点数类型。 - MFCC特征: 包含
mfcc_1至mfcc_20,共20个梅尔频率倒谱系数特征,均为64位浮点数类型。
数据结构
- 数据文件路径:
data/train-*