instruction_following-ifeval
收藏资源简介:
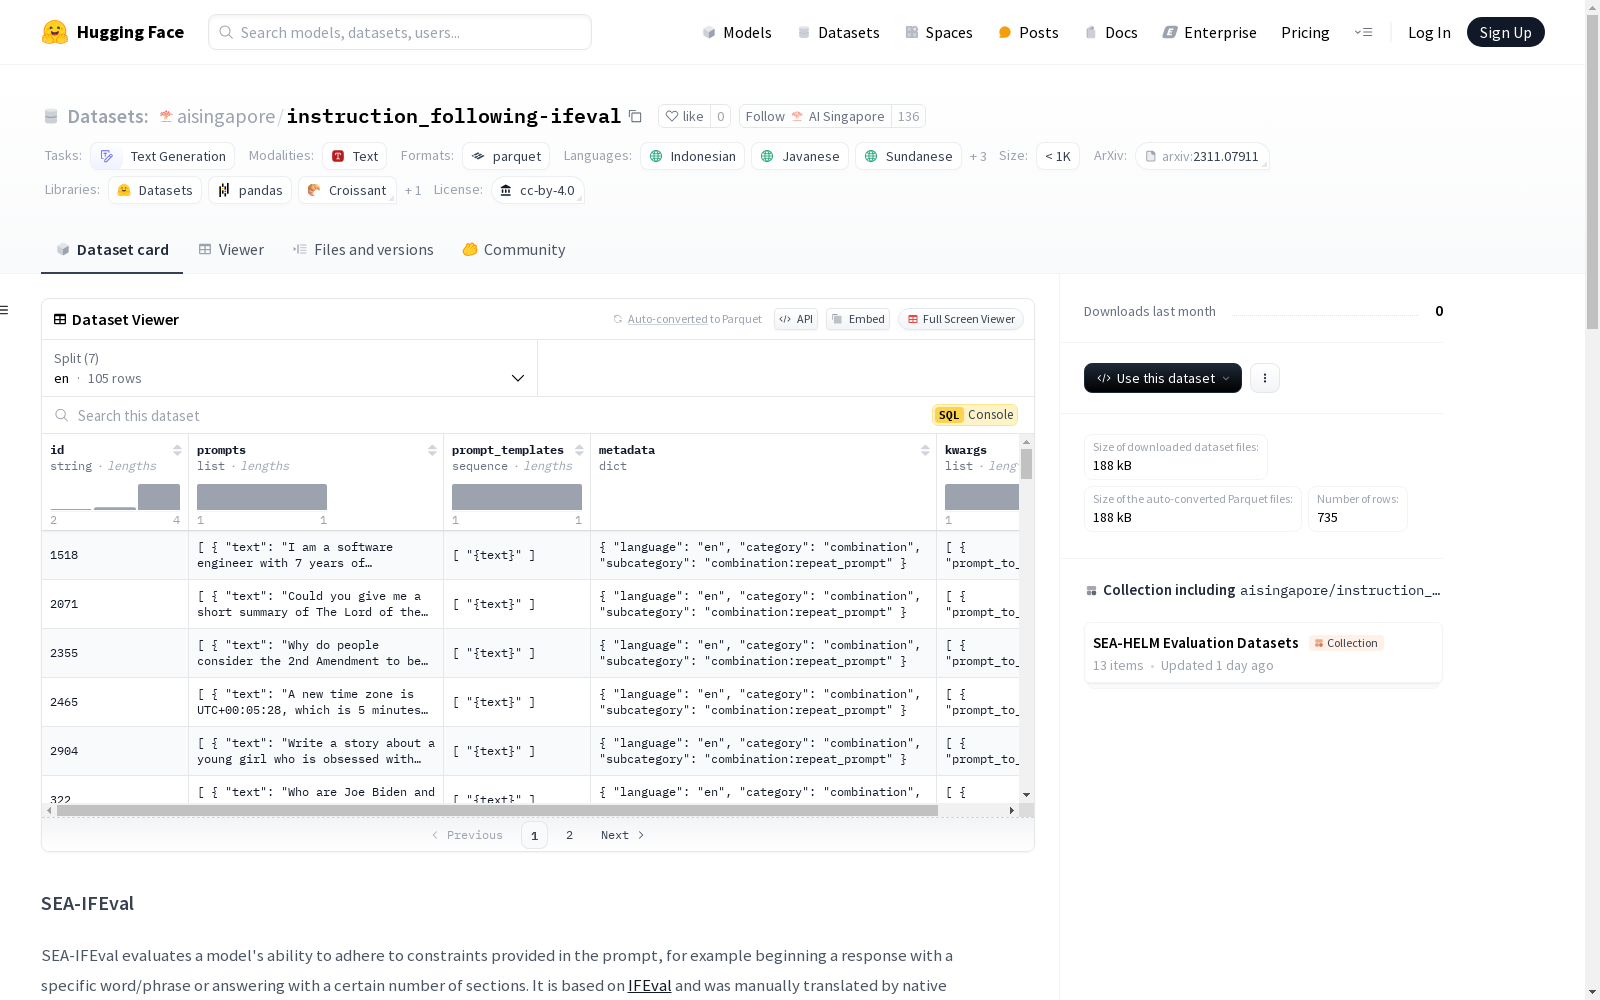
SEA-IFEval数据集用于评估模型在遵循提示中提供的约束条件的能力,例如以特定词/短语开始响应或以特定数量的部分回答问题。该数据集基于IFEval,并由母语者手动翻译为印尼语、爪哇语、巽他语、泰语、他加禄语和越南语。数据集按语言划分,每种语言有105个样本,统计信息包括每种语言的样本数量、GPT-4o、Gemma 2和Llama 3的token数量。数据集的下载大小为187918字节,数据集大小为312110字节,总token数量分别为33875、34959和40253。数据集的许可证为CC BY 4.0,适用于印尼语、爪哇语、他加禄语、巽他语和越南语。
The SEA-IFEval dataset is developed to evaluate models' capability to follow constraints specified in prompts, such as starting responses with a designated word/phrase or structuring answers to a question with a fixed number of sections. This dataset is based on IFEval, and was manually translated into Indonesian, Javanese, Sundanese, Thai, Tagalog, and Vietnamese by native speakers. The dataset is partitioned by language, with 105 samples per language. Its statistical information includes the number of samples per language, as well as the token counts of GPT-4o, Gemma 2, and Llama 3. The download size of the dataset is 187,918 bytes, and the total dataset size is 312,110 bytes. The total token counts for the three models are 33,875, 34,959, and 40,253 respectively. The dataset is licensed under CC BY 4.0, which applies to Indonesian, Javanese, Tagalog, Sundanese, and Vietnamese languages.