ai4privacy/pii-masking-nano-1k
收藏资源简介:
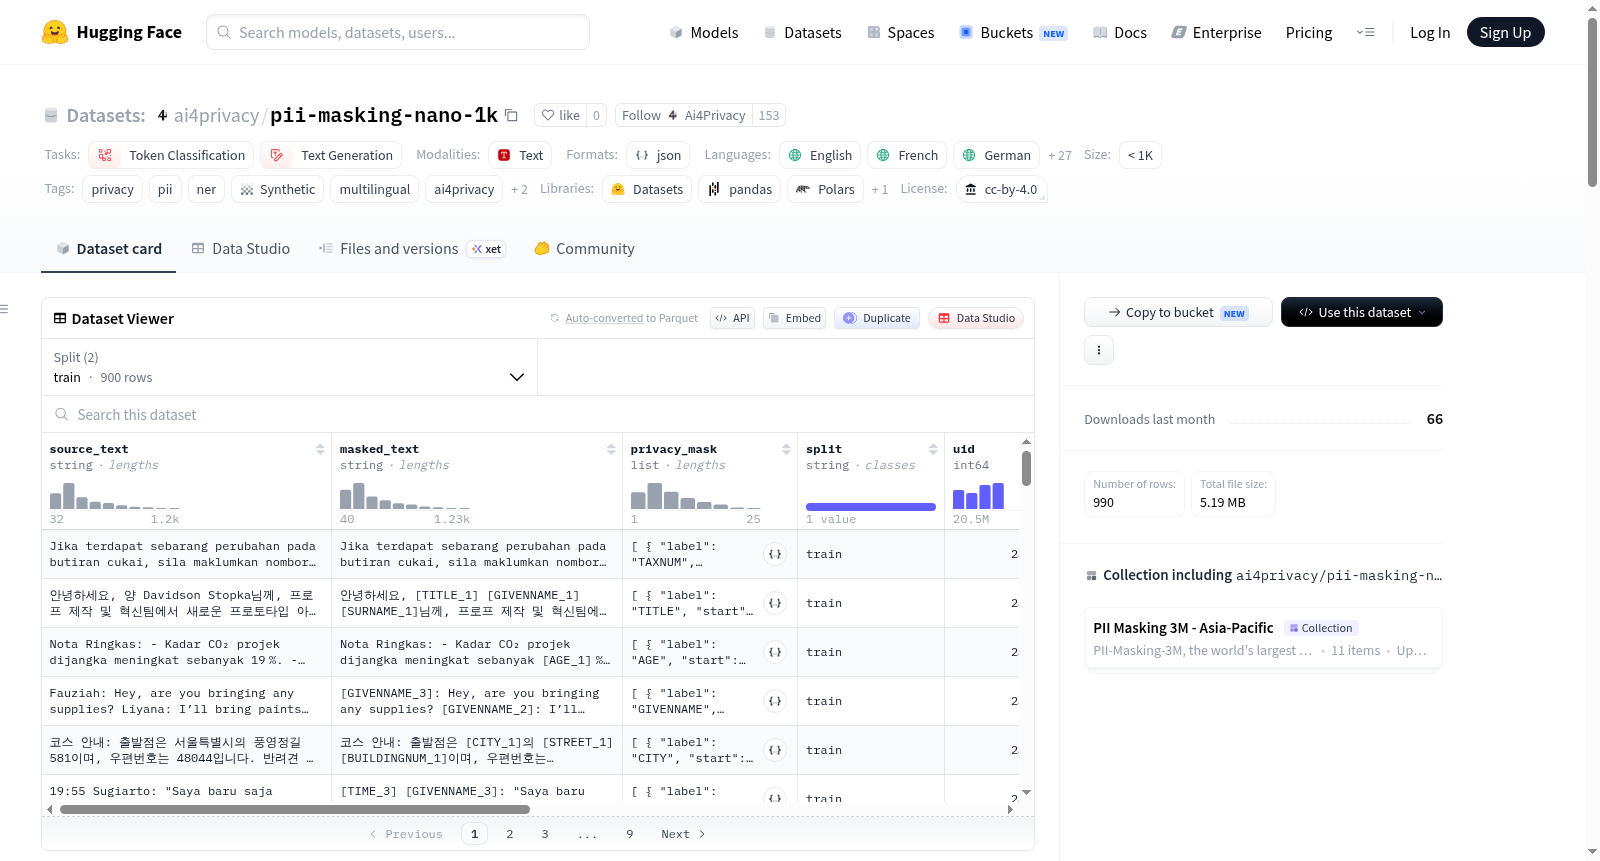
PII掩码纳米版:多语言样本是一个纳米级分层样本,源自PII-Masking-3M家族的主要版本pii-masking-openpii-1.5m数据集。该样本通过(source_dataset, language)进行比例抽样,确保每个语言和标签都有代表性,亚洲太平洋地区的行优先显示。数据集包含990个示例,其中训练集900个,验证集90个,涵盖19种个人身份信息(PII)标签类型(如姓名、电子邮件、日期、地址等)和30种语言,涉及37个地区,总共有7,611个标注。数据集格式为JSONL,许可证为CC-BY-4.0,专门用于隐私保护任务,如PII掩码,属于token-classification和text-generation类别。数据仅包含合成PII,无真实个人数据。
PII Masking Nano Edition: Multilingual Sample is a nano-scale stratified sample derived from the pii-masking-openpii-1.5m dataset, the primary release of the PII-Masking-3M family. This sample adopts proportional sampling based on (source_dataset, language) to ensure representative coverage for each language and label, with entries from the Asia-Pacific region displayed first. The dataset contains 990 total examples, including 900 for training and 90 for validation. It covers 19 types of Personally Identifiable Information (PII) labels (e.g., name, email, date, address, etc.), 30 languages, and 37 regions, with a total of 7,611 annotations. The dataset is formatted in JSONL, licensed under CC-BY-4.0, and is specifically designed for privacy protection tasks such as PII masking, falling under the token-classification and text-generation task categories. All data in this dataset consists of synthetic PII, with no real personal data included.