Vl-RewardBench
收藏资源简介:
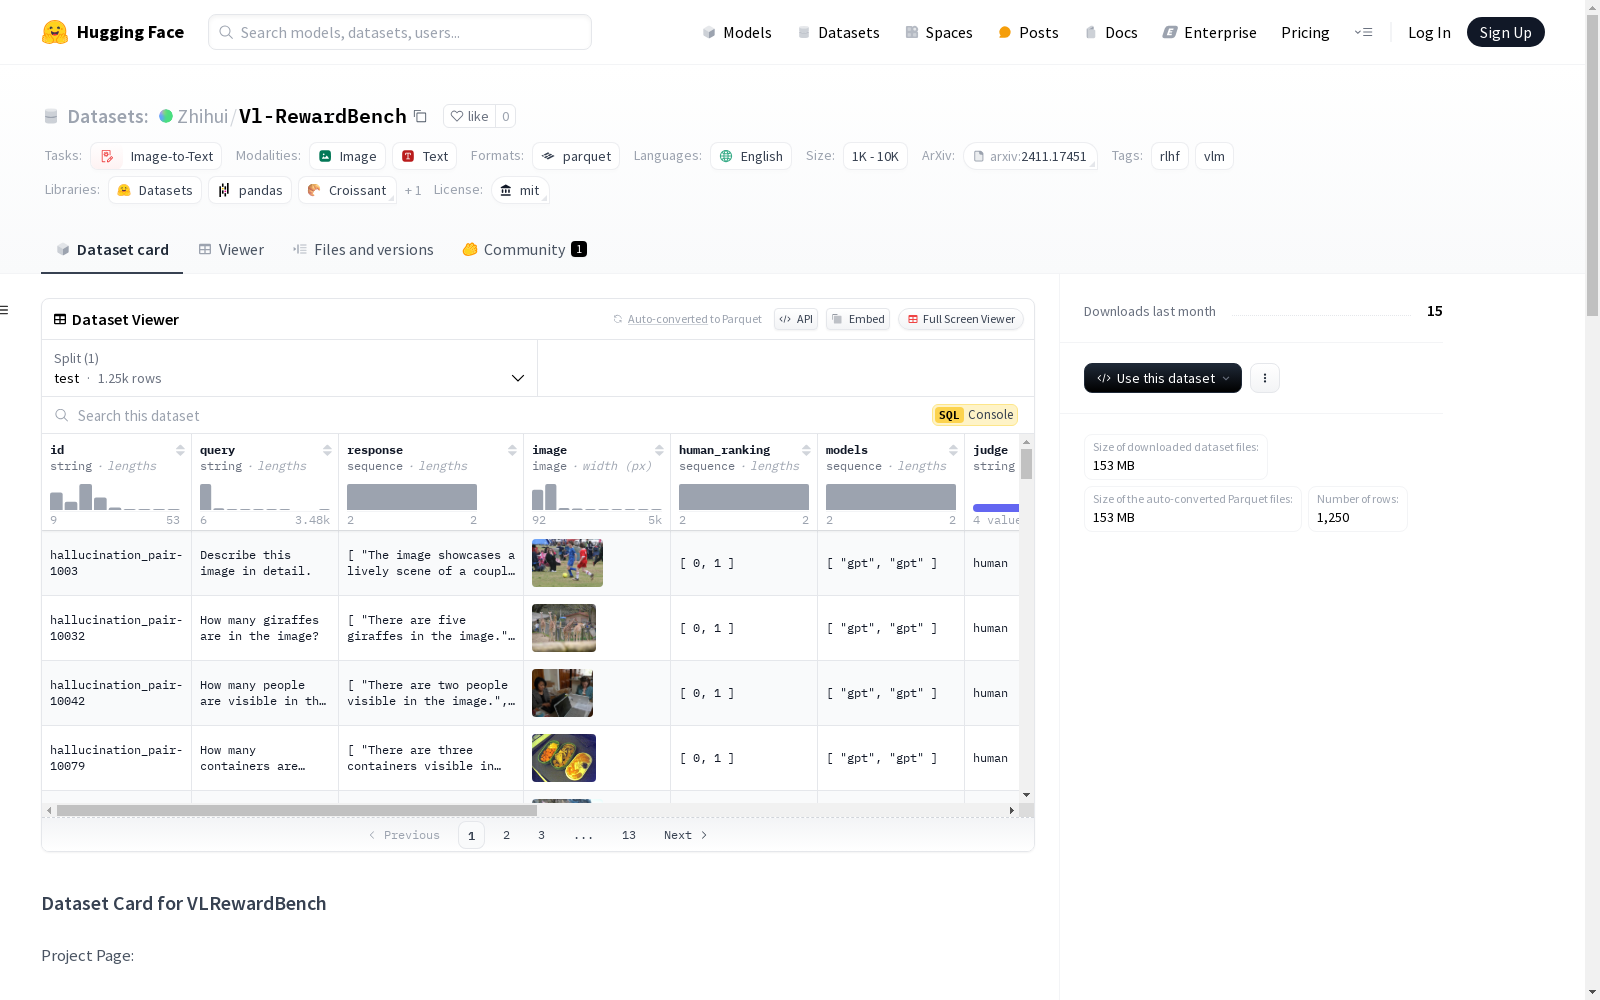
VLRewardBench是一个综合性的基准测试,旨在评估视觉语言生成奖励模型(VL-GenRMs)在视觉感知、幻觉检测和推理任务中的表现。该基准包含1,250个高质量的示例,专门设计用于探测模型的局限性。每个实例包含多模态查询,涵盖三个关键领域:一般多模态查询、视觉幻觉检测任务和多模态知识与数学推理。数据集的结构包括多个字段,如实例ID、多模态提示的文本查询、图像输入、由模型生成的两个候选响应、人类对两个响应的排名、错误分析标签、生成响应的模型以及实例的来源数据集。数据集的目的是用于研究用途,特别是评估和改进视觉语言奖励模型,研究模型在视觉感知和推理中的局限性,以及开发更好的多模态AI系统。
VLRewardBench is a comprehensive benchmark designed to evaluate Visual-Language Generation Reward Models (VL-GenRMs) on visual perception, hallucination detection and reasoning tasks. This benchmark comprises 1,250 high-quality examples specifically crafted to probe the limitations of such models. Each instance contains multimodal queries spanning three core domains: general multimodal queries, visual hallucination detection tasks, and multimodal knowledge and mathematical reasoning. The dataset structure includes multiple fields, such as instance ID, text query of multimodal prompts, image input, two candidate responses generated by the model, human rankings of the two responses, error analysis labels, the model that generated the responses, and the source dataset of the instance. The dataset is intended for research purposes, specifically to evaluate and improve visual-language reward models, investigate the limitations of models in visual perception and reasoning, and develop better multimodal AI systems.
VLRewardBench 数据集概述
数据集摘要
VLRewardBench 是一个综合基准,旨在评估视觉-语言生成奖励模型(VL-GenRMs)在视觉感知、幻觉检测和推理任务中的表现。该基准包含 1,250 个高质量示例,专门设计用于探测模型的局限性。
数据集结构
每个实例包含跨三个关键领域的多模态查询:
- 来自真实用户的通用多模态查询
- 视觉幻觉检测任务
- 多模态知识和数学推理
数据字段
关键字段:
id: 实例 IDquery: 多模态提示的文本查询image: 多模态提示的图像输入response: 由模型生成的两个候选响应列表human_ranking: 两个响应的排名,[0, 1]表示第一个响应更优,[1, 0]表示第二个响应更优human_error_analysis: 偏好对的注释错误标签models: 生成响应的相应模型,适用于wildvision子集的实例query_source: 实例的来源数据集- WildVision
- POVID
- RLAIF-V
- RLHF-V
- MMMU-Pro
- MathVerse
注释
- 使用小型 LVLMs 过滤具有挑战性的样本
- 强大的商业模型生成带有显式推理路径的响应
- GPT-4o 进行质量评估
- 所有偏好标签都经过人工验证
使用目的
该数据集仅用于研究目的,具体用于:
- 评估和改进视觉-语言奖励模型
- 研究模型在视觉感知和推理中的局限性
- 开发更好的多模态 AI 系统
许可证
仅限研究使用。使用受 GPT-4o 和 Claude 的许可证协议限制。
引用信息
bibtex @article{VLRewardBench, title={VLRewardBench: A Challenging Benchmark for Vision-Language Generative Reward Models}, author={Lei Li and Yuancheng Wei and Zhihui Xie and Xuqing Yang and Yifan Song and Peiyi Wang and Chenxin An and Tianyu Liu and Sujian Li and Bill Yuchen Lin and Lingpeng Kong and Qi Liu}, year={2024}, journal={arXiv preprint arXiv:2411.17451} }