HRM-He-corpus-objective
收藏资源简介:
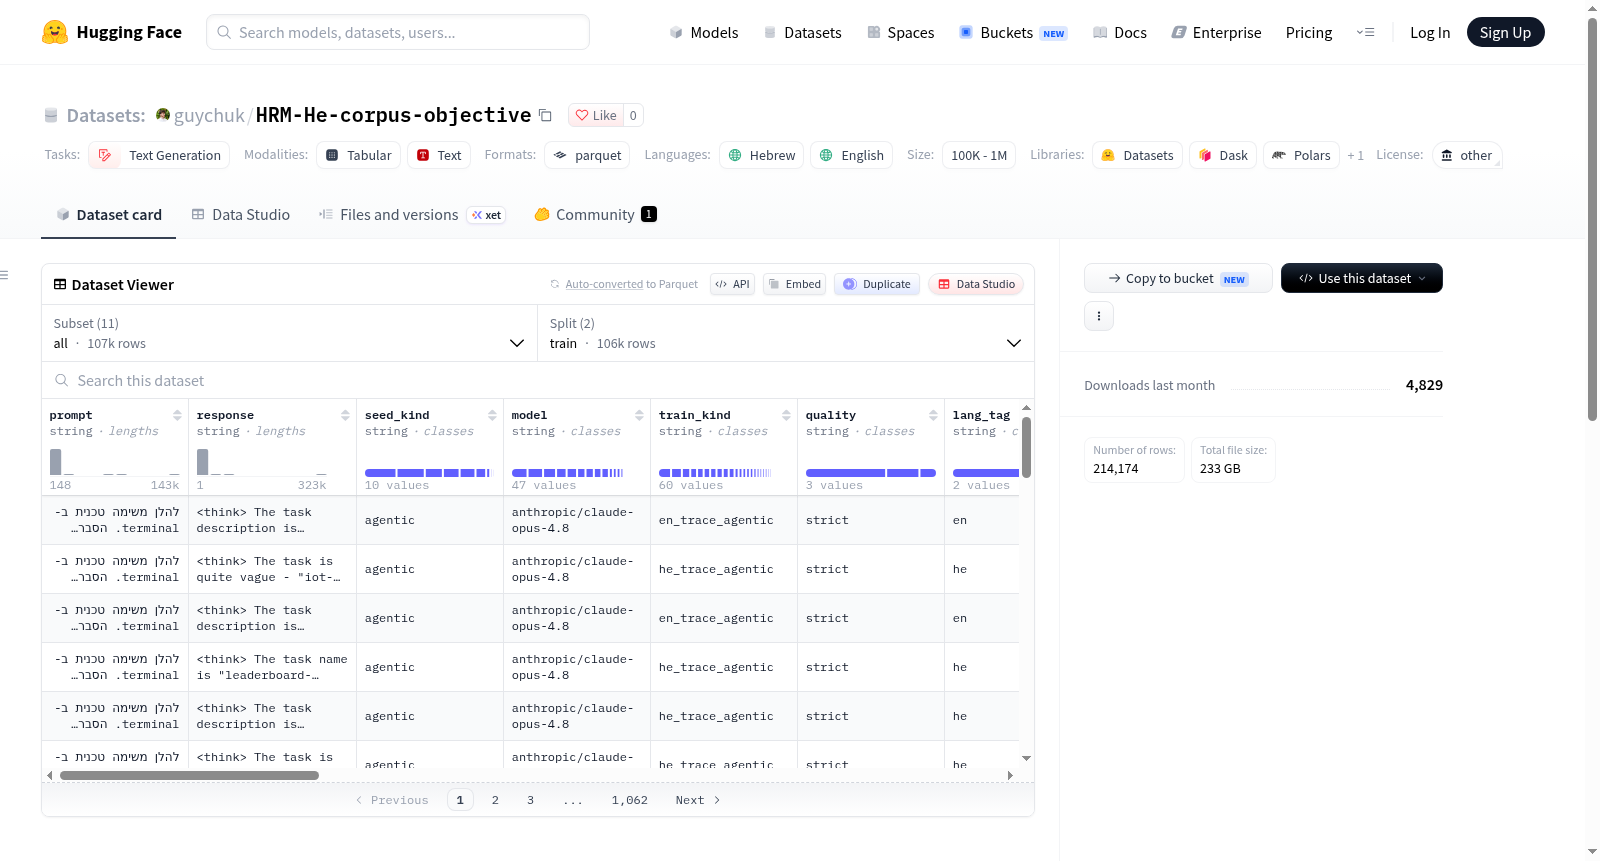
该数据集名为“Hebrew reasoning traces”,用于生成希伯来语推理链(chain-of-thought),专为希伯来语/英语代码专用语言模型设计。它通过基于代码、网络安全、代理、数学和通用推理种子生成推理轨迹,填补了现成希伯来语推理数据几乎不存在的空白。数据集包含多个配置子集:all(默认)、agentic、code、cyber、evol、magpie、math、math_easy、reason 和 web。默认配置保留了所有训练数据,但排除了两种不合格情况:最终答案错误(answer_ok 为 False)和阿拉伯语漂移。每个样本包含以下字段:quality(质量标签,取值为 strict——干净、partial——有推理但无明确答案、direct——有答案但无推理块)、lang_tag(语言标签,若推理以希伯来语为主则为 he,否则为 en,希伯来语答案与英语推理的组合是支持的形态)、train_kind(构建器使用的具体标签,如 he_trace_cyber_partial)。验证集通过对提示进行哈希,保留1%的样本,确保同一种子在多次生成中保持在同一侧。数据由约34个不同的模型生成,model 列记录了每个样本的来源。数据集的语言为希伯来语和英语,许可证为 other,任务类别为文本生成(text-generation)。
The dataset is named Hebrew reasoning traces, designed to generate chain-of-thought reasoning in Hebrew, tailored for Hebrew/English code-specific language models. It fills the gap of almost nonexistent Hebrew reasoning data by generating reasoning traces based on seeds from code, cybersecurity, agent, math, and general reasoning. The dataset includes multiple configuration subsets: all (default), agentic, code, cyber, evol, magpie, math, math_easy, reason, and web. The default configuration retains all training data except for two disqualifying conditions: final answer incorrect (answer_ok is False) and Arabic drift. Each sample contains fields: quality (quality label with values strict for clean, partial for reasoning without explicit answer, direct for answer without reasoning block), lang_tag (language tag he if reasoning is predominantly Hebrew, otherwise en; Hebrew answer with English reasoning is supported), train_kind (specific builder label like he_trace_cyber_partial). The validation set is constructed by hashing prompts and retaining 1% of samples, ensuring the same seed stays on the same side across multiple generations. Data is generated by approximately 34 different models, with the model column recording the source for each sample. The dataset language is Hebrew and English, license is other, and the task category is text-generation.
HRM-He-corpus-objective 数据集概述
基本信息
- 语言:希伯来语(he)和英语(en)
- 许可证:其他(other)
- 任务类别:文本生成(text-generation)
- 数据格式:Parquet 文件
数据集内容
该数据集包含生成的希伯来语**思维链(chain-of-thought)**数据,覆盖以下领域:
- 代码(code)
- 网络安全(cybersecurity)
- 智能体(agentic)
- 数学(math)
- 一般推理(general-reasoning)
数据集专为希伯来语/英语代码专业语言模型构建,旨在弥补现成的希伯来语推理数据几乎不存在的问题。
数据配置
数据集提供默认配置 all 及 9 个特定子配置:
| 配置名 | 说明 |
|---|---|
all |
全部数据(默认) |
agentic |
智能体相关数据 |
code |
代码相关数据 |
cyber |
网络安全相关数据 |
evol |
演化数据 |
magpie |
Magpie 数据 |
math |
数学数据 |
math_easy |
简单数学数据 |
reason |
推理数据 |
web |
网络数据 |
每个配置均包含 train 和 validation 两个分割。
数据筛选标准
默认配置中保留所有训练语料行,但排除以下两类数据:
- 最终答案错误(
answer_ok为 False) - 阿拉伯语漂移(Arabic drift)
其余数据均保留并打上标签。
数据标签字段
quality:数据质量标签strict:干净数据partial:有推理但无明确答案direct:有答案但无推理块
lang_tag:语言标签he:希伯来语推理(希伯来语占比 ≥ 0.6)en:英语推理(英语推理搭配希伯来语答案是受支持的形态)
train_kind:分片构建器使用的精确标签(如he_trace_cyber_partial)
可通过筛选 quality == strict 获取干净子集,但不同类别中严格数据的占比差异较大。
数据分割
- 验证集:按提示词哈希保留 1% 数据,确保同一种子在多次重新生成时始终位于同一侧。
数据来源
- 数据由约 34 种不同模型生成
model列记录了每条数据由哪个模型产生- 下游使用需遵守相应模型的条款