datademon4/ghostbuster-essay-cleaned
收藏资源简介:
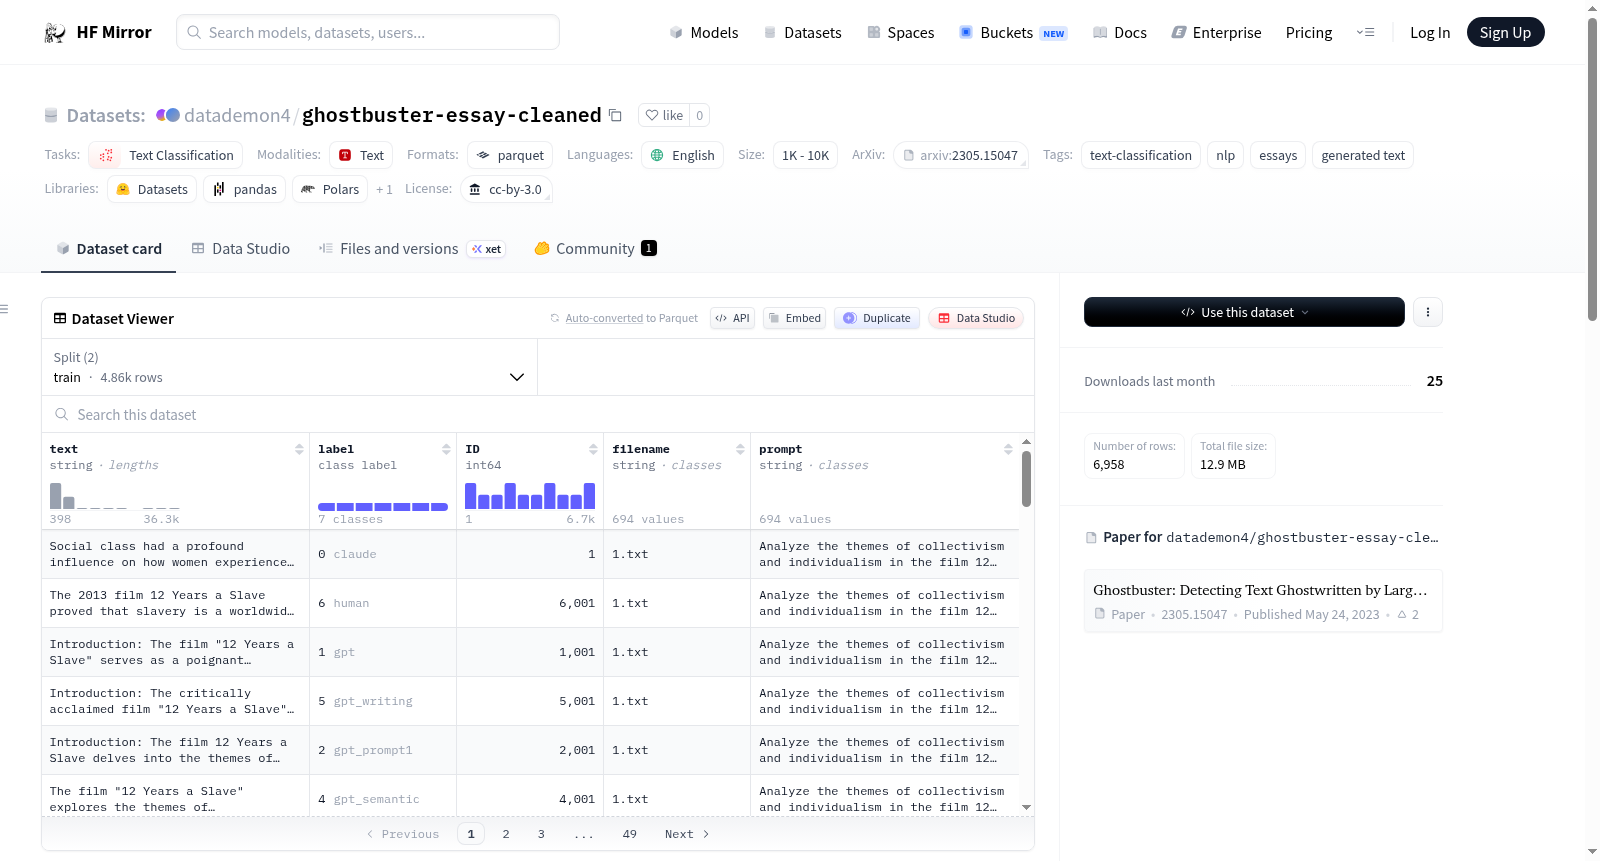
Ghostbuster论文数据集(人类撰写与LLM撰写的论文,已清理)用于区分人类撰写和大型语言模型(LLM)撰写的论文。数据集包含清理后的文本,已删除空文本或非常短的文本。数据集包含各种标签,指示文本的来源(如claude、gpt、human等)。数据集结构包含字段如text、label、ID、filename和prompt,并分为训练集和测试集。该数据集由论文《Ghostbuster: Detecting Text Ghostwritten by Large Language Models》的作者创建,采用CC By 3.0许可证。
Essay dataset used in the paper Ghostbuster: Detecting Text Ghostwritten by Large Language Models (see citation below). Empty or very short texts removed. The original data was txt files in folders for each label. The filenames allow you to match generated texts across the various prompts. I have included the prompt corresponding to each text, but see the paper for an authoritative source on how the texts were generated and the meaning of each label. Note: The splits have been added. These are not a feature of the source data.