AVCAffe
收藏资源简介:
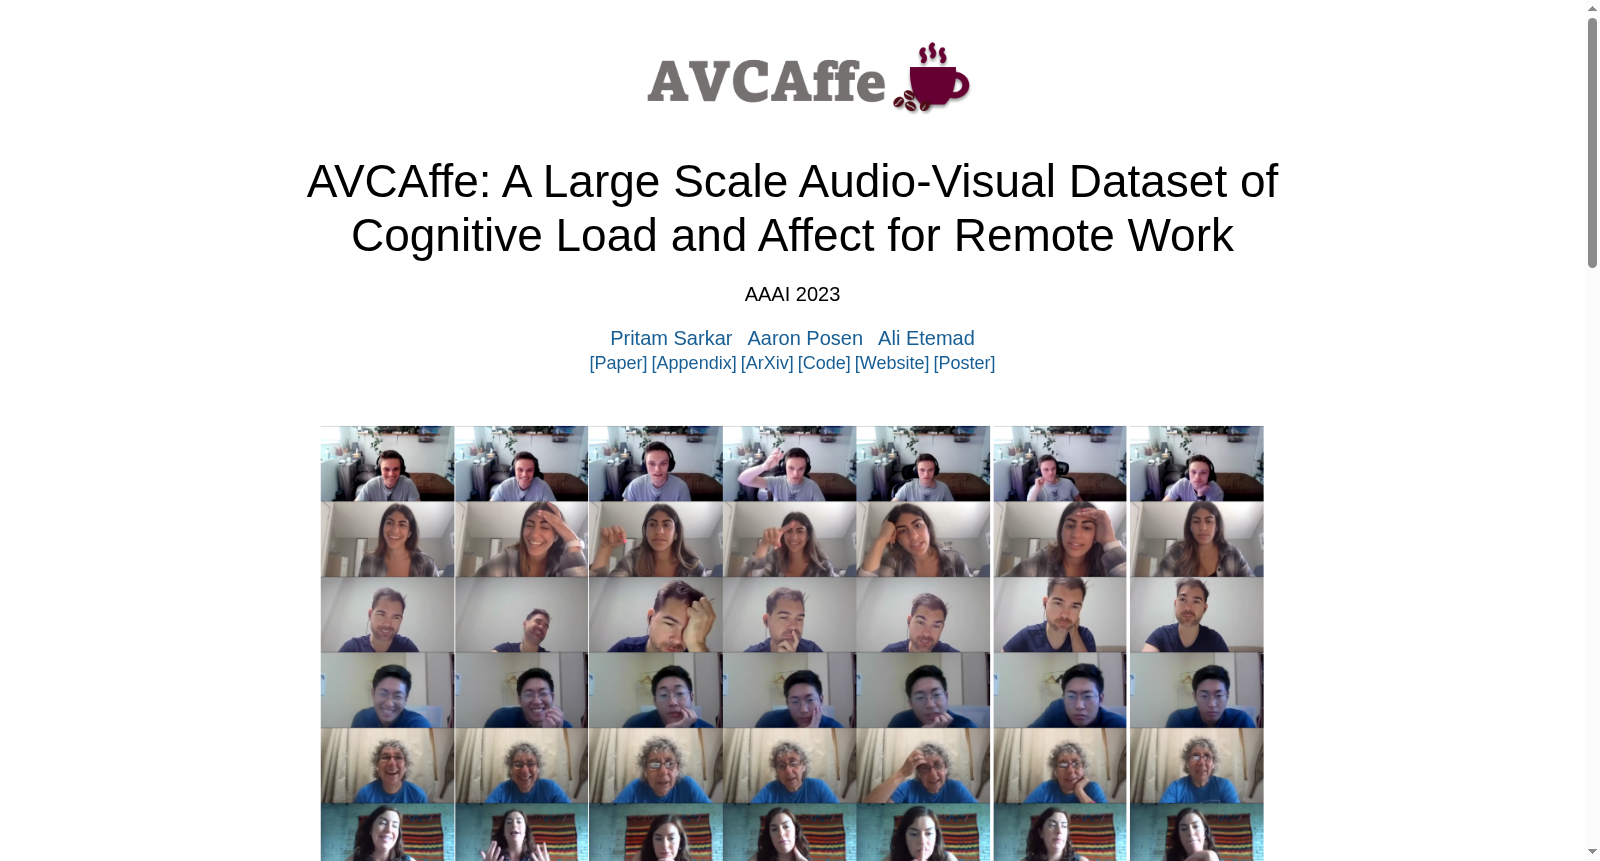
AVCAffe是首个包含认知负荷和情感属性的音频-视觉数据集,通过模拟远程工作场景收集。数据集由女王大学和向量研究所创建,包含106名来自18个不同国家的参与者,年龄跨度为18至57岁,性别比例平衡。数据集总计包含108小时视频,相当于超过58,000个片段,每个片段都附有基于任务的自报告真实标签,用于评估唤醒、价态和多种认知负荷属性。该数据集旨在为深度学习研究社区提供一个挑战性的基准,特别是在远程工作环境中理解和量化认知负荷和情感状态。
AVCAffe is the first audio-visual dataset incorporating cognitive load and affective attributes, collected through simulated remote work scenarios. Developed by Queen's University and the Vector Institute, this dataset includes 106 participants from 18 distinct countries, with an age range of 18 to 57 years and a balanced gender ratio. It contains a total of 108 hours of video, equivalent to over 58,000 segments, each paired with task-based self-reported ground-truth labels for evaluating arousal, valence, and multiple cognitive load attributes. This dataset aims to provide a challenging benchmark for the deep learning research community, particularly for understanding and quantifying cognitive load and affective states in remote work environments.