CerebRM-olmo-3-7b-instruct-sft-list_em-so1_completions
收藏资源简介:
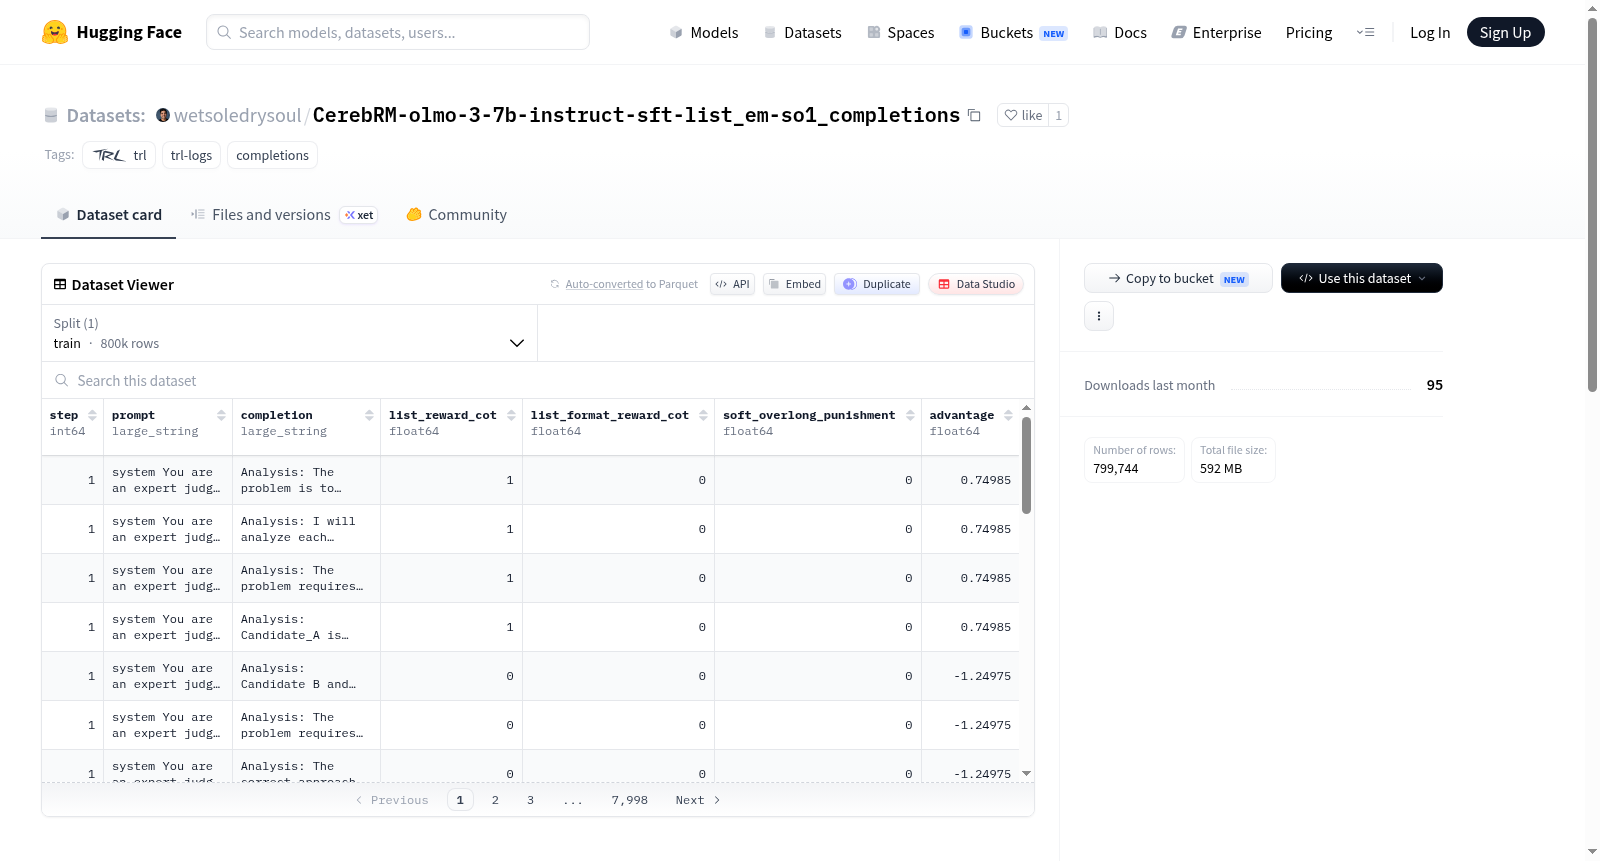
TRL Completion logs数据集是一个专门用于存储和记录使用TRL(Transformer Reinforcement Learning)框架进行模型训练过程中生成的补全内容的数据集。其核心目的是为强化学习训练过程提供详细的日志记录,便于后续的分析、评估和调试。数据以Parquet文件格式存储,每个文件对应训练过程中的一个特定步骤(具体取决于训练配置中的`logging_steps`参数)。每个数据文件包含五个关键字段:`step`(记录当前训练所处的步骤编号)、`prompt`(模型接收到的输入提示文本)、`completion`(模型基于提示生成的输出补全文本)、`<reward_function_name>`(一个或多个奖励函数对该补全结果给出的奖励分数,字段名会根据实际使用的奖励函数动态变化)以及`advantage`(根据奖励计算出的优势值,常用于策略优化)。这种结构化的存储方式使得数据能够被高效地加载和处理,适用于使用Hugging Face Datasets Viewer、Polars或Pandas等工具进行深入分析,例如评估模型在不同训练阶段的生成质量、奖励函数的效果,或进行强化学习训练过程的可视化与问题诊断。
The TRL Completion Logs Dataset is a specialized dataset dedicated to storing and recording the completion outputs generated during model training using the TRL (Transformer Reinforcement Learning) framework. Its core purpose is to provide detailed log records for the reinforcement learning training pipeline, enabling subsequent analysis, evaluation, and debugging. The dataset is stored in Parquet file format, with each file corresponding to a specific training step, where the interval between files is determined by the `logging_steps` parameter in the training configuration. Each data file includes five core fields: `step`, which records the sequential number of the current training step; `prompt`, the input prompt text received by the model; `completion`, the output completion text generated by the model based on the provided prompt; `<reward_function_name>`, the reward score(s) assigned to this completion result by one or more reward functions, with the field name dynamically adjusted based on the actual reward functions in use; and `advantage`, the advantage value calculated from the reward scores, which is commonly used for policy optimization in reinforcement learning. This structured storage method allows for efficient data loading and processing, supporting in-depth analysis via tools such as Hugging Face Datasets Viewer, Polars, or Pandas. Common applications include evaluating the generation quality of the model across different training stages, assessing the performance of reward functions, as well as visualizing the reinforcement learning training process and diagnosing training-related issues.
数据集概述
- 数据集名称: TRL Completion logs
- 数据集来源: 使用
trl库训练过程中生成的模型输出(completions) - 数据格式: Parquet 文件,每个文件对应一个训练步(step)的输出
数据内容
每个 Parquet 文件包含以下列:
- step: 训练步数
- prompt: 生成输出时使用的提示(prompt)
- completion: 模型生成的输出(completion)
- <reward_function_name>: 训练过程中奖励函数为输出分配的奖励值
- advantage: 计算得到的优势值(advantage)
加载方式
-
使用 Datasets 库: python import datasets dataset = datasets.load_dataset("wetsoledrysoul/CerebRM-olmo-3-7b-instruct-sft-list_em-so1_completions")
-
使用 Polars 库: python import polars as pl df = pl.read_parquet("hf://datasets/wetsoledrysoul/CerebRM-olmo-3-7b-instruct-sft-list_em-so1_completions/*.parquet")
特点
- 数据以 Parquet 格式存储,便于使用 Datasets Viewer、Pandas、Polars 等工具加载和分析
- 每个文件对应单一训练步的输出,步数由
logging_steps参数决定